成功した推論の推移アクティビティ
まだ十分なデータがありません

GPT Image 2 は Flatkey の画像生成フローで提供される OpenAI の画像モデルです。/v1/images/generations を使い、送信前に枚数、サイズ、品質、形式、背景、モデレーションを設定します。
プレビューのみです。Flatkey に送信するにはログインしてください。
{
  "model": "gpt-image-2",
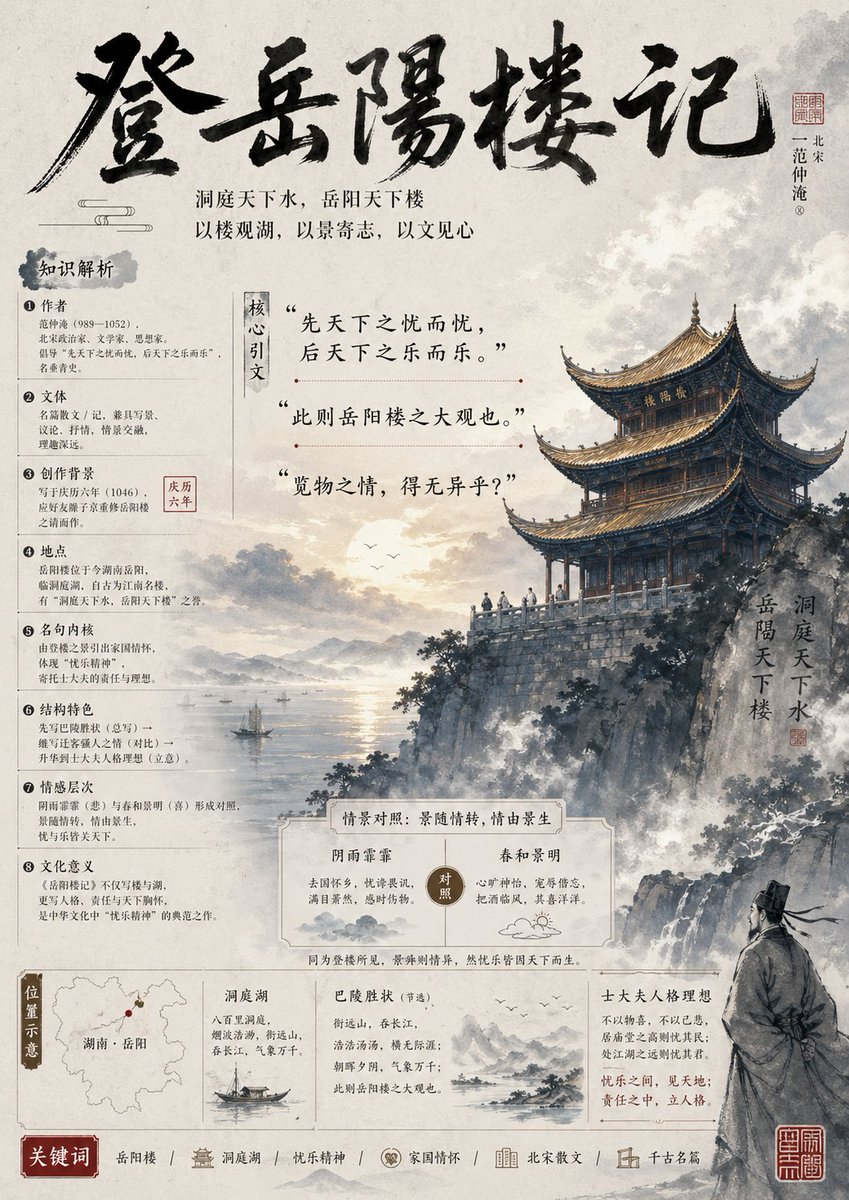
  "prompt": "Goal: Create a vertical ancient-Chinese style literature teaching PPT poster analyzing {argument name=\"work title\" default=\"登岳阳楼记\"}, with an ink-wash historical illustration, dense text-and-image layout, and Song/Yuan classroom handout aesthetics.\n\nCanvas: Portrait 3:4 poster, warm off-white rice paper background with subtle fibers, gray ink stains, light cloud textures, aged edges, and muted black, sepia, red seal, and pale blue-gray tones. High information density but elegant and readable.\n\nLayout: Top third contains a huge expressive black brush-calligraphy title across the page, with a small red seal and a vertical author label at the upper right. Under the title, place two centered subtitle lines in small serif Chinese type: “洞庭天下水,岳阳天下楼” and “以楼观湖,以景寄志,以文见心”. The left column is a structured knowledge-analysis panel; the center contains three large quoted key sentences; the right half is dominated by a dramatic Yueyang Tower illustration above cliffs and Dongting Lake. Bottom third contains comparison cards, a location map, two small literary reference cards, an author-ideal card, and a keyword strip.\n\nMain illustration: Paint Yueyang Tower as a multi-eaved traditional wooden pavilion on a high rocky cliff, facing a vast misty lake at sunset. Include layered mountains, drifting clouds, birds, tiny boats on the lake, water reflections, rugged rocks, pine-like vegetation, and mist rising from the cliff. At lower right, show one robed ancient Chinese scholar seen from behind in gray ink, standing on rocks and looking toward the tower. Add a vertical inscription beside the tower reading “洞庭天下水 / 岳阳天下楼” with a small red seal.\n\nLeft knowledge panel: Use a vertical heading in a gray ink blot reading “知识解析”. Include exactly 8 numbered analysis items, each with a circled number and short Chinese body text: 1 Author, 2 Text genre, 3 Creative background, 4 Place, 5 Famous sentence, 6 Structural features, 7 Emotional layers, 8 Cultural meaning. Add one small red boxed date label near item 3 reading “庆历六年”. Keep all text compact, like a teaching slide.\n\nCenter quote section: Add a narrow vertical label reading “核心引文”. Include exactly 3 large quoted excerpts, separated by thin decorative horizontal rules with small red dots: “先天下之忧而忧,后天下之乐而乐。”; “此则岳阳楼之大观也。”; “览物之情,得无异乎?”.\n\nBottom middle comparison card: Draw a bordered cream card titled “情景对照:景随情转,借由景生”. Inside it, create exactly 2 contrasting columns: left column “阴雨霏霏” describing gloomy rain, waves, and melancholy; right column “春和景明” describing bright spring, calm waves, and joy. Put a round center badge reading “对照”, with small ink cloud and sun doodles.\n\nBottom information row: Create exactly 4 boxed sections from left to right. Section 1 is a “位置示意” location card with a simplified map of Hunan and a red dot labeled “湖南·岳阳”. Section 2 is a Dongting Lake card titled “洞庭湖” with a small sailboat illustration and brief notes about vast lake water and mist. Section 3 is a reference card titled “巴陵胜状(节选)” with a small mountain-water sketch and brief excerpt text. Section 4 is a card titled “士大夫人格理想” explaining concern for the world, responsibility, and moral character.\n\nBottom keyword strip: Add a red label “关键词”, followed by exactly 6 keyword groups separated by slashes and small icons: “岳阳楼”, “洞庭湖”, “忧乐精神”, “家国情怀”, “北宋散文”, “千古名篇”. Add two small red square seal stamps at the bottom right.\n\nTypography and style: Combine bold wild brush calligraphy for the title, neat traditional Chinese serif type for educational notes, and thin line dividers. Use ink-wash realism mixed with PPT infographic layout. Keep all visible text in Chinese, crisp and legible. Avoid modern sans-serif UI styling, neon colors, cartoon effects, watermarks, or English text.",
  "n": 1,
  "size": "1024x1024",
  "quality": "high",
  "output_format": "png",
  "background": "opaque",
  "moderation": "auto"
}
機能
Flatkey の GPT Image 2 に関するリクエストテレメトリは、十分なトラフィックがある場合に表示されます。ベンチマークや品質スコアを推測するものではありません。
API
このセクションは GPT Image 2 への Flatkey の実際のリクエストを反映します。十分なトラフィックが集まるまでデータは報告されません。
料金
GPT-image-2 の料金は Flatkey の現行カタログ単位に従い、OpenAI の直接利用料金を流用しません。サイズ、品質、枚数を選び、編集時は参照画像と維持したい要素を指定してください。
以下は文書化された統合項目です。ベンチマークや品質の約束は推測していません。
/v1/images/generations で新しい画像を生成し、/v1/images/edits で既存画像を編集できます。
画像コンテキストを使い、商品・編集・キャンペーンの主題と構図を保ちます。
1つの企画から正方形・縦長・横長の素材を各チャネル向けに展開します。
記録された品質、形式、背景、モデレーションの挙動に沿って成果物を整えます。
比較
以下は文書化された統合項目です。ベンチマークや品質の約束は推測していません。
| 機能 | GPT Image 1 | GPT Image 2 |
|---|---|---|
| エンドポイント | ここでは不明 | /v1/images/generations; /v1/images/edits |
| サイズ | ここでは不明 | 1024x1024, 1536x1024, 1024x1536, auto |
| 形式 | ここでは不明 | PNG, JPEG, WebP |
| 品質/背景/モデレーション | ここでは不明 | 上記に記載 |
| 画像品質の順位 | 主張なし | 主張なし |
対応ワークフロー、現在の費用、Flatkey の正確なパラメータ契約を確認します。
固定単価がある場合、現在の設定とライブ料金から計算します。
最終料金は送信内容とアカウントグループに従います。トークン・段階料金は固定額にできません。
利用可能なものだけを使用します。公開モデル ID は共通で、入力方式はリクエスト本文で選択します。
テキストから新しい画像を生成します。
gpt-image-2/v1/images/generations参照画像で編集やバリエーションを作ります。
gpt-image-2/v1/images/generationsPlayground と同じモデル設定に基づく値です。
n画像数1–10
既定値: 1sizeサイズ1024x1024 · 1536x1024 · 1024x1536 · auto
既定値: 1024x1024quality品質auto · high · medium · low
既定値: highoutput_format出力形式png · jpeg · webp
既定値: pngbackground背景opaque · auto
既定値: opaquemoderationモデレーションauto · low
既定値: autoimage参照上限4 ファイル
エンドポイント: /v1/images/generationsPlayground と API で同じ契約を使い、検証、残高、状態、結果取得を明示的に処理します。
モデル、プロンプト、参照、出力を検証。
画像リクエストを送信。
結果または非同期タスクを取得。
ファイルとメタデータを保存。
非対応の値や参照数を送信前に拒否します。
キー、残高、制限、グループ料金を分けて処理します。
交換すべきプロンプトや素材を明示します。
task ID を保持し、再試行を制限し、成功扱いしません。
プロンプトライブラリ
具体的な被写体、動作、カメラまたは構図と出力設定から始め、リクエスト項目はプロンプトとは別に指定します。
Image 2 で生成
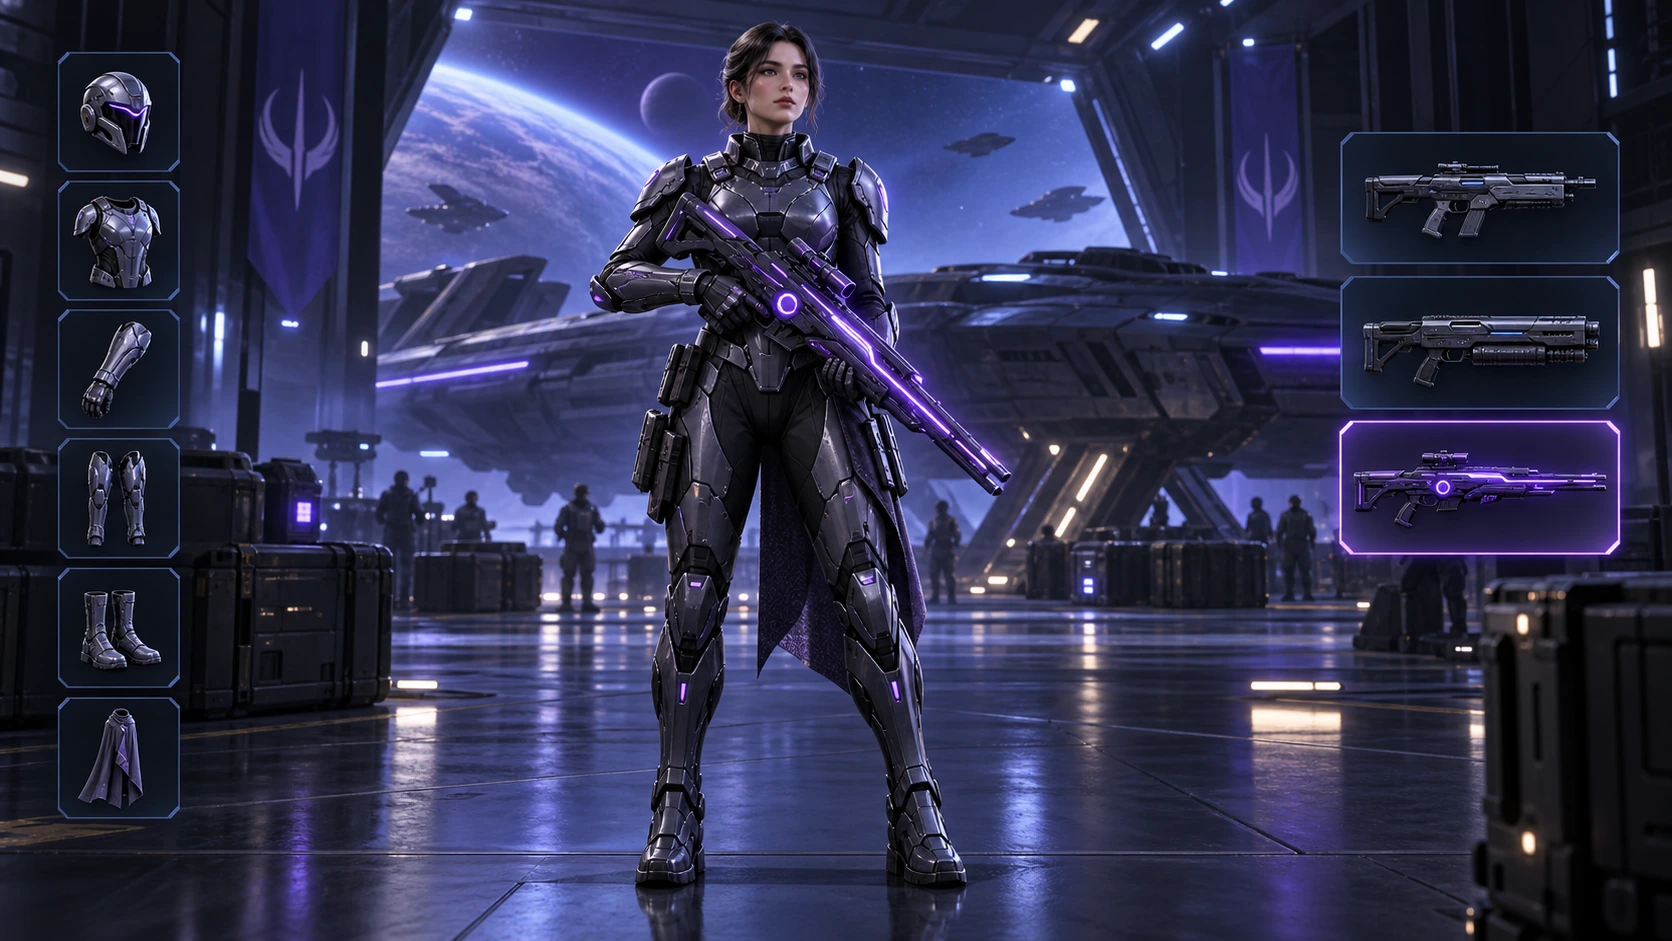
Scene: A 16:9 sci-fi game loadout screen in a blue-purple spaceship hangar. A female armored character stands centered with a glowing violet rifle; armor slots line the left, three weapon slots line the right, and the lower slot is highlighted. Keep the HUD hierarchy, pose, lighting, and equipment geometry fixed for an exact equipment-switch frame. No readable words, logos, invented stats, or watermark. Composition and rendering: Deliver one 16:9 game-interface keyframe. Separate the character, held equipment and HUD into clear depth layers; keep slot spacing and icon scale consistent, with the selected item visually dominant. Preserve the scene-specific game art style. Let material edges catch the existing light without letting interface glow obscure the silhouette. Keep all equipment fully inside the frame. Avoid: warped perspective, malformed anatomy, merged objects, inconsistent shadows, excessive sharpening and watermarks. Follow the scene-specific text and branding restrictions above.
Image 2 で生成
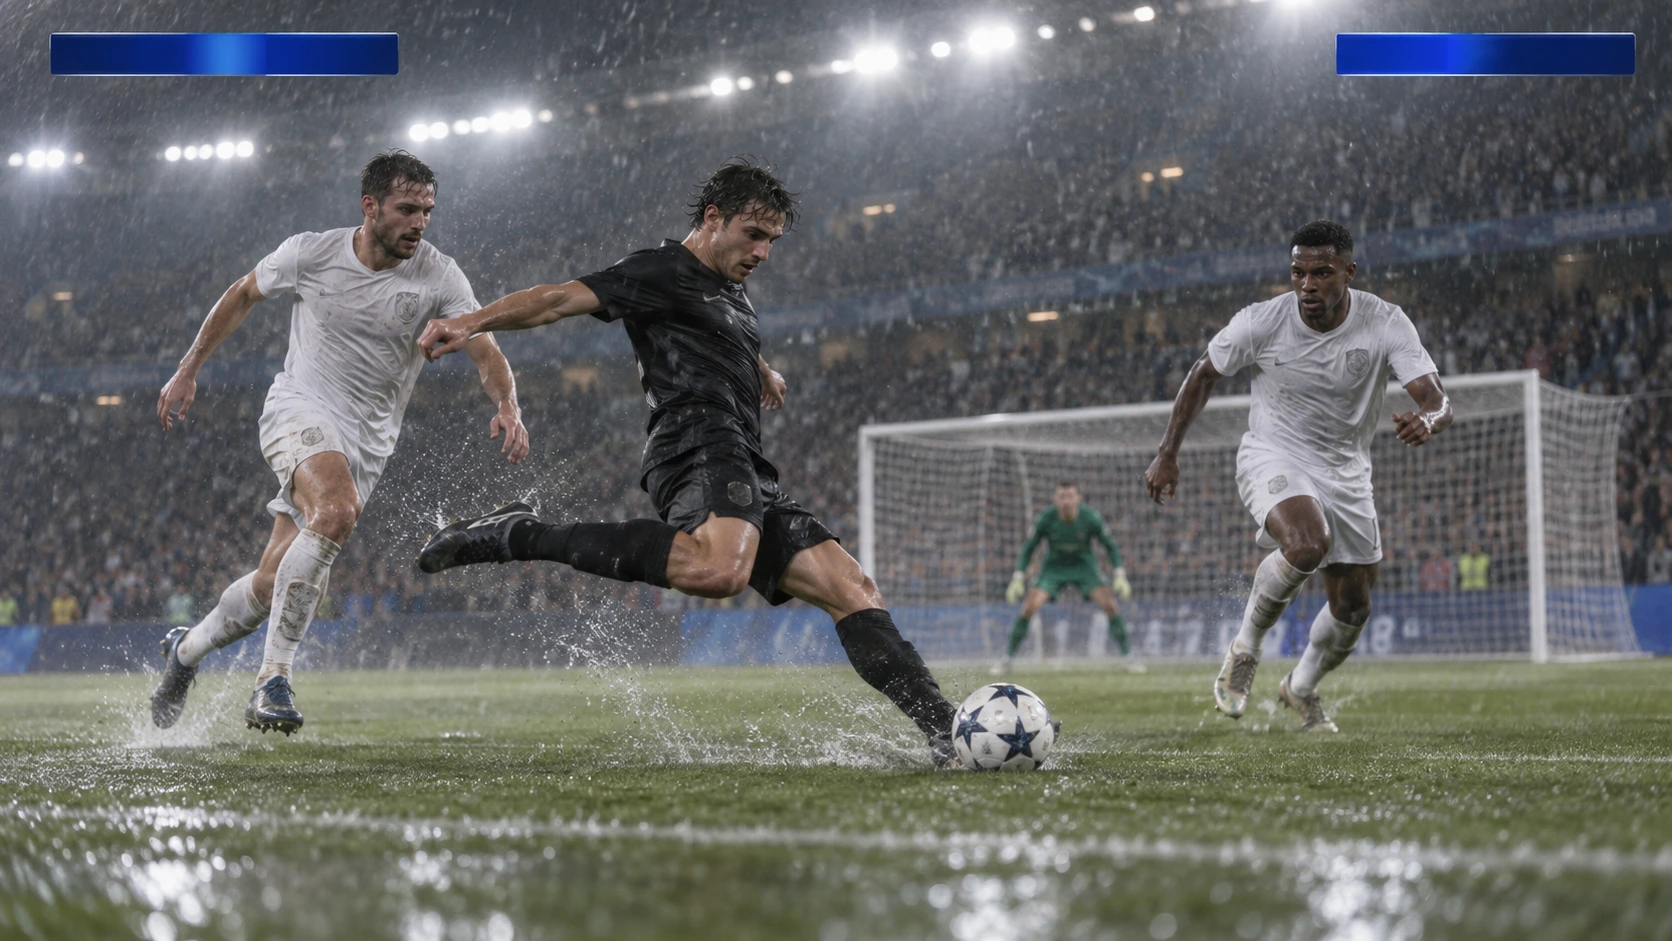
Scene: A rainy night soccer broadcast frame under bright stadium floodlights. A black-uniform player strikes the ball while two white-uniform defenders close in, with the goal and a blurred crowd behind. Keep the broadcast camera angle, blank blue score bars, spray, and motion blur consistent; leave overlays abstract and text-free. No real teams, athletes, logos, or watermark. Composition and rendering: Deliver one 16:9 broadcast still at the decisive instant. Use coherent perspective for the playing surface and equipment, readable separation between competitors, and a softer crowd behind the action. Keep the principal subject sharp, with directional blur limited to fast extremities and spray. Preserve the specified broadcast angle and reserve overlay areas clear of the action. Avoid: warped perspective, malformed anatomy, merged objects, inconsistent shadows, excessive sharpening and watermarks. Follow the scene-specific text and branding restrictions above.
Image 2 で生成
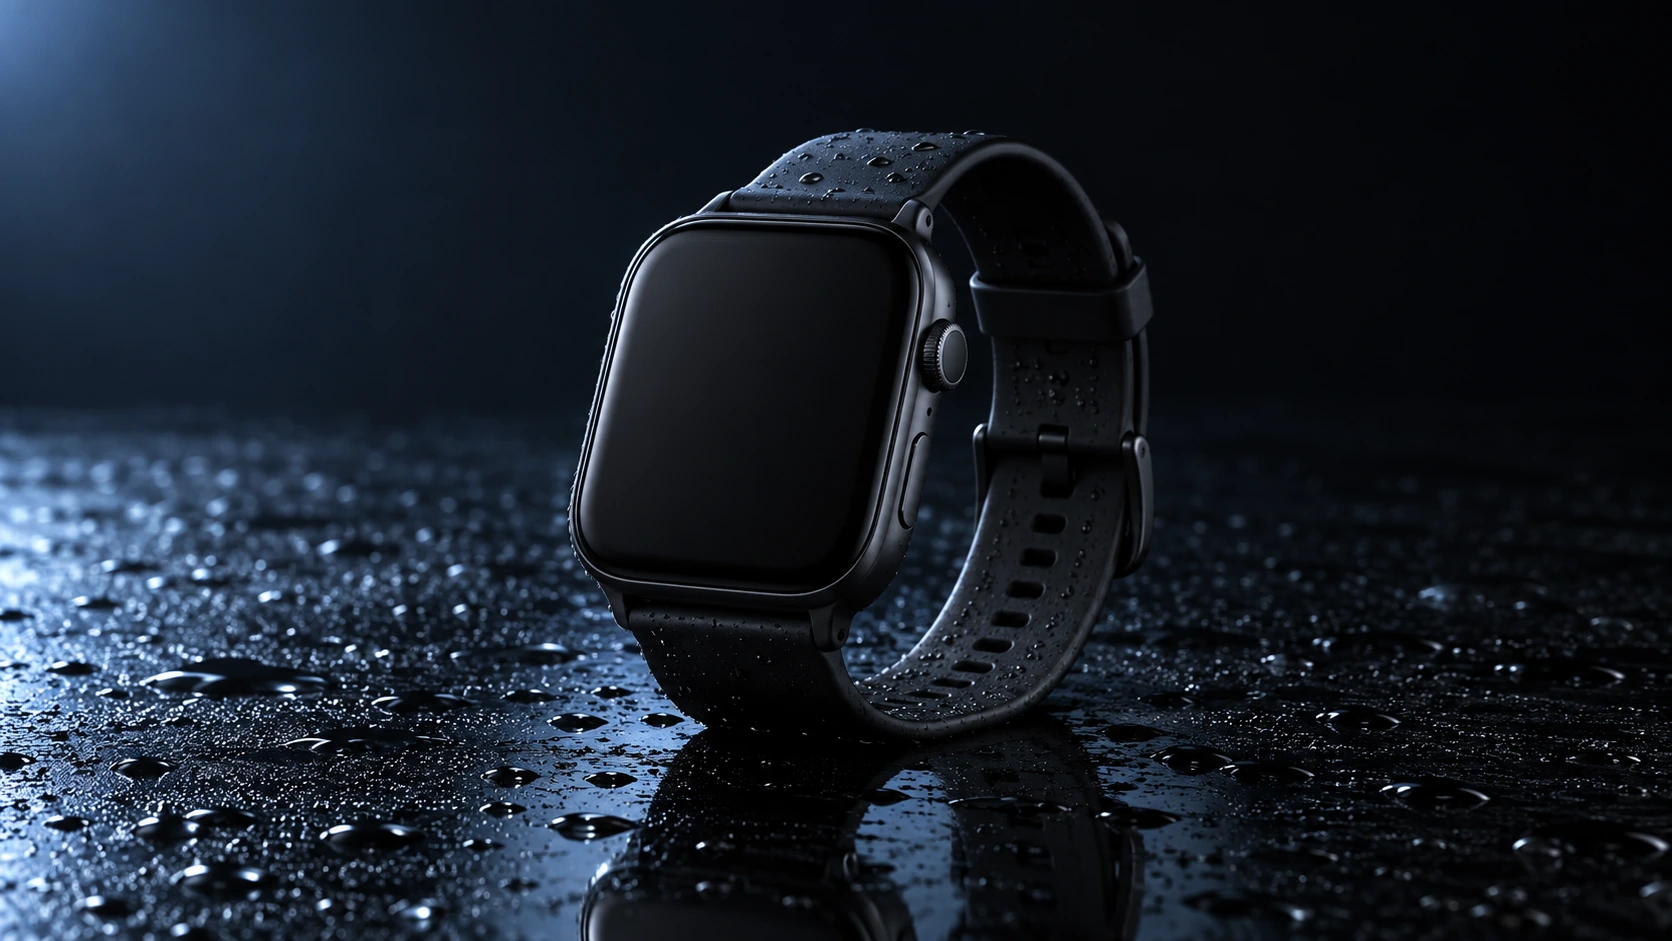
Scene: A closed matte-black square smartwatch with a black strap rests on a wet glossy black tabletop. Water droplets catch a cool blue rim light and a soft reflection sits beneath the watch. Use a low three-quarter product camera and preserve the case, strap, highlights, and empty dark background. No readable branding, extra products, hands, or watermark. Composition and rendering: Deliver one 16:9 commercial product still. Keep the complete product silhouette inside generous crop-safe margins. Resolve edges, seams and material transitions precisely; shape highlights to describe volume without clipping bright surfaces or crushing dark details. Align reflections with the object and light source. Retain the stated camera angle and existing negative space; add no decorative props. Avoid: warped perspective, malformed anatomy, merged objects, inconsistent shadows, excessive sharpening and watermarks. Follow the scene-specific text and branding restrictions above.
Image 2 で生成
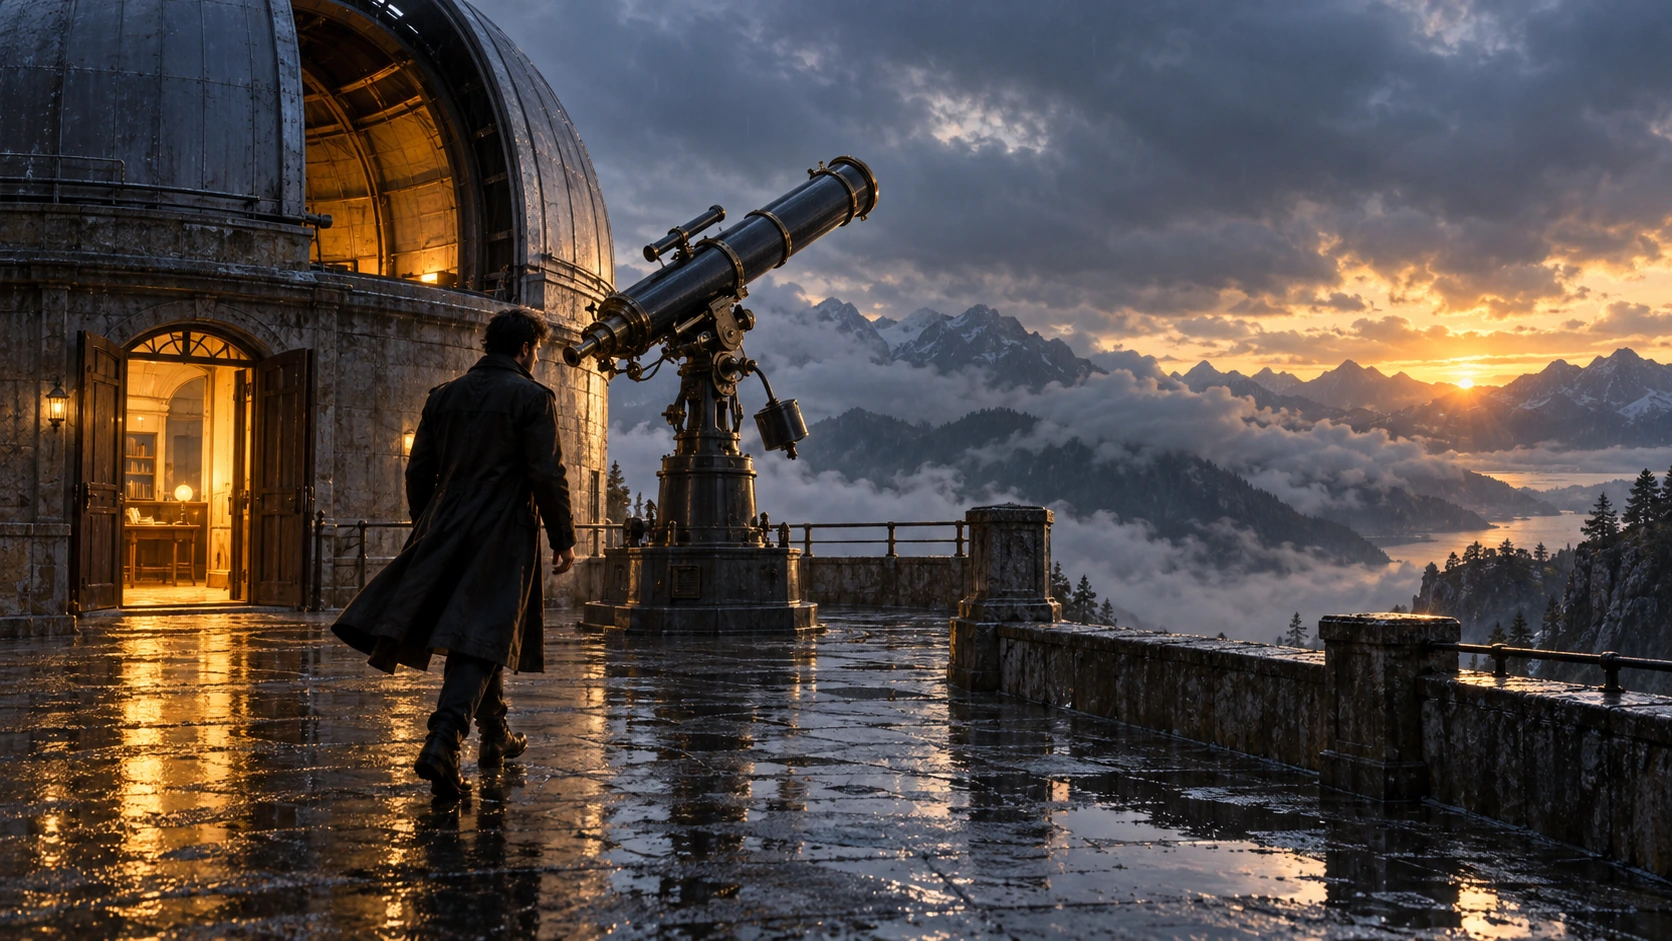
Scene: On a rain-soaked observatory roof at sunrise, a lone figure in a long dark coat walks toward a large telescope beside an open dome. Wet stone reflects the warm doorway light; cloud-covered mountains sit beyond. Hold the screen direction and end on the telescope and figure in the same wide composition. No readable text, logos, or watermark. Composition and rendering: Deliver one 16:9 storyboard keyframe, not a collage or an action sequence. Separate foreground, character plane and background through the existing light and atmospheric depth. Keep the stated pose and eyelines readable, and retain environmental landmarks for continuity. Match the described photographic, illustrated or puppet medium; give fabric and surfaces texture appropriate to that medium. Avoid: warped perspective, malformed anatomy, merged objects, inconsistent shadows, excessive sharpening and watermarks. Follow the scene-specific text and branding restrictions above.
Image 2 で生成
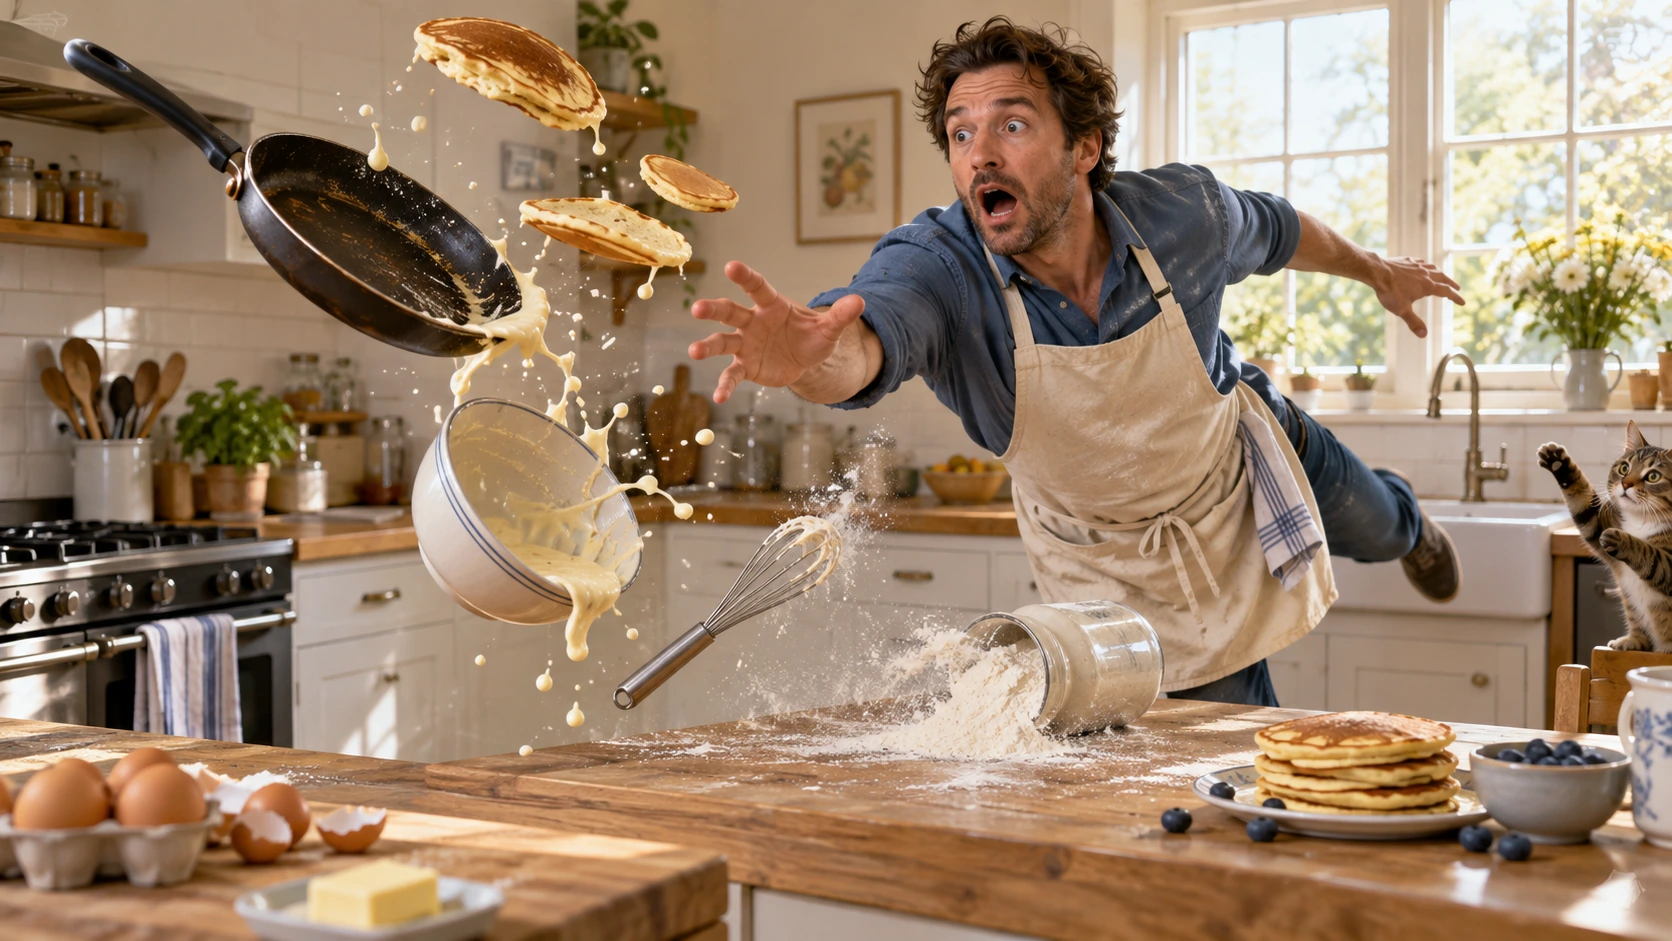
Scene: In a bright home kitchen, a surprised cook in a blue shirt and cream apron reaches toward pancakes, a frying pan, flour, bowl, and whisk suspended midair. Freeze the comic cause-and-effect moment with believable weight, warm daylight, and a clear path for each object. No injury, logos, readable words, or watermark. Composition and rendering: Deliver one 16:9 physical-comedy still at the described instant. Make the cause of the gag readable through body balance, grip and object spacing. Separate the reaction from the airborne props; retain believable gravity and contact points. Keep the face and important props sharp, with only restrained directional blur on fast edges. Preserve the stated lighting and room or stage layout. Avoid: warped perspective, malformed anatomy, merged objects, inconsistent shadows, excessive sharpening and watermarks. Follow the scene-specific text and branding restrictions above.
Image 2 で生成
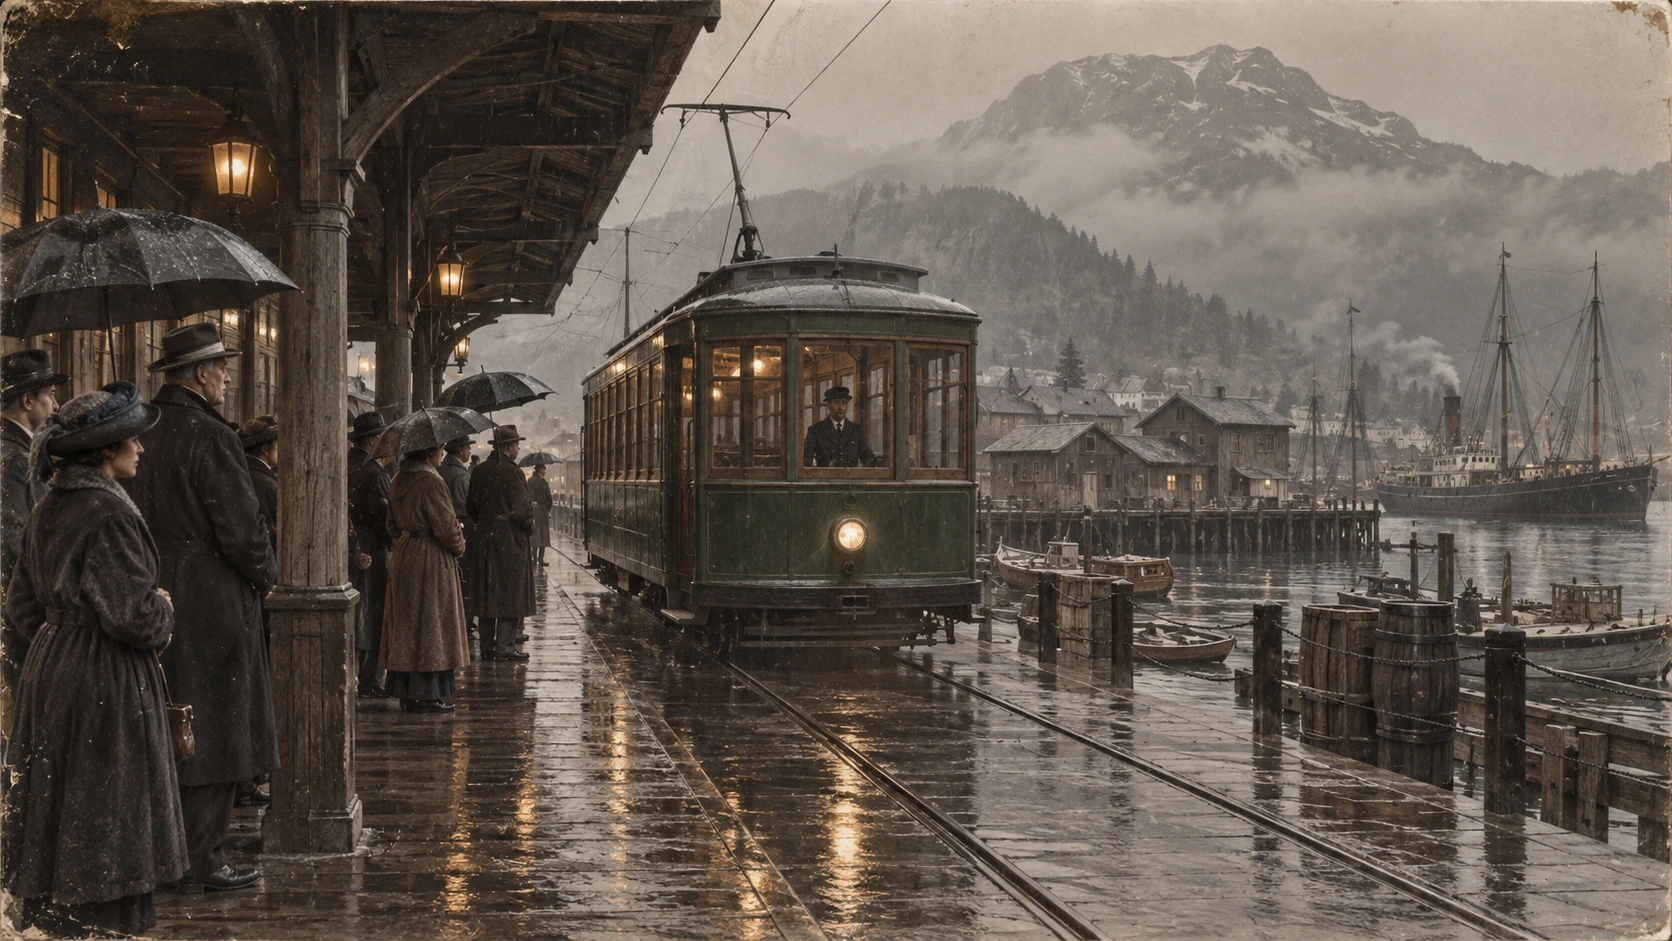
Scene: A rainy period harbor platform shelters people in era-appropriate coats and umbrellas as a vintage green tram arrives on wet tracks. Wooden waterfront buildings and misty mountains sit behind the reflections. Preserve the historical clothing, tram shape, rain direction, and stable wide composition; no readable signage, logos, or watermark. Composition and restoration: Deliver one 16:9 archival-style still. Preserve the original framing, period-specific construction and restrained tonal range; retain monochrome, sepia or faded color as described. Recover modest detail in faces, clothing and architecture without synthetic sharpening. Keep fine grain and authentic aging consistent across the frame; repair damage without replacing historical features. Avoid: warped perspective, malformed anatomy, merged objects, inconsistent shadows, excessive sharpening and watermarks. Follow the scene-specific text and branding restrictions above.
Flatkey を選ぶ理由
テストから本番へ移行する間も、GPT Image 2 の事実、リクエスト項目、料金の境界を確認できます。
コンソールに渡す前に n、size、quality、output format、background、moderation を設定します。
GPT Image 2 の入力・出力・キャッシュの各項目を確認し、見出しの価格を一律料金とみなさないでください。
商品、広告、絵コンテの例を編集可能なプロンプトの出発点として使います。
確認されていない事実について、透明な出力、無料生成、固定の画像単価を約束しません。
API
同じキーとモデルカタログで4つの方法から選べます。実行可能な例を確認してください。
curl https://router.flatkey.ai/v1/images/generations \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer sk-***" \
  -d '{"model":"gpt-image-2","prompt":"GPT-image-2で高品質な商品画像を作成:整理された構図、正確な照明、被写体への強いフォーカス、リアルなディテール。","n":1,"size":"1024x1024","quality":"high","output_format":"png","background":"opaque","moderation":"auto"}'
よくある質問
料金、互換性、制限、モデル固有のリクエスト情報。