
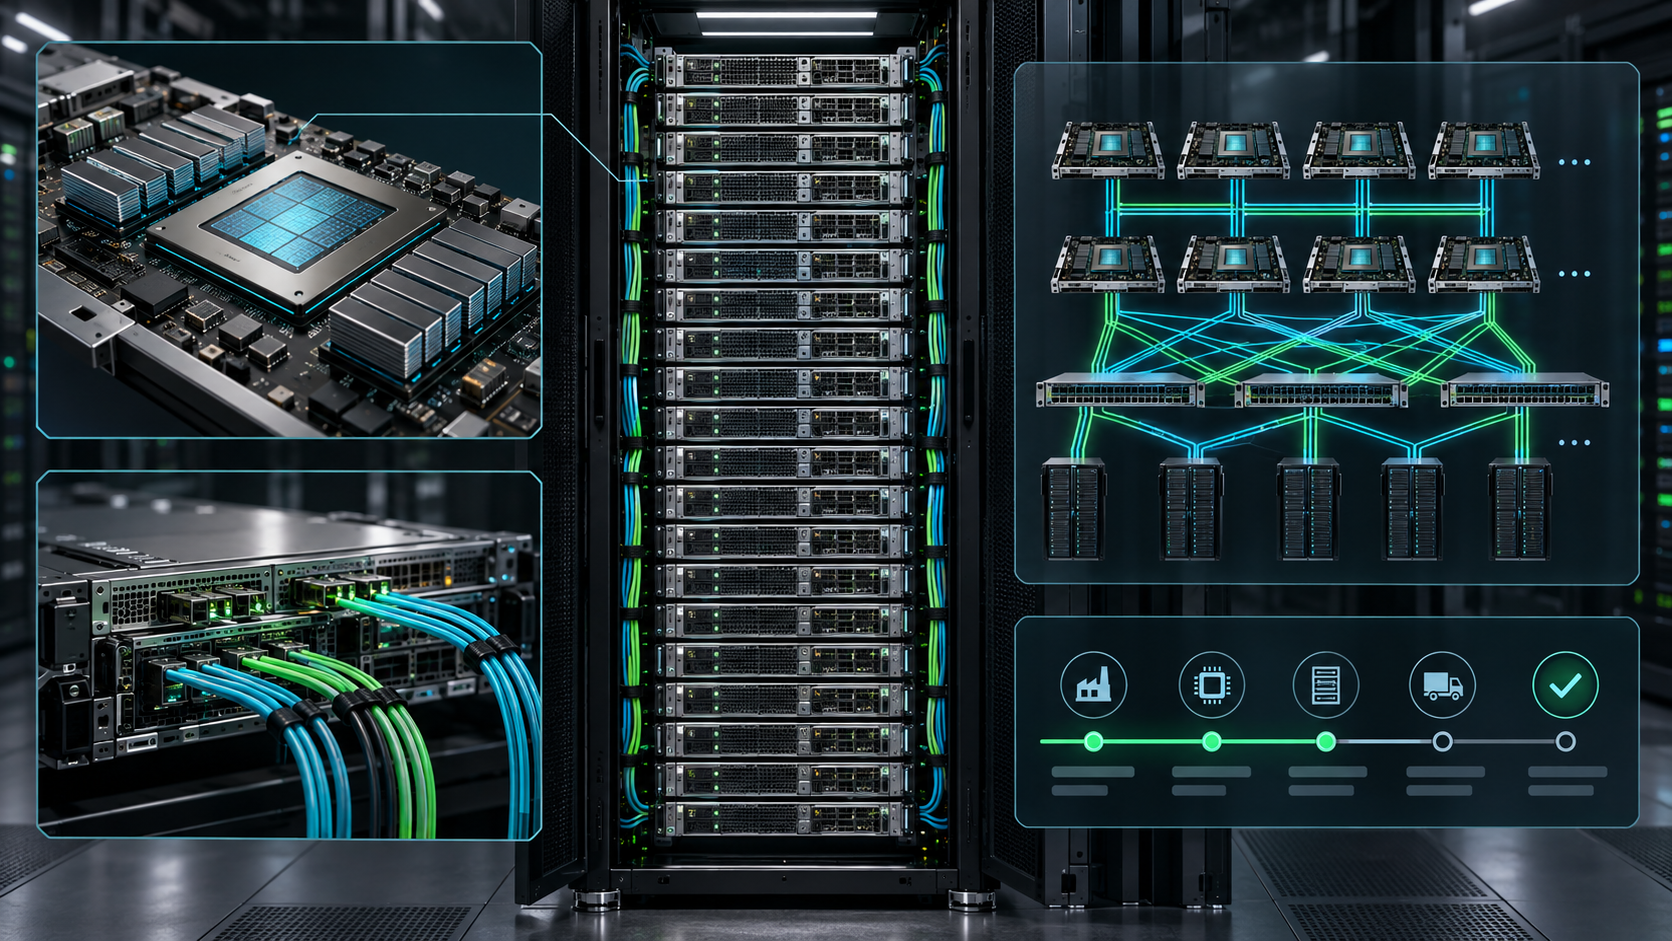
The AMD MI455X is the accelerator to watch if your GPU roadmap depends on open rack-scale AI infrastructure instead of a single PCIe card or a one-off cloud instance. AMD positions the Instinct MI455X as the GPU inside the Helios rack platform: a 72-GPU, HBM4-based system aimed at large training, post-training, and high-throughput inference.
For buyers, the useful question is not only "what are the AMD MI455X specs?" It is also: how much HBM4 memory does the rack expose, what bandwidth figure should you model, when can you actually get capacity, and is vLLM enabled on AMD Instinct MI455X GPUs in a production image?
This tracker summarizes the public record as of October 13, 2026 and separates AMD-confirmed claims from buyer assumptions.
Quick Answer: What Is AMD MI455X?
The AMD MI455X is an AMD Instinct data-center GPU based on AMD's CDNA Next architecture. AMD's public product page lists 432 GB of HBM4 memory and 23.3 TB/s peak memory bandwidth per MI455X accelerator. In the AMD Helios rack, 72 MI455X GPUs combine for roughly 31 TB of HBM4 memory and about 1.67 PB/s aggregate GPU memory bandwidth.
AMD has described Helios as a rack-scale platform for open AI infrastructure rather than a standalone accelerator SKU. That matters because most teams will evaluate AMD MI455X through cloud capacity, rack reservations, managed clusters, and software images, not by buying one loose GPU.
AMD MI455X Tracker
| Field | Current Public Status | Buyer Takeaway |
|---|---|---|
| GPU | AMD Instinct MI455X | Treat it as the flagship MI400-series accelerator for Helios planning. |
| Architecture | AMD CDNA Next | New-generation AMD AI architecture; expect software stack validation to matter. |
| Memory capacity | 432 GB HBM4 per GPU | Large headroom for KV cache, long context, MoE experts, and large-model serving. |
| Memory bandwidth | 23.3 TB/s peak per GPU | Use this current AMD figure when modeling bandwidth, not older pre-brief numbers. |
| Rack platform | AMD Helios | The practical procurement unit is likely rack or cluster capacity. |
| GPUs per Helios rack | 72 MI455X GPUs | Comparable decisions should be made at rack topology level, not only GPU-card level. |
| Rack memory | About 31 TB HBM4 | Useful for large-model inference, post-training, and multi-tenant scheduling models. |
| Rack memory bandwidth | About 1.67 PB/s aggregate | Bandwidth-sensitive workloads should request real tokens/sec and step-time benchmarks. |
| Software stack | ROCm, AMD developer stack, and framework support | vLLM can run on AMD ROCm platforms, but MI455X production images still need provider validation. |
| Availability | AMD has positioned MI400/Helios for the 2026 infrastructure cycle | Real availability depends on provider inventory, region, preview programs, and reservation terms. |
AMD MI455X Architecture: Why CDNA Next Matters
AMD MI455X is not just an incremental memory bump for teams that already run MI300X. It belongs to AMD's next Instinct generation, and the surrounding Helios system changes the procurement conversation from "which GPU instance should we rent?" to "which rack topology, software stack, and provider commitment can pass our workload tests?"
The architecture questions that matter most are practical:
- Memory per GPU: 432 GB HBM4 changes how much model state, KV cache, and batching headroom can stay close to the accelerator.
- Memory bandwidth: 23.3 TB/s peak bandwidth per AMD MI455X is the spec to benchmark for memory-bound inference and post-training workloads.
- Scale-up topology: Helios puts 72 MI455X GPUs in one rack-scale system, so placement, interconnect, failure domains, and scheduler awareness all matter.
- Software maturity: CDNA Next capacity is only useful when kernels, ROCm images, vLLM/SGLang support, observability, and orchestration are stable for your model.
- Provider packaging: Cloud buyers may see full racks, partial racks, private clusters, managed inference, or benchmark previews before ordinary on-demand instances.
That is why the AMD MI455X should sit next to your GPU cluster TCO model, not just inside a raw accelerator comparison table.
AMD MI455X Specs: What Is Confirmed
These are the core figures to put in a planning sheet today:
| Spec | AMD MI455X Public Figure |
|---|---|
| Product family | AMD Instinct MI400 series |
| GPU | AMD Instinct MI455X |
| Architecture | AMD CDNA Next |
| Memory | 432 GB HBM4 |
| Peak memory bandwidth | 23.3 TB/s |
| Primary platform | AMD Helios rack |
| Helios GPU count | 72 AMD Instinct MI455X GPUs |
| Helios memory | About 31 TB HBM4 |
| Helios aggregate memory bandwidth | About 1.67 PB/s, based on 72 x 23.3 TB/s |
The secondary keyword "amd mi455x memory bandwidth" is especially important because some early discussion can lag behind current product-page numbers. If a provider quote, slide deck, or benchmark says 19.6 TB/s, ask for the source date and whether the quote reflects current MI455X product guidance.
AMD Helios: The Rack Is the Product
AMD Helios is the rack-scale platform built around the AMD MI455X. For infrastructure buyers, this means the most important specs are not only per-GPU figures. The rack has to be evaluated as a system:
| Helios Planning Area | What to Ask |
|---|---|
| Rack topology | Is the provider offering a full Helios rack, a partitioned rack, or a higher-level managed service? |
| GPU placement | Can your job reserve contiguous MI455X topology, or will placement be fragmented? |
| Memory visibility | How much of the nominal 31 TB HBM4 is usable after framework, tensor parallelism, and scheduler overhead? |
| Network fabric | What scale-up and scale-out network is exposed, and what counters are visible to customers? |
| Storage path | Can checkpoint, dataset, and embedding storage feed the rack without creating idle GPU time? |
| Failure domain | What happens when one tray, NIC, switch, or power/cooling component fails mid-run? |
| Software image | Which ROCm, Linux, Kubernetes, Slurm, vLLM, SGLang, PyTorch, and monitoring versions are supported? |
| Acceptance test | Can you run your own model, sequence lengths, batch mix, and SLOs before committing? |
Helios should also be compared with competing rack-scale systems and with a managed model API baseline. If your product only needs reliable model outputs and not direct hardware control, read this alongside GPU cloud vs model API before reserving rack capacity.
Why HBM4 Is the AMD MI455X Spec to Watch
The query "amd mi455x memory capacity hbm4" exists because memory is now one of the main buying filters for AI infrastructure. HBM4 affects both capacity and speed:
- Long-context inference: More HBM gives larger KV cache headroom before batch size or context length has to be cut.
- Large MoE models: More local memory helps with active experts, routing state, and less aggressive offload.
- Post-training: SFT, preference optimization, and reinforcement learning pipelines can be limited by activation and optimizer memory.
- Tenant density: More memory can support more model variants, replicas, or customers per reserved topology, if isolation is engineered well.
- Cost per accepted output: Larger batch sizes only help if latency, quality, retries, and failure recovery stay inside the product SLO.
Do not buy on memory capacity alone. Ask providers for workload-level evidence: tokens/sec at your context length, time to first token, batch latency, model quality acceptance rate, queue time, failed-run cost, and operational recovery time.
Is vLLM Enabled on AMD Instinct MI455X GPUs?
The precise answer is: vLLM is supported on AMD ROCm platforms, and AMD positions its AI software stack around open framework support, but you should verify MI455X-specific vLLM enablement with the actual cloud provider image before treating it as production-ready.
That distinction matters. "ROCm supports vLLM" is not the same as "this MI455X region, this driver, this kernel set, this container image, this model, and this serving topology are all production-supported by my provider."
Use this vLLM validation checklist:
- Confirm the provider's ROCm version and whether MI455X is listed in the image release notes.
- Ask whether vLLM is preinstalled, provider-supported, or community-supported.
- Run your target model with the same quantization, tensor parallelism, sequence length, and concurrency you expect in production.
- Measure prefill, decode, time to first token, throughput, error rate, and GPU memory pressure.
- Check whether fallback serving options such as SGLang, Triton, or provider-managed inference are available.
- Verify upgrade policy, rollback procedure, observability, and kernel compatibility before signing a reserved-capacity contract.
If the provider cannot answer those questions yet, treat AMD MI455X vLLM support as an evaluation item rather than a finished production claim.
AMD MI455X Release Date and Availability Tracker
Search demand around "amd mi455x release date" usually means buyers want to know when they can rent, benchmark, or reserve capacity. The clean way to track this is by milestone rather than a single date:
| Milestone | What Is Publicly Useful | What Buyers Still Need |
|---|---|---|
| Product disclosure | AMD has publicly listed MI455X product specs and Helios platform details. | Confirm spec revision date in provider quotes. |
| Software enablement | ROCm and AMD AI software support are central to the platform story. | Confirm MI455X-specific image support, framework versions, and vLLM/SGLang status. |
| System availability | AMD positions Helios for the 2026 AI infrastructure cycle. | Confirm first provider regions, allocation model, and capacity windows. |
| Cloud preview | Early capacity may appear as benchmark access or private preview. | Ask for representative topology, not isolated marketing benchmarks. |
| General rental | On-demand capacity may lag system-level availability. | Compare on-demand, reserved, private cluster, and managed-service terms. |
The practical rule: do not equate AMD's hardware roadmap with your team's available capacity. Provider inventory, region, power, cooling, networking, software images, and commercial terms all determine when AMD MI455X capacity is usable.
When to Wait for AMD MI455X
Waiting for AMD MI455X or Helios capacity can make sense when:
- Your workload is memory-bound and 432 GB HBM4 per GPU changes the economics.
- You need rack-scale control for training, post-training, large MoE inference, or custom serving.
- You can benchmark on production-shaped prompts, context windows, and concurrency.
- Your team is ready to operate ROCm images, scheduler policies, network counters, storage, and failure recovery.
- Your procurement window can tolerate provider preview, allocation, and region uncertainty.
Waiting is risky when:
- You need user-facing production capacity now.
- Your workload can use hosted models through an API without direct GPU control.
- You do not have enough utilization to amortize a reserved rack or private cluster.
- Your main bottleneck is routing, reliability, evaluation, spend attribution, or user workflow, not raw accelerator access.
- You cannot run an acceptance benchmark before making a term commitment.
For many teams, the pragmatic path is hybrid: use model APIs for production now, benchmark MI455X or Helios when capacity appears, and reserve hardware only after it beats your model/API baseline on cost per accepted output.
Provider Questions for AMD MI455X Capacity
Before reserving AMD MI455X capacity, send providers this checklist:
- Are you offering AMD MI455X, AMD Helios, or a different MI400-series configuration?
- Is the capacity full rack, partial rack, private cluster, managed inference, preview, or on-demand instance?
- Which regions have physical inventory, and what is the allocation window?
- What ROCm, kernel, driver, firmware, Slurm/Kubernetes, PyTorch, vLLM, and SGLang versions are supported?
- Can we run our model, prompt mix, context length, concurrency, and evaluation harness before committing?
- What are the queue-time, retry, failed-job, egress, storage, and support costs?
- What telemetry is exposed for GPU utilization, HBM pressure, memory bandwidth, network counters, and job failures?
- What happens if public specs, delivery timing, or benchmark results change after contract signature?
- What security controls exist for tenant isolation, data handling, and audit evidence?
- How does pricing compare with current GPU rental prices, serverless GPU vs dedicated GPU, and managed model/API alternatives?
Flatkey Take: Track MI455X, but Keep a Production Baseline
The AMD MI455X is important because it gives buyers a serious HBM4 and rack-scale alternative for the next AI infrastructure cycle. It should be tracked by anyone planning large-model inference, post-training, or private AI factory capacity.
It is not automatically the right first move for every AI product team. If your product needs reliable access to model outputs, cost visibility, fallback routing, and one billing surface, a managed model/API layer can keep production moving while MI455X supply and software images mature.
Flatkey is built for that path: one key, one balance, and routing across official model and tool APIs. Use Flatkey as the production baseline in your AMD MI455X analysis so you compare rack-scale hardware against a working deployment path, not against a blank spreadsheet.
FAQ
What is AMD MI455X?
AMD MI455X is an AMD Instinct MI400-series data-center accelerator based on AMD CDNA Next architecture. AMD lists 432 GB HBM4 memory and 23.3 TB/s peak memory bandwidth for the GPU.
What is AMD Helios?
AMD Helios is a rack-scale AI platform built around 72 AMD Instinct MI455X GPUs. At that scale, the rack exposes about 31 TB of HBM4 memory and about 1.67 PB/s aggregate GPU memory bandwidth.
What is the AMD MI455X memory capacity?
The public AMD MI455X memory capacity is 432 GB of HBM4 per GPU. A 72-GPU Helios rack therefore reaches roughly 31 TB of HBM4 memory before practical software and scheduling overhead.
What is the AMD MI455X memory bandwidth?
AMD's current public MI455X figure is 23.3 TB/s peak memory bandwidth per GPU. For a 72-GPU Helios rack, that implies about 1.67 PB/s aggregate memory bandwidth.
When is the AMD MI455X release date?
AMD has publicly disclosed MI455X and positioned Helios for the 2026 AI infrastructure cycle. Buyers should track provider-specific inventory, region, preview access, software images, and reservation terms rather than assuming a single universal rental date.
Is vLLM enabled on AMD Instinct MI455X GPUs?
vLLM supports AMD ROCm platforms, but MI455X-specific production enablement depends on the provider image, ROCm version, kernels, model, serving configuration, and support policy. Verify it with the provider before committing production traffic.
Sources Checked
- AMD Instinct MI455X product page: https://www.amd.com/en/products/accelerators/instinct/mi400/mi455x.html
- AMD Helios solution page: https://www.amd.com/en/solutions/ai/helios.html
- AMD Newsroom, AI roadmap and open AI infrastructure announcements: https://www.amd.com/en/newsroom/press-releases/2025-6-12-amd-unveils-ai-roadmap-and-comprehensive-full-stack-open-ai-infrastructure-solutions.html
- AMD ROCm vLLM documentation: https://rocm.docs.amd.com/en/latest/how-to/rocm-for-ai/inference-optimization/vllm.html


