
Model and Modality Playbooks
Latest articles in Model and Modality Playbooks.
Grok vs Gemini (October 2026): Which AI Should You Use?
Gemini wins on value, Google integration, research, and video; Grok wins on real-time X content and bundles with X Premium. Compare October 2026 plans, tasks, and API prices, then test both with code.

AI Video Generator API: Access, Pricing, Integration, and Production Guide
A practical guide to choosing, pricing, integrating, and operating an AI video generation API with asynchronous jobs and measurable cost controls.

Perplexity AI API: Access, Pricing, Integration, and Production Guide
A source-backed guide to choosing the right Perplexity API surface, integrating it correctly, estimating cost, and operating it safely in production.

Ollama OpenAI Compatible API: Access, Pricing, Integration, and Production Guide
Use the Ollama OpenAI compatible API locally or in the cloud. Compare endpoints and pricing, configure the OpenAI SDK, and ship with production guardrails.
Best LLMs for Coding in 2026: A Developer's Decision Guide
A task-based guide to selecting coding LLMs with a 20-case evaluation, hard gates, a scorecard, and a safe multi-model comparison workflow.

Claude Sonnet API (2026): Model IDs, Setup, Limits, and Code for Sonnet 5.5
Everything to call Claude Sonnet 5.5 through the API: model IDs, keys, working code, effort and thinking settings, rate limits, costs, and migration fixes.
Speculative Decoding for LLM Inference: Throughput Gains and Tradeoffs
A practical guide to speculative decoding for LLM inference: how it works, when it helps, how EAGLE and Medusa differ, and what to benchmark before rollout.
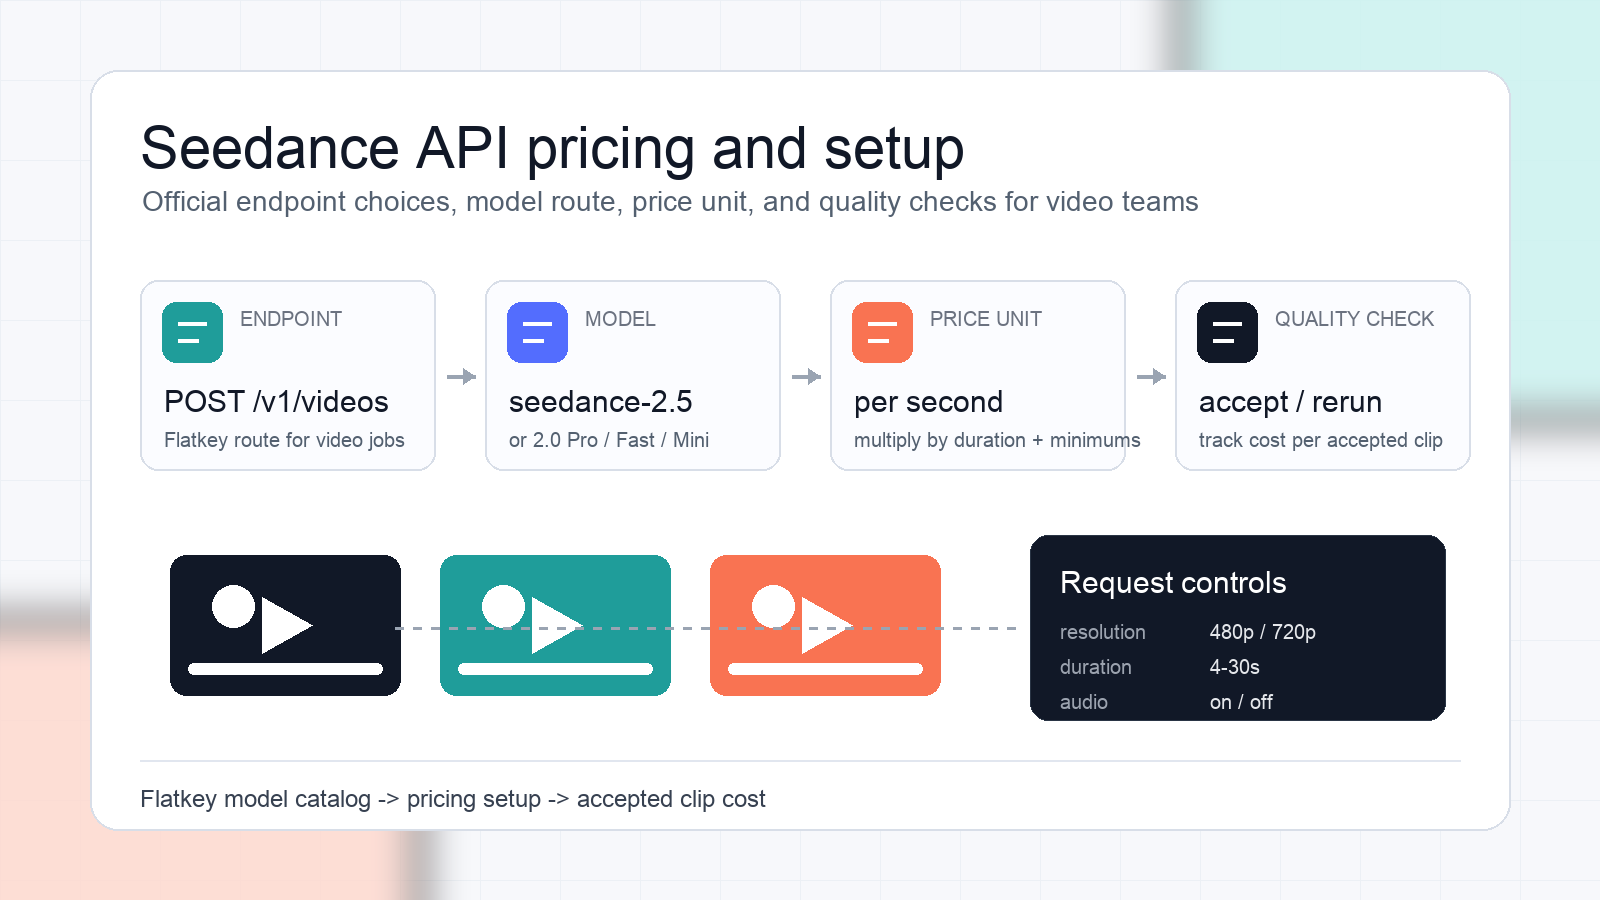
Seedance API: Pricing, Quality, and Setup for Official Endpoints
Compare official Seedance API endpoint options, Flatkey per-second pricing, setup steps, and quality checks for video generation teams.
Llama API (2026): Where You Can Still Call Llama, Prices, and Setup
What happened to the official Meta Llama API, which providers still serve Llama 3.3 and Llama 4 in October 2026, their prices, copy-paste OpenAI SDK code, and self-hosting trade-offs.
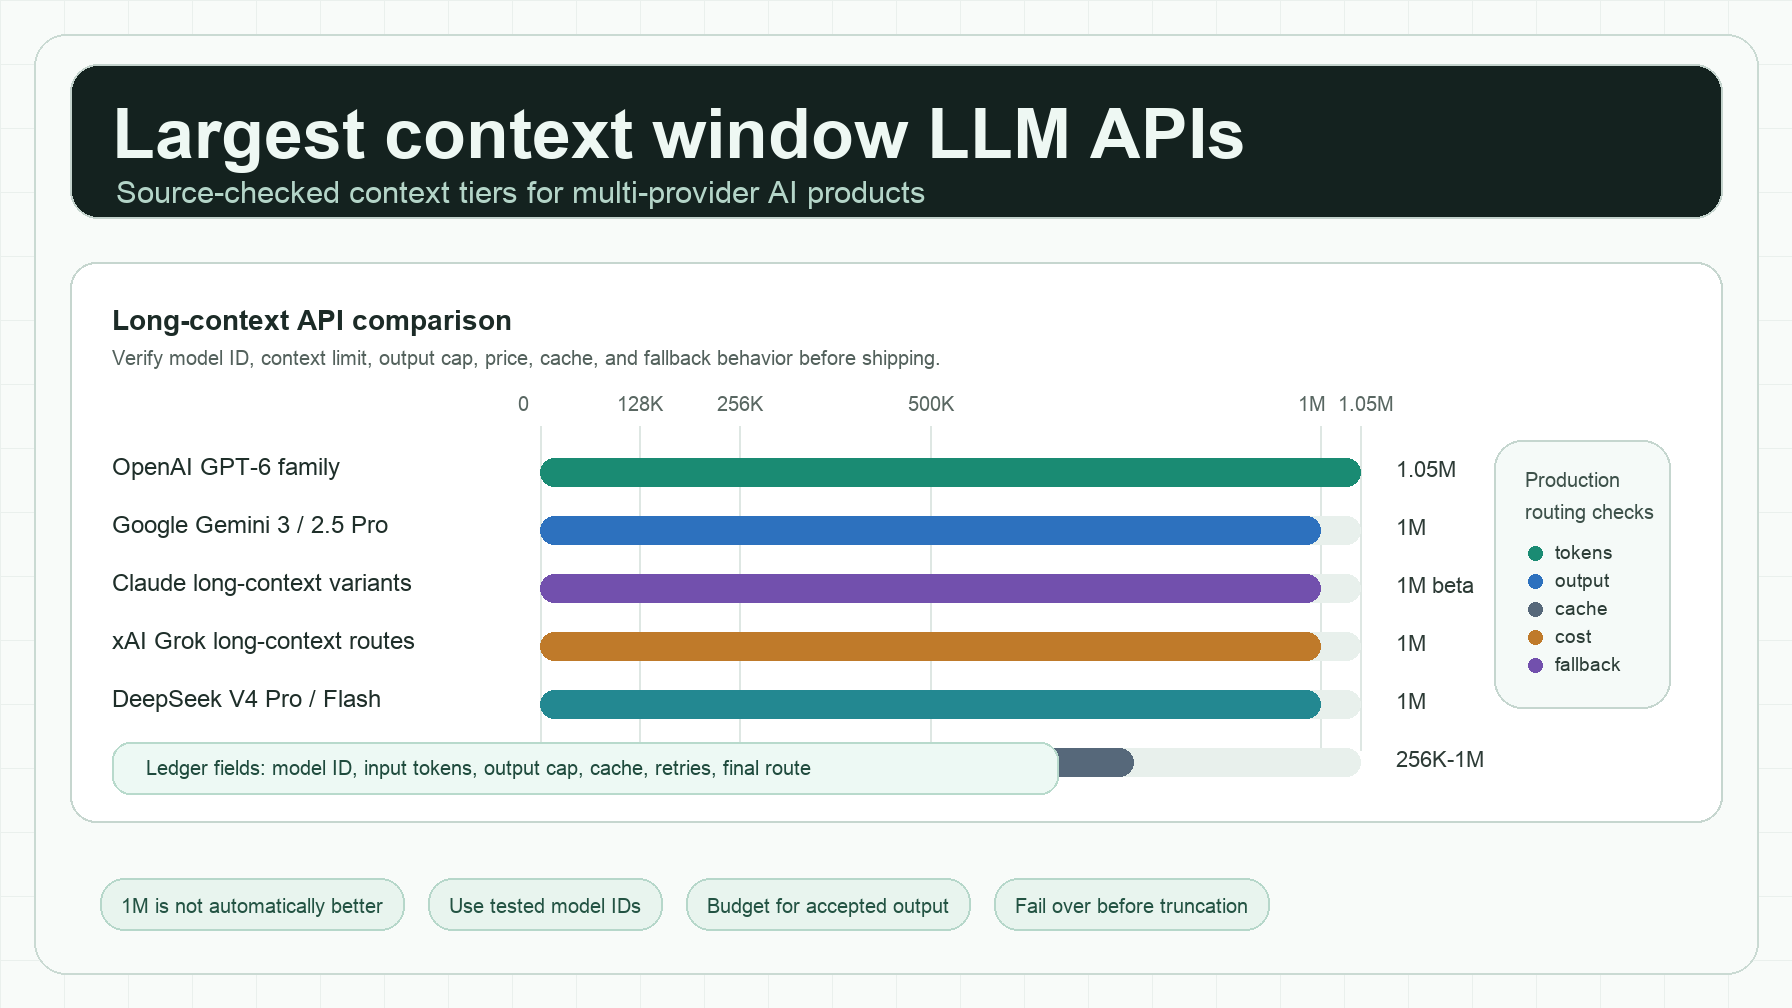
LLM Context Window Explained: What It Means, Sizes for Every Major Model, and How to Use It (October 2026)
An LLM context window is the model's working memory per request. See what 128K, 200K and 1M tokens mean, published limits for major models in October 2026, long-context pricing, and code to count tokens.
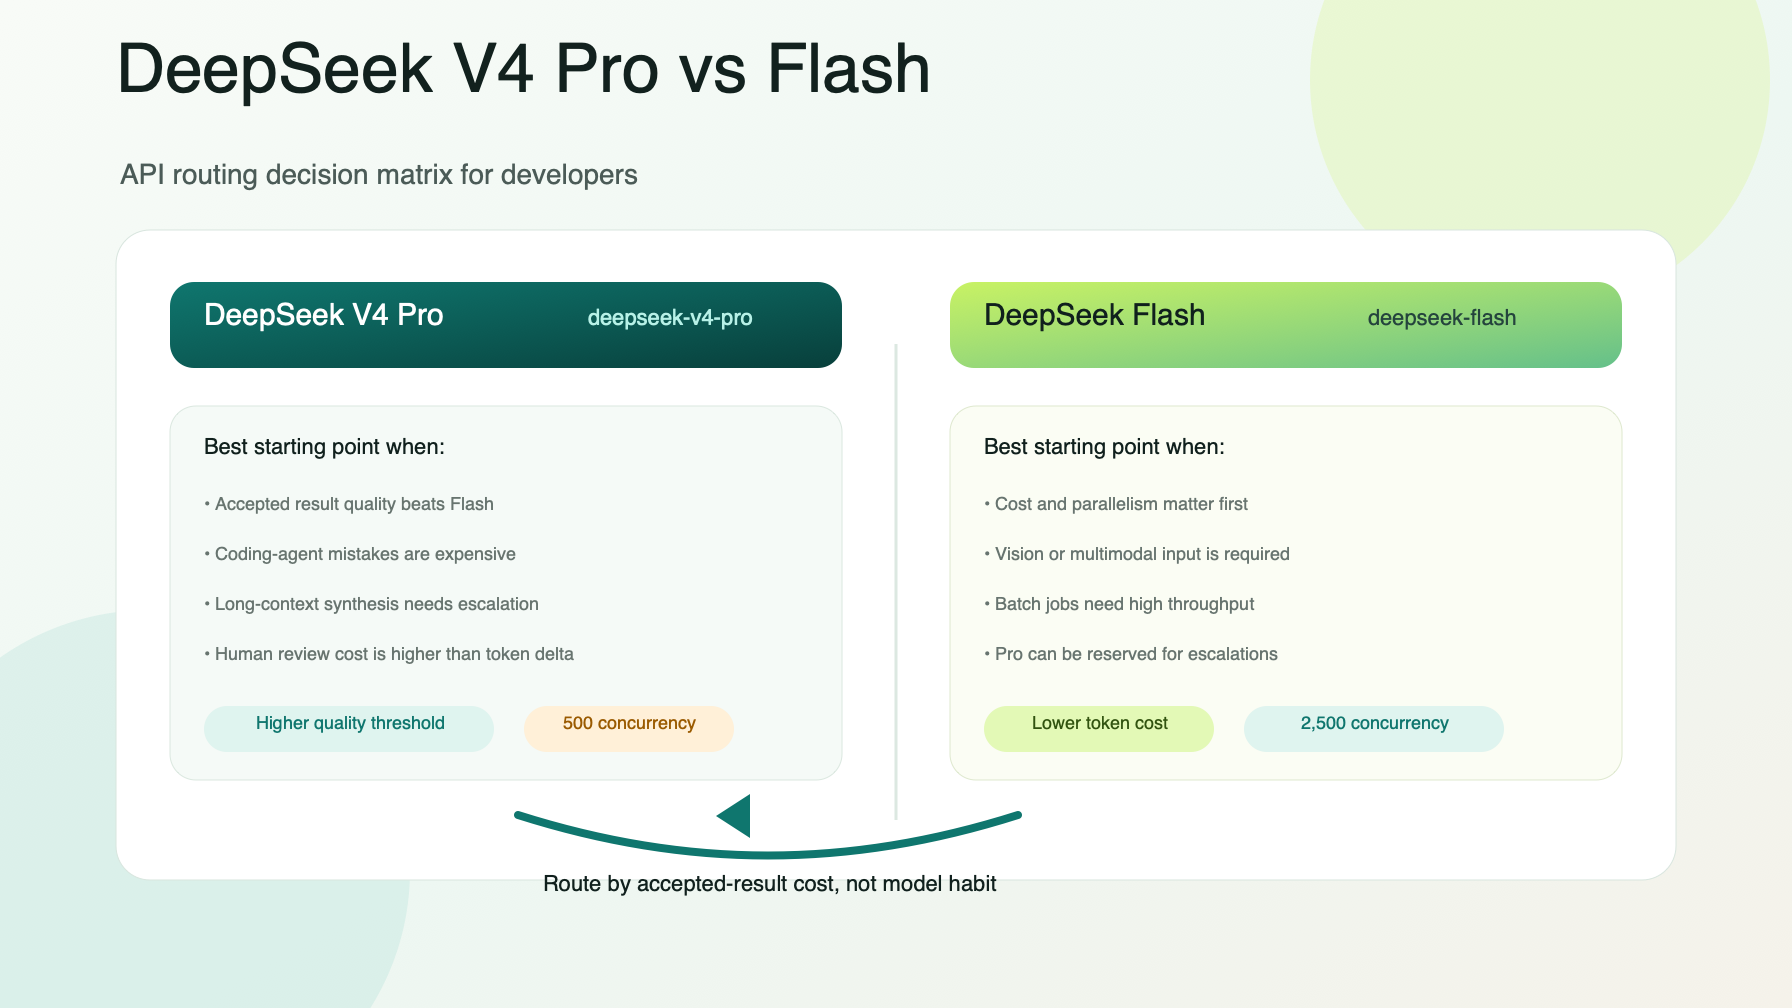
DeepSeek V4 Pro vs Flash: Which Model Fits Your API Workflow?
Compare DeepSeek V4 Pro vs Flash for API routing, pricing, vision, concurrency, cache cost, and when to use Pro or Flash.

GLM-5.3 Prime API: Pricing, Context, and Setup
Check GLM-5.3 Prime API pricing, 1M context, 128K output, 10,000 RPM, how it differs from base GLM-5.3, and setup patterns.
Kimi API Pricing (2026): K3 Cost, API Key, and Setup
Kimi API pricing, K3 token costs, API key setup, base URL, context window, and a working request example, verified for 2026.
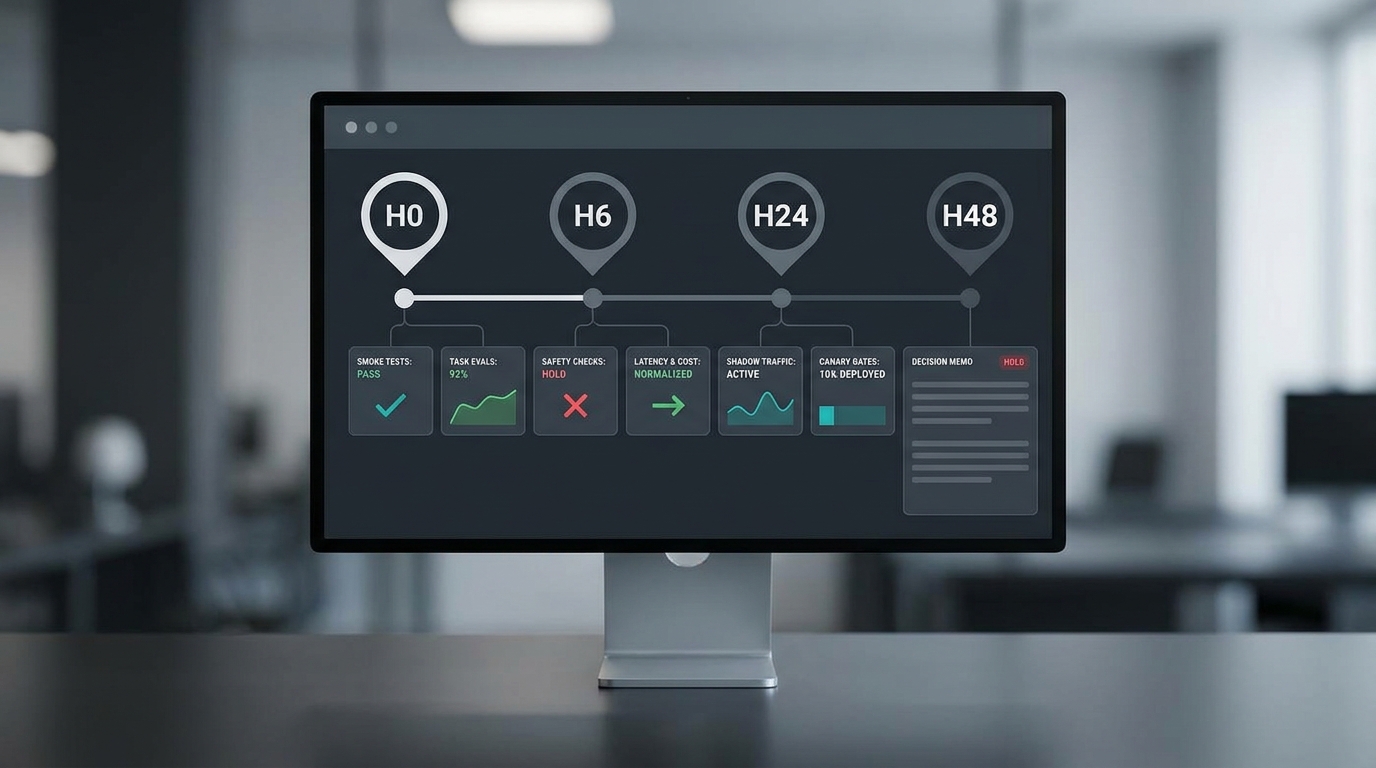
How to Evaluate a New Model in 48 Hours: A Release-Day Checklist
Use this 48-hour release-day checklist to evaluate a new AI model with smoke tests, task evals, safety gates, latency checks, accepted-output cost, and canary rules.
GLM-4.7 vs Claude Sonnet 4.6: Coding Quality and Cost Math
Compare GLM-4.7 vs Claude Sonnet 4.6 for coding agents with token cost math, quality tests, routing rules, and a Flatkey evaluation scorecard.
DeepSeek vs ChatGPT (2026): Features, Cost, Privacy, and API
ChatGPT is the more complete assistant; DeepSeek is cheaper and open-weight but stores data in China. Compare apps, models, coding, privacy, and official API prices as of October 2026.
DeepSeek V4 Flash Pricing (October 2026): Peak, Off-Peak, and Free Access
DeepSeek Flash (now V4.1-Flash-1017) costs $0.30 input and $1.20 output per 1M tokens at peak, and half that off-peak. See the full price table, peak hours, a worked cost example, and what is actually free.
Sora 2 API Deprecation Watch: Routing Checks Before September 24, 2026
Use this September 2026 Sora 2 API deprecation checklist to verify shutdown dates, routes, logs, fallback policy, and active video models.
Build faster with one AI gateway.
Use flatkey.ai to manage models, keys, billing, and observability from one API platform.
Get started