
Model and Modality Playbooks
Latest articles in Model and Modality Playbooks.
How to Get a DeepSeek API Key and Use It in 2026
Get a DeepSeek API key, secure it, test your first request, and choose between direct DeepSeek access and a Flatkey multi-model route.
Seedance 2.0 API Access and Pricing Through One AI API Key
Verify Seedance 2.0 API routes, per-second pricing, and accepted-clip budgeting before routing video jobs through one Flatkey API key.
Gemini API Base URL: OpenAI-Compatible Setup (2026)
Use the official Gemini API base URL with OpenAI SDKs, compare direct Google and Flatkey routes, and fix common base URL errors.
Qwen API Pricing (2026): Every Model, Region, and Discount Explained
Current Qwen Max, Plus, Flash, Coder and VL prices on Alibaba Cloud Model Studio, why regions price differently, tier and cache rules, and OpenAI-compatible code.
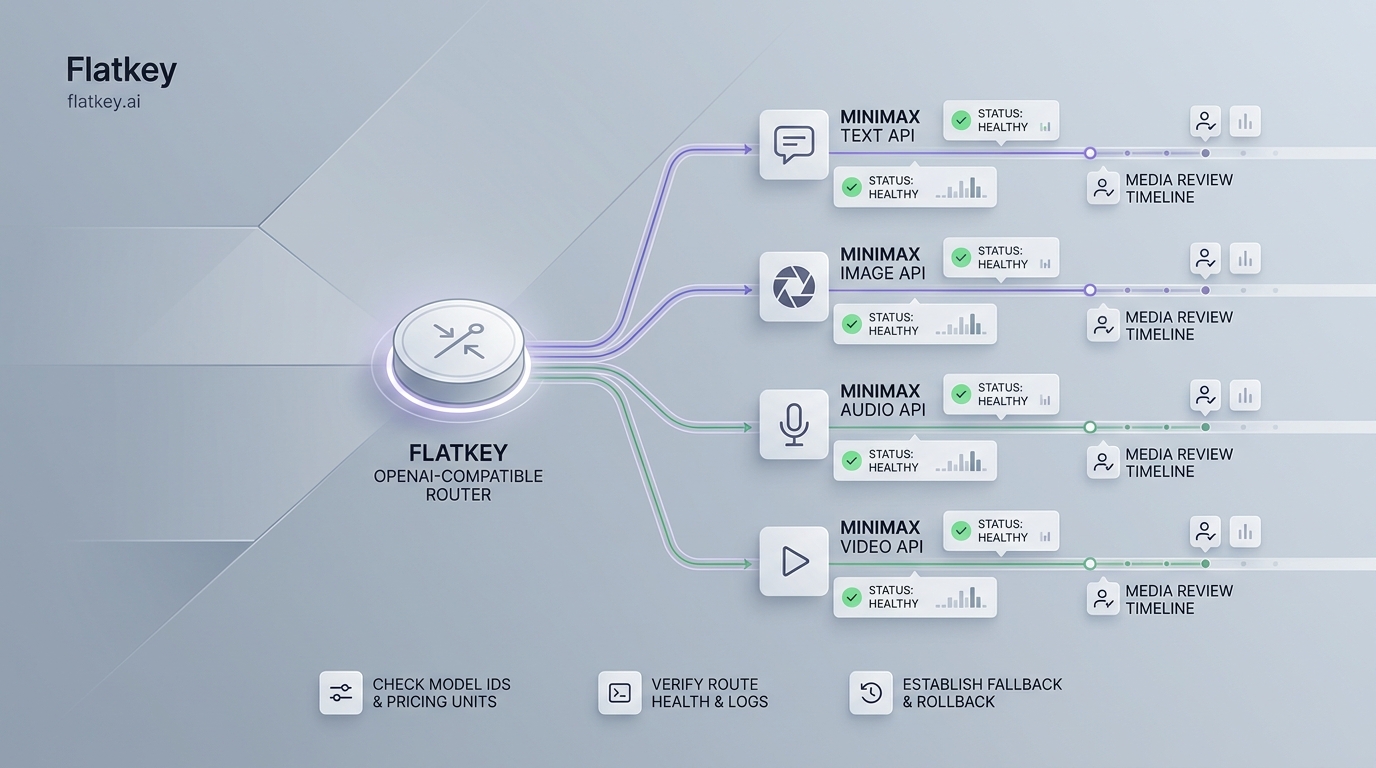
MiniMax API Access With One OpenAI-Compatible Router
Use this MiniMax API access guide to compare direct MiniMax setup, Flatkey routing, current model checks, pricing units, logs, and rollback.
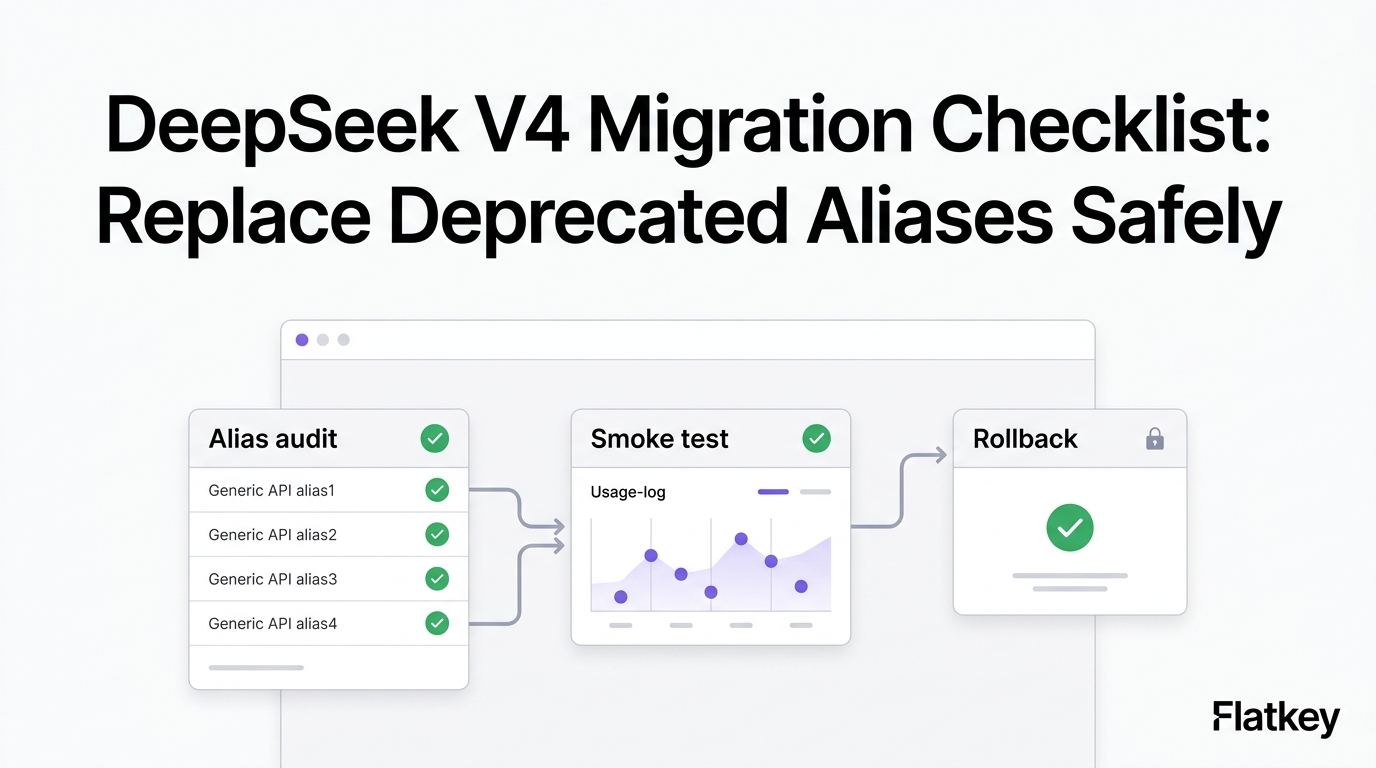
DeepSeek V4 Migration Checklist: Replace Deprecated Aliases Safely
Use this DeepSeek V4 migration checklist to replace retired Flash aliases, test thinking mode, verify Flatkey routing, and roll back safely.
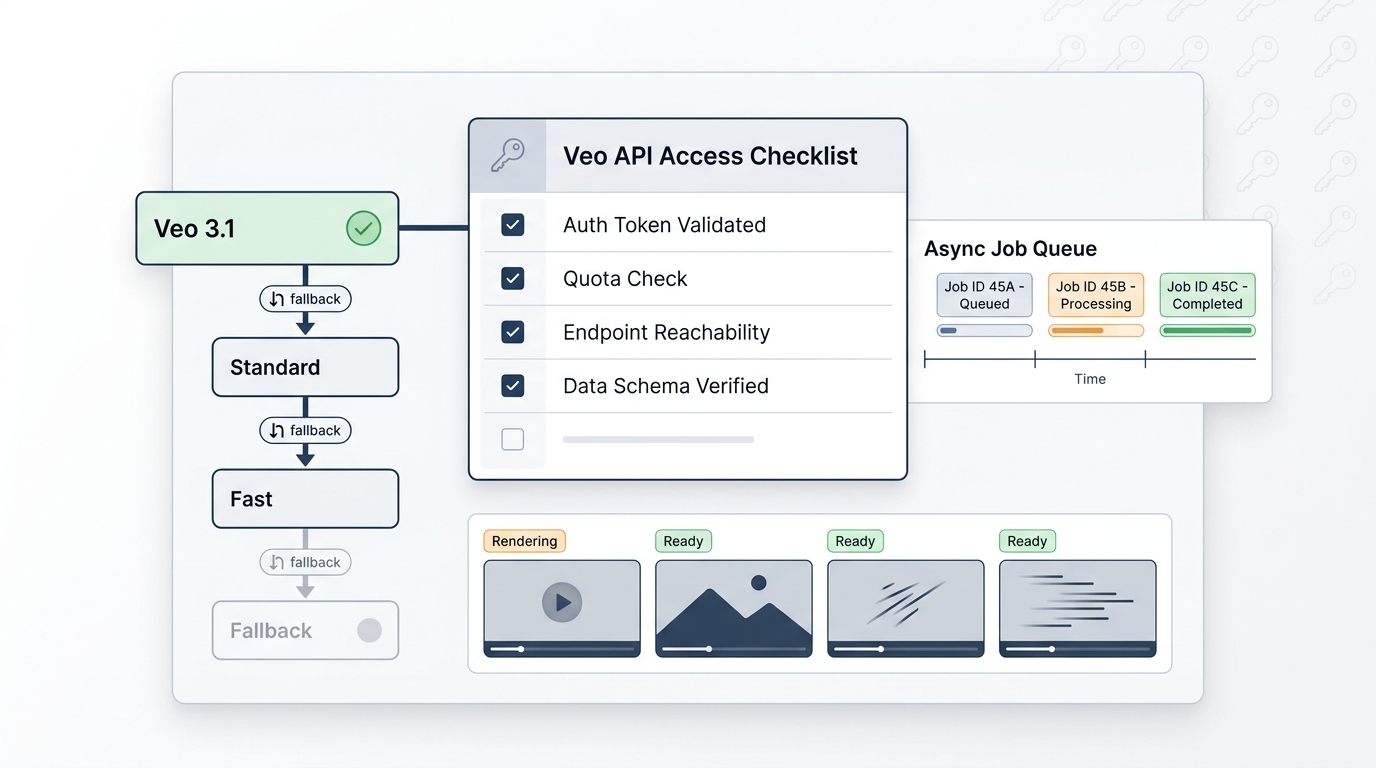
Veo 3 Pricing (October 2026): Veo 3 vs 3.1 Costs, API Access, and Plans
Veo 3 and Veo 3.1 cost $0.40 per second with audio on Vertex AI as of October 2026. Compare Veo 3.1 Fast and Lite, Gemini Omni Flash token pricing, Google AI plans, and what the Gemini API shutdown means for your code.
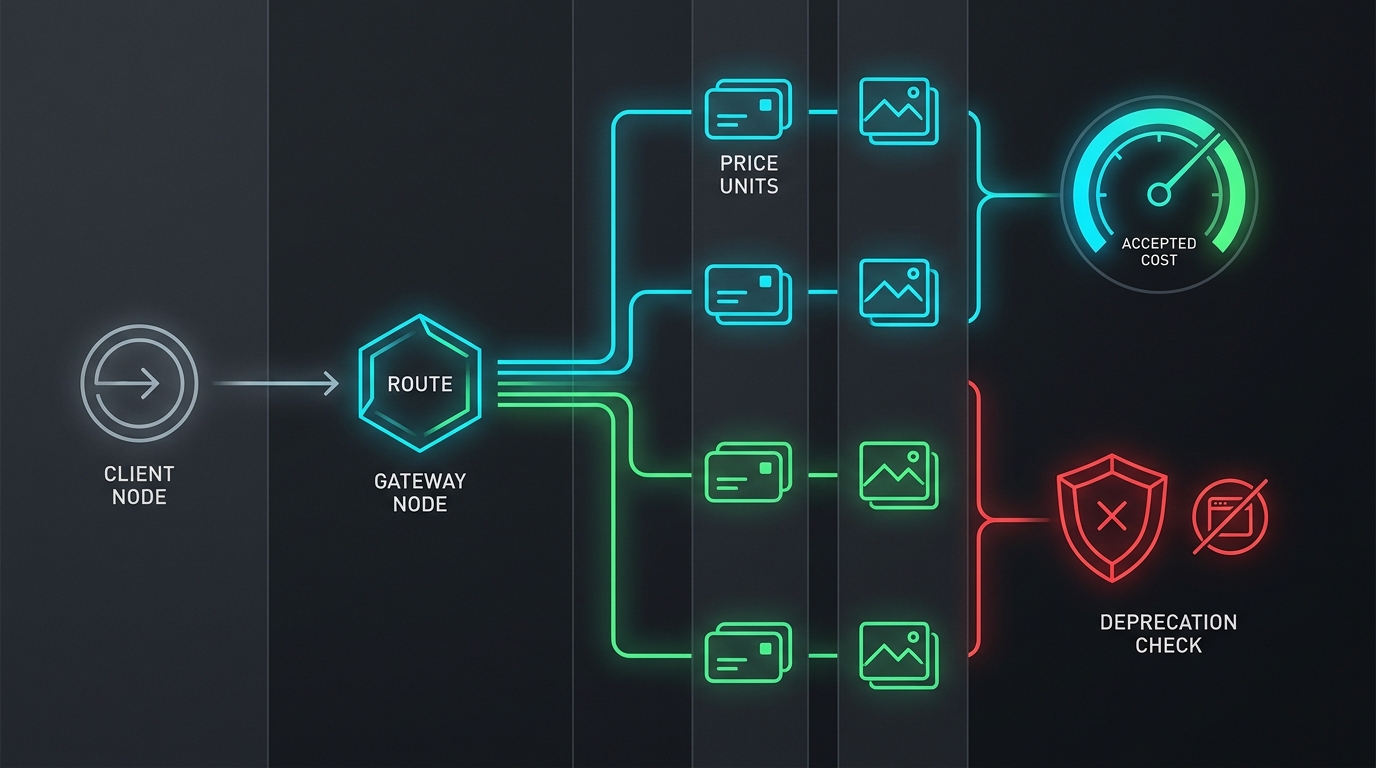
Imagen API Pricing and Routing Checks for OpenAI-Compatible Workflows
Use this September 2026 Imagen API pricing and routing checklist to verify Gemini image model prices, deprecations, Flatkey routes, and accepted-image cost before launch.
GPT Image 2 API Through Flatkey: Pricing, Models, and Request Checks
Use this GPT Image 2 API Through Flatkey guide to verify model rows, pricing units, endpoint support, and request checks before production traffic.
Claude vs GPT API Routing: When to Prefer Provider-Specific Models or a Gateway
A practical decision framework for routing Claude and GPT workloads through direct provider APIs, a Flatkey gateway, or a hybrid architecture.
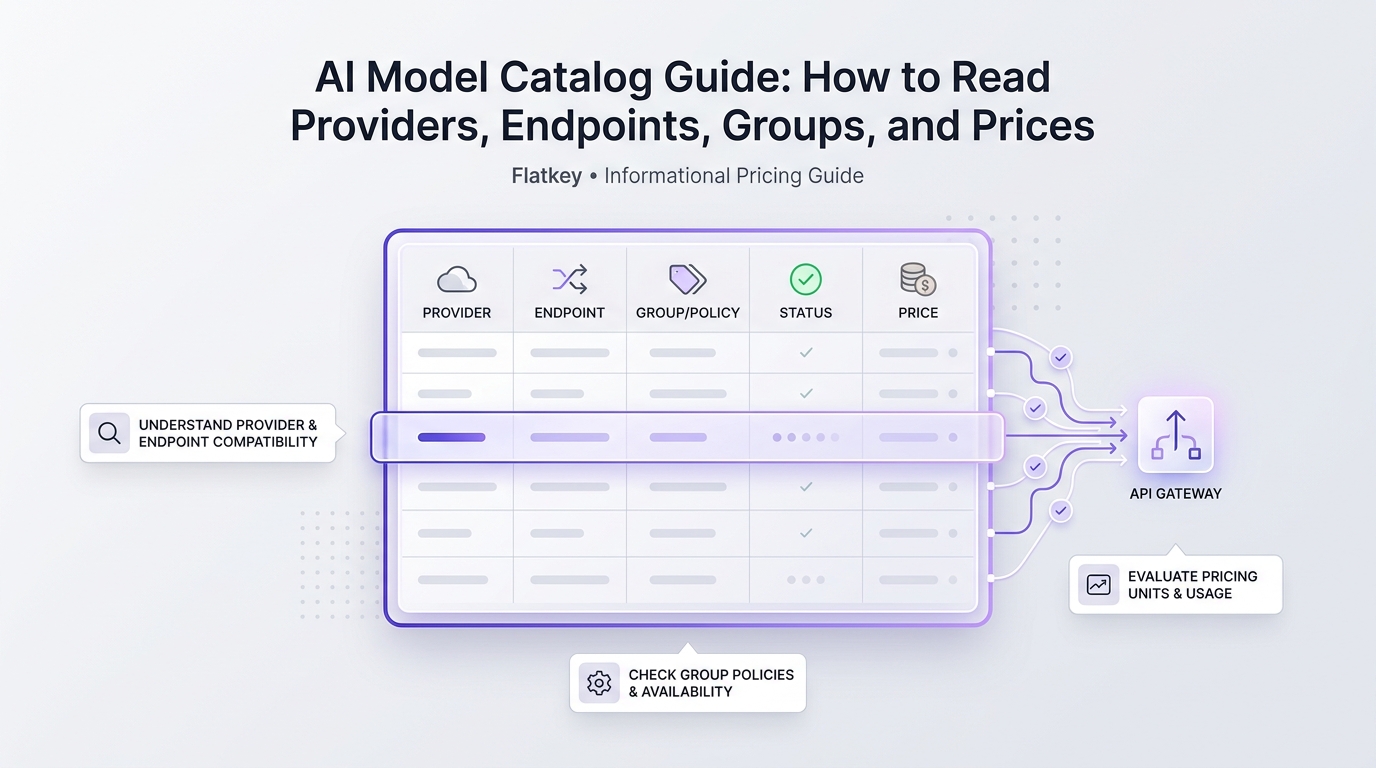
AI Model Catalog Guide: How to Read Providers, Endpoints, Groups, and Prices
Use this AI model catalog guide to read providers, endpoints, groups, availability, pricing units, and usage evidence before production routing.
GPT Image vs Gemini Image API: Routing and Pricing Questions Before You Choose
Compare GPT Image vs Gemini Image API routing, pricing units, model status, rate limits, and accepted-image cost before production rollout.
Seedance vs Veo API: Video Generation Routing and Pricing Review
Compare Seedance vs Veo API pricing units, route controls, model availability, and production checks before sending creator workflows to video generation APIs.
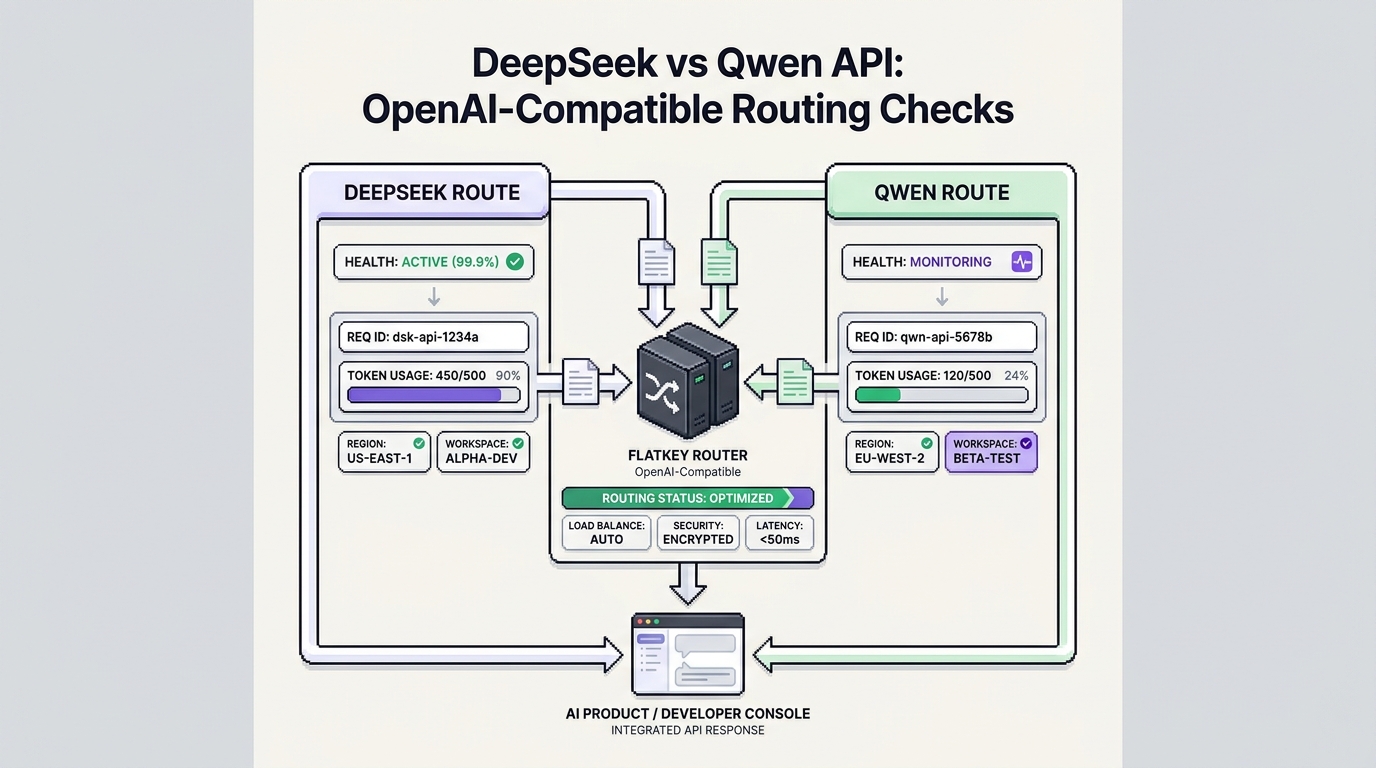
DeepSeek vs Qwen (October 2026): Models, Pricing, and Which to Use
DeepSeek is simpler and cheaper at the flagship tier; Qwen offers more model sizes, open weights, and regional endpoints. Compare models, October 2026 API prices, free options, and how to test both with one key.
GPT Image vs Imagen API: Pricing Units and Request Checks
A current comparison of GPT Image and Google's post-Imagen image-generation path, with pricing units, request checks, rate-limit checks, and migration guidance.
Speech-to-Text API Routing: How to Balance Transcription Cost, Latency, and Data Controls
Use this speech-to-text API routing framework to compare transcription cost, latency classes, fallback behavior, and data controls before production rollout.
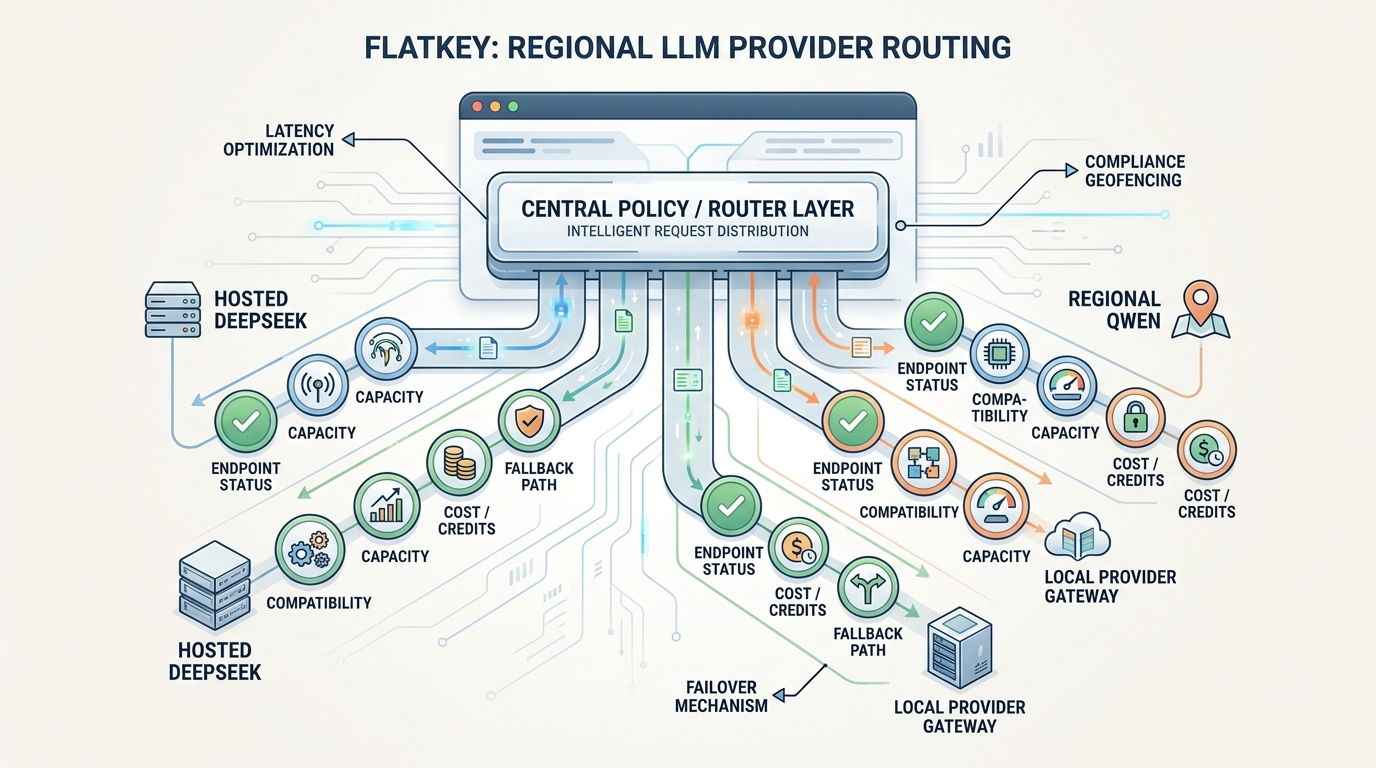
Regional LLM Provider Routing: When DeepSeek, Qwen, and Local Providers Need Separate Checks
A practical provider-check framework for routing DeepSeek, Qwen, and local LLM gateways with region, compatibility, capacity, cost, and fallback controls.
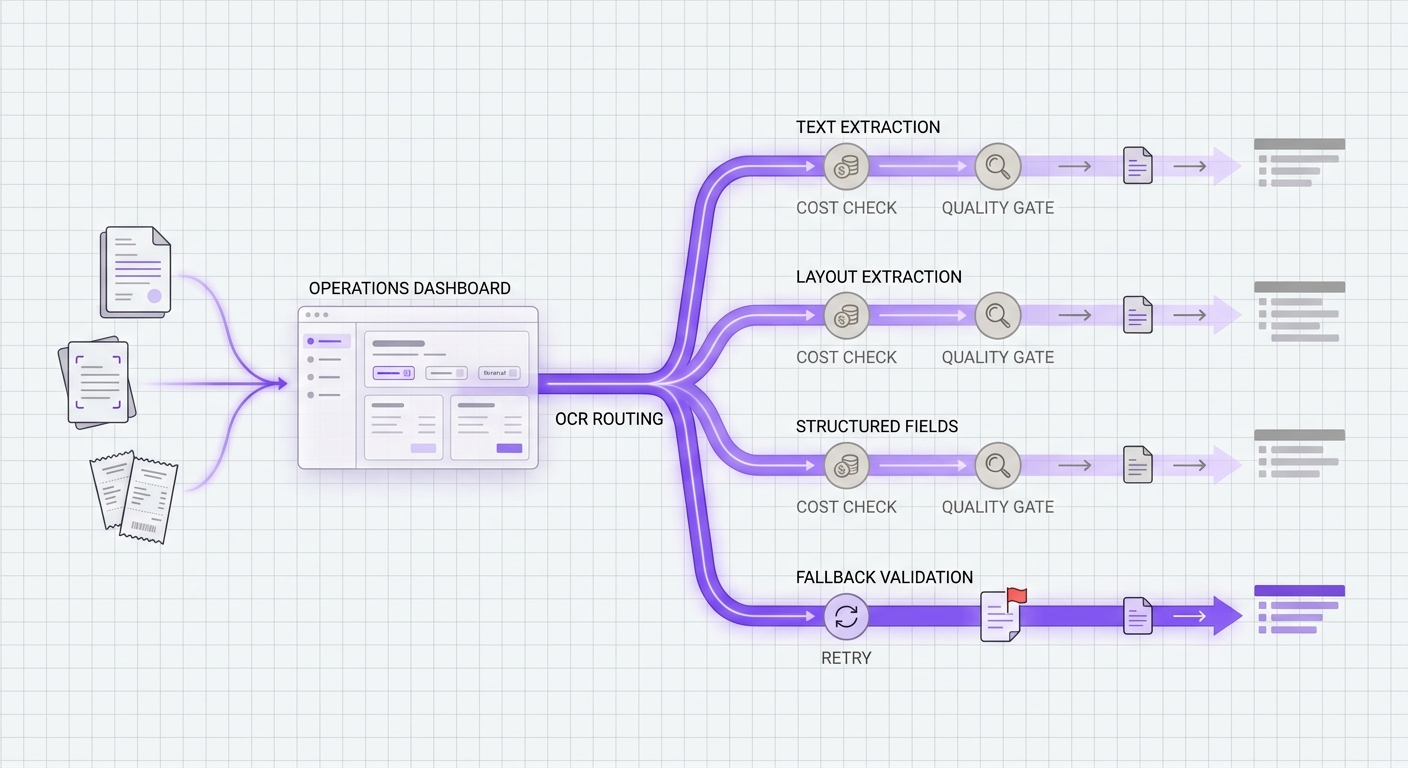
OCR Model Routing: How to Balance Text Extraction Cost, Quality, and Fallback Checks
Use this OCR model routing framework to compare OCR API cost, extraction quality, and fallback constraints before standardizing document AI traffic.
Build faster with one AI gateway.
Use flatkey.ai to manage models, keys, billing, and observability from one API platform.
Get started