
Cost, Billing, and Ops
Latest articles in Cost, Billing, and Ops.
NVIDIA B300 vs B200: Memory, Bandwidth, Training, and Inference
A practical B200 vs B300 comparison for ML infrastructure teams evaluating NVIDIA Blackwell GPU memory, bandwidth, training, inference, and procurement economics.
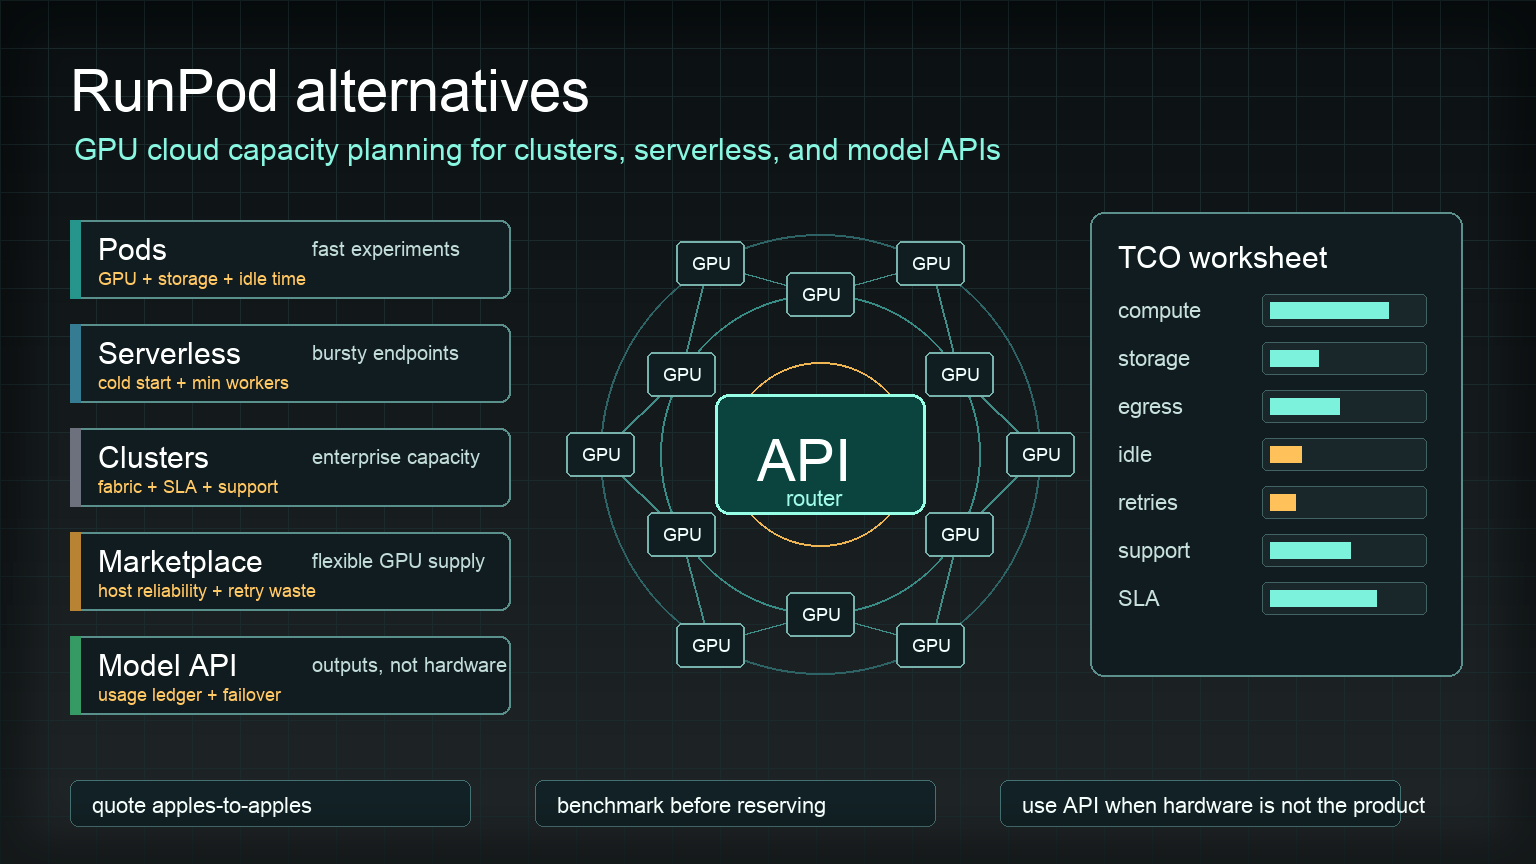
10 Best RunPod Alternatives in 2026: Prices, Pros, and Which to Pick
Compare 10 RunPod alternatives with October 2026 GPU prices: cheapest marketplaces, stable GPU clouds, serverless platforms, and model APIs, plus Vast.ai vs RunPod, reliability, and a migration checklist.
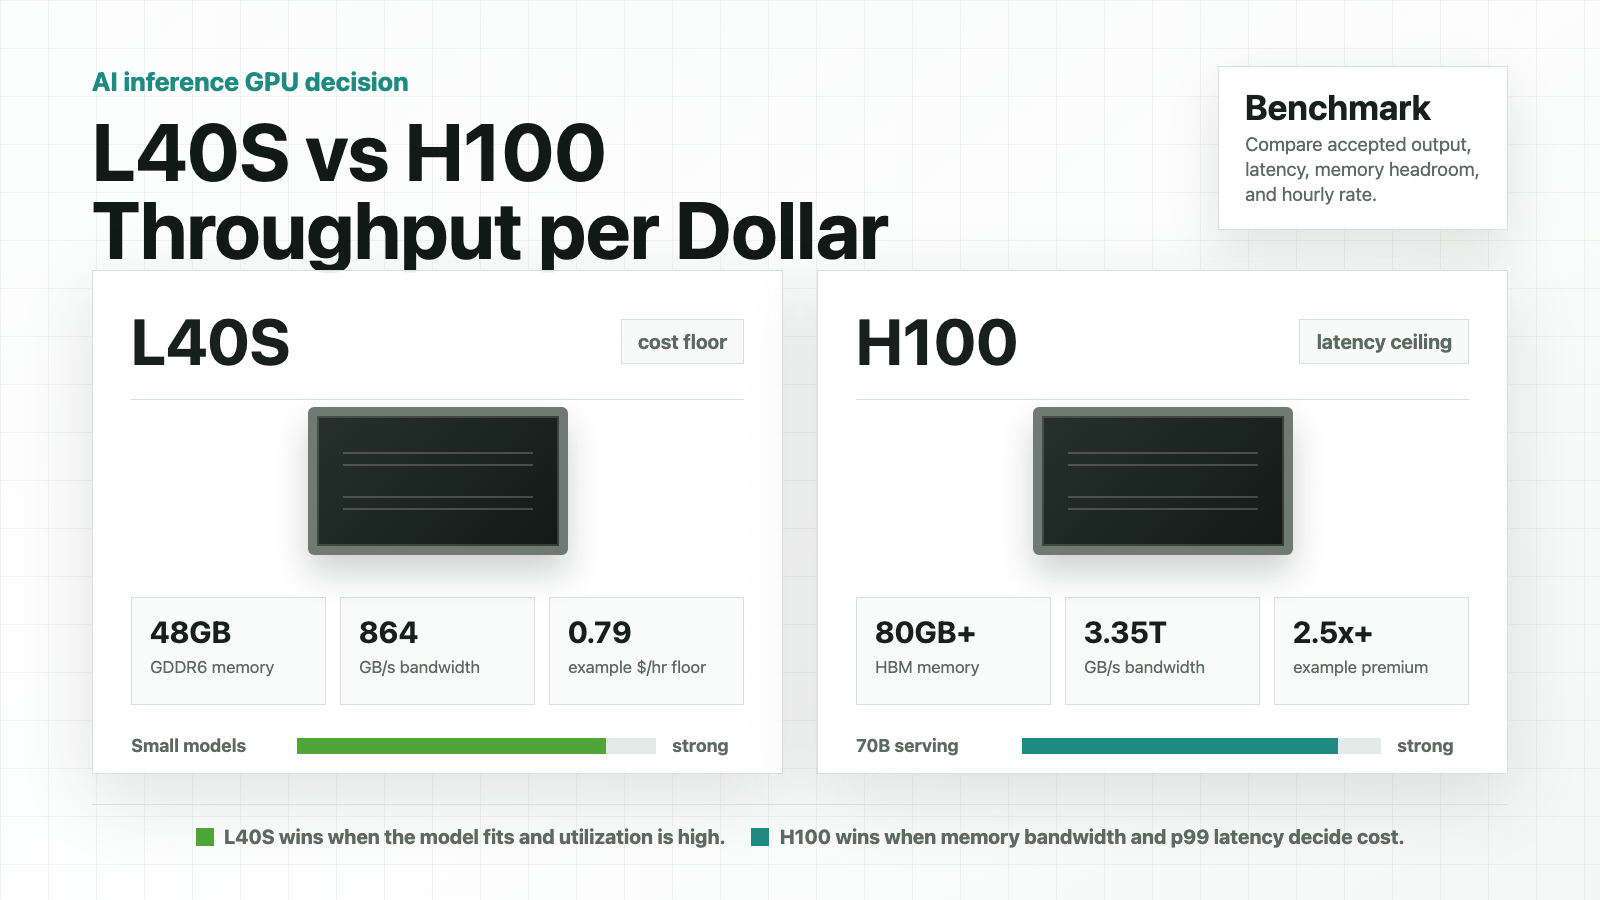
NVIDIA L40S vs H100 for AI Inference: Throughput per Dollar
A practical L40S vs H100 comparison for AI teams evaluating inference throughput, latency, memory fit, and cloud GPU cost per accepted output.
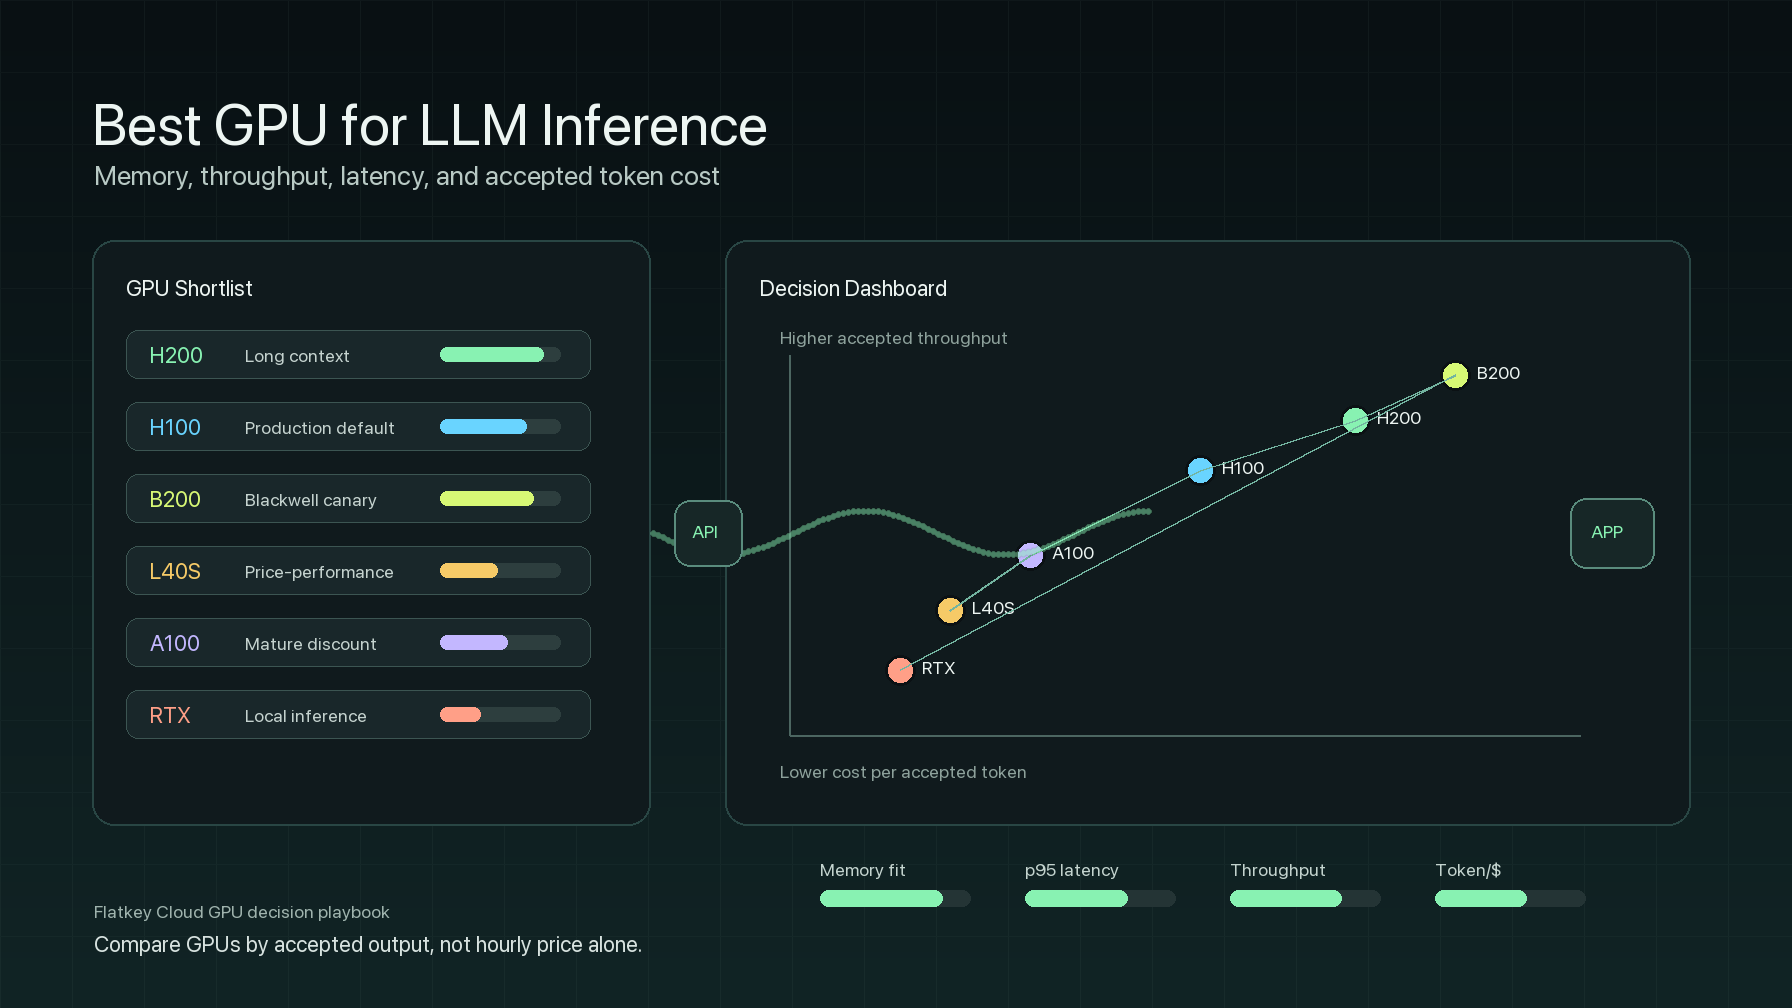
Best GPU for LLM Inference: Memory, Throughput, Latency, and Cost
A practical GPU selection guide for enterprise LLM inference teams, comparing H100, H200, B200, A100, L40S, local RTX-class GPUs, tokens per dollar, p95 latency, memory fit, and cost per accepted token.

Mistral API Pricing (2026): Every Model, Batch Discount, and Cost Example
Full Mistral API price list by model family, free tier and 50% batch rules, worked cost examples, a comparison with GPT, Claude and Qwen, and setup code.
Grok API Pricing (2026): Every Model, Tool Fee, and Multiplier
Every current Grok API price: text, Imagine, and Voice models, plus the long-context, priority, US-region, batch, and tool multipliers, with a calculator and code.
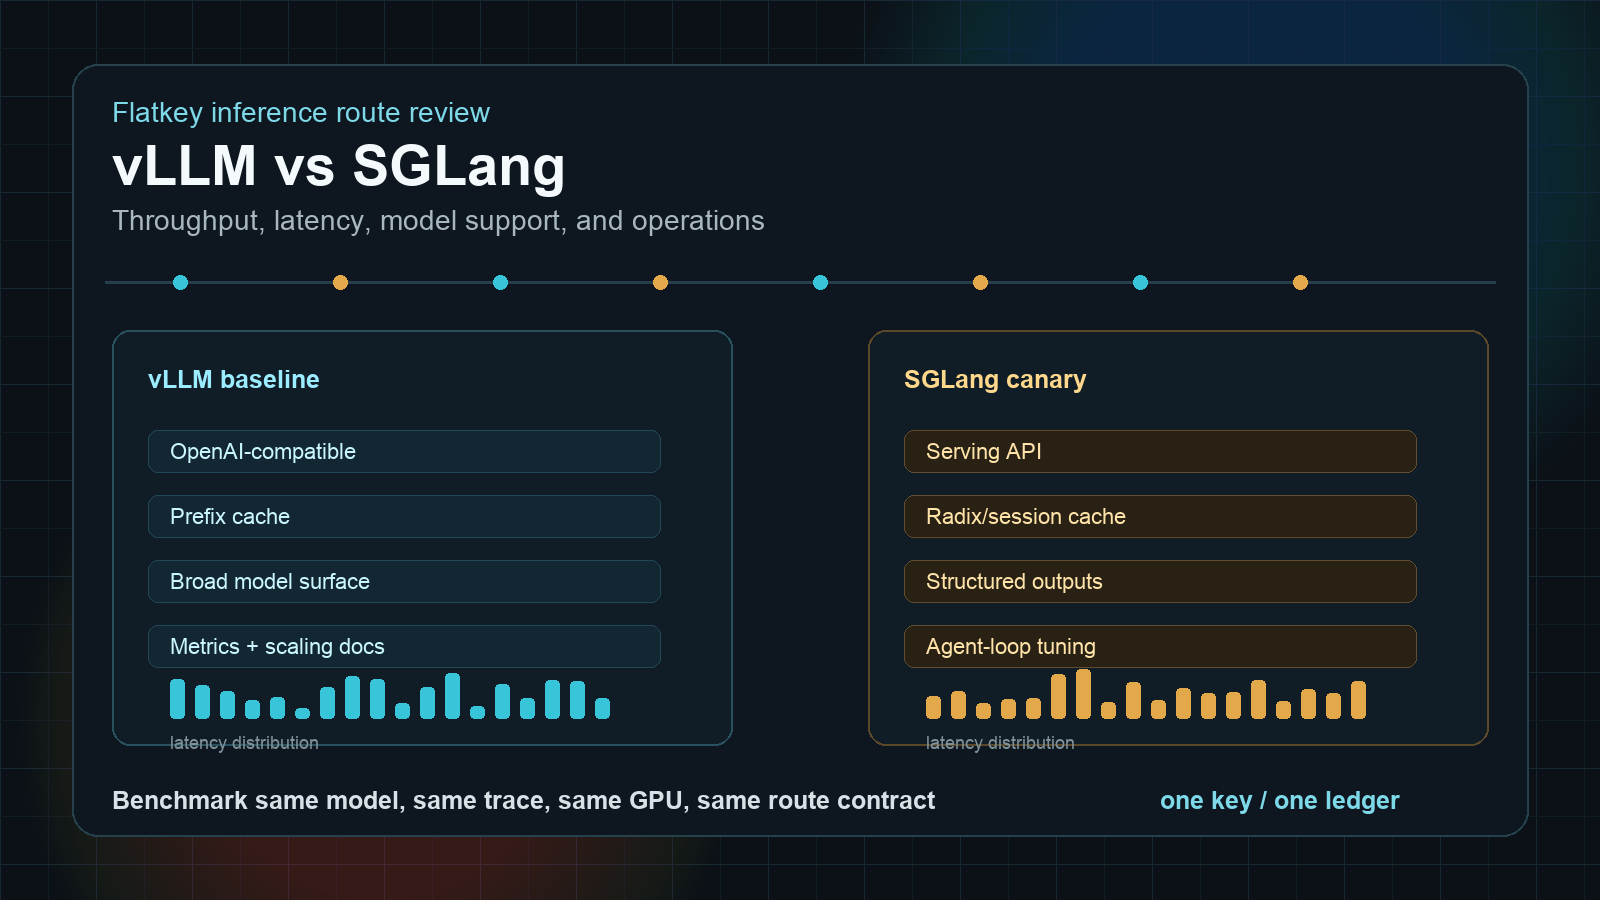
vLLM vs SGLang: Throughput, Latency, Model Support, and Operations
Compare SGLang vs vLLM for cloud GPU inference: throughput, latency, model support, operations, benchmarks, and when Ollama fits local testing.
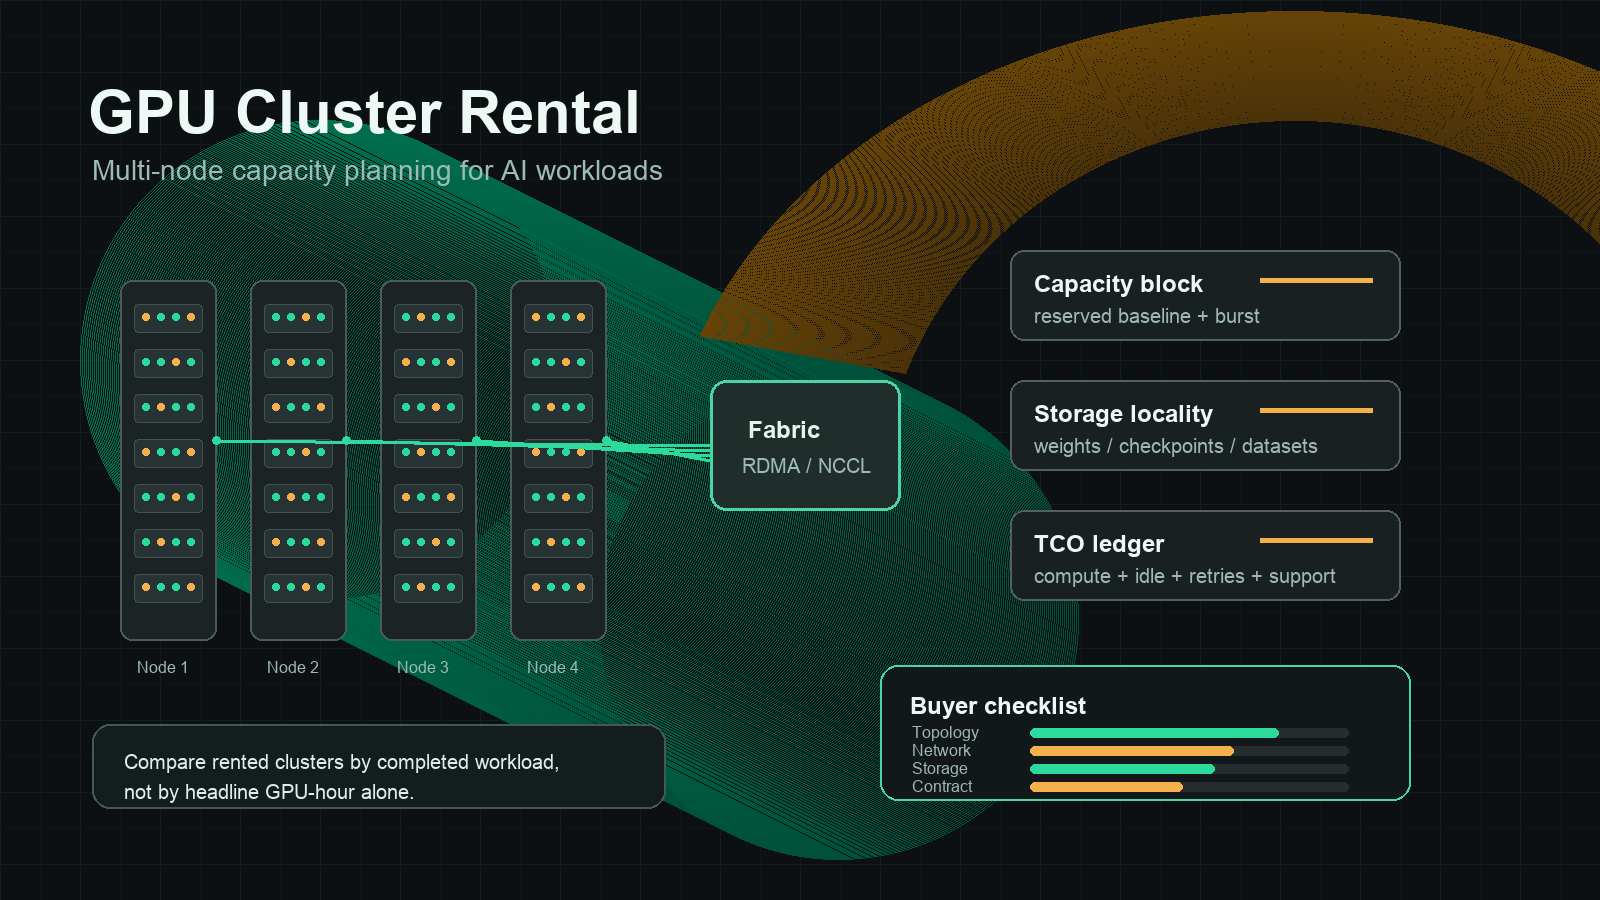
GPU Cluster Rental: A Buyer's Guide to Multi-Node AI Capacity
A buyer's guide for enterprise AI teams evaluating multi-node GPU cluster rental, cloud providers, reserved capacity, network fabric, storage, and TCO.
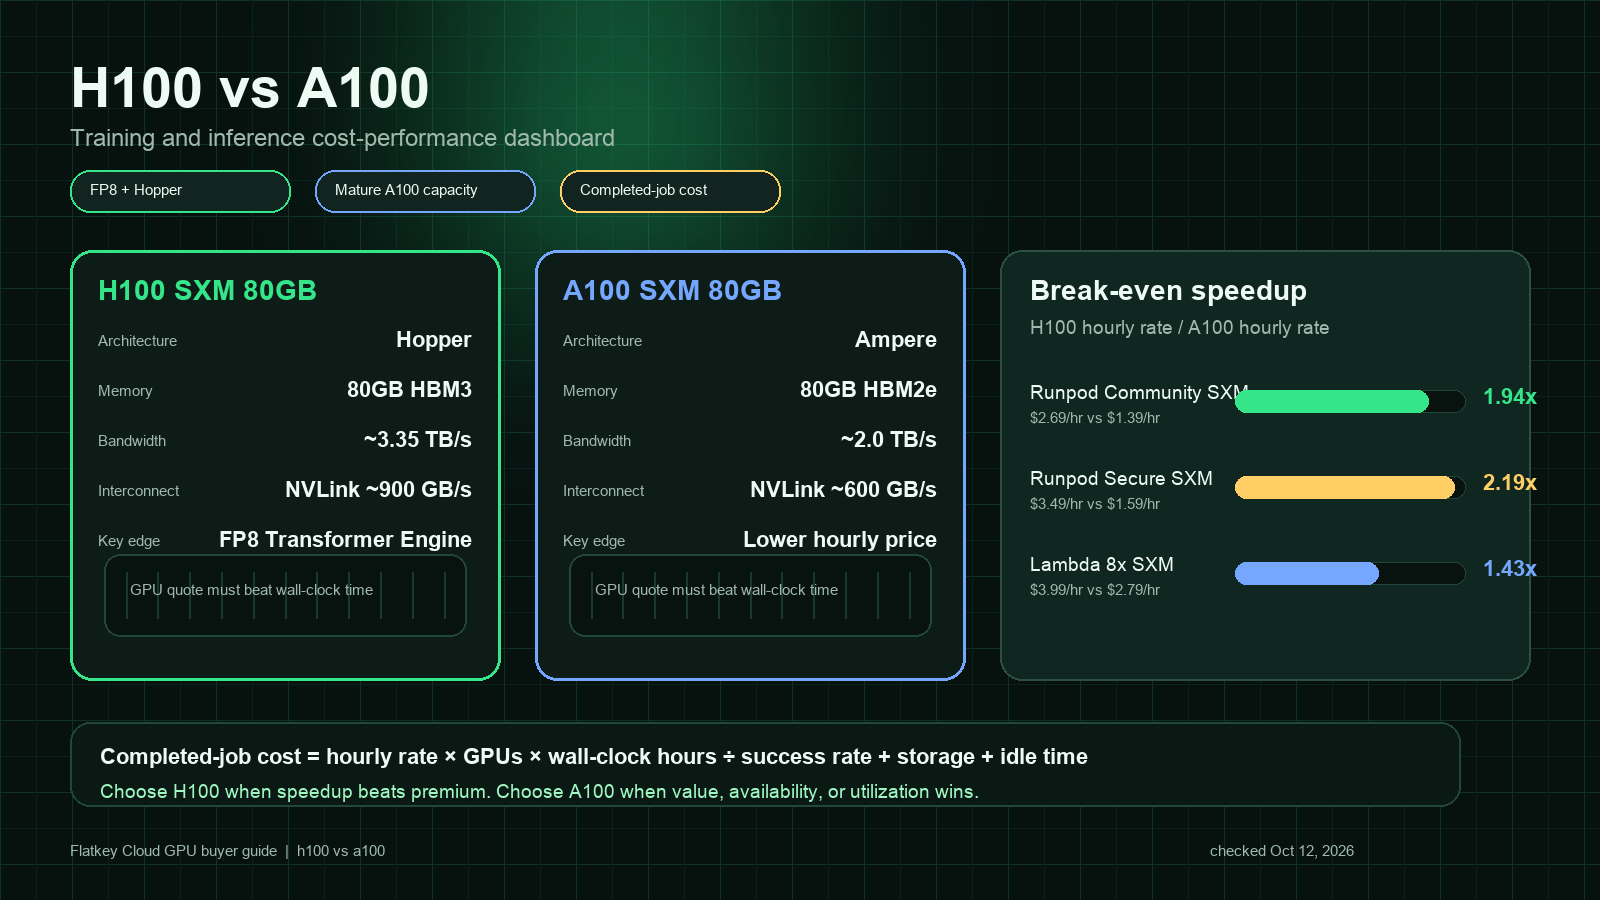
NVIDIA H100 vs A100: Training and Inference Cost-Performance
A practical H100 vs A100 comparison for AI teams deciding between Hopper performance and Ampere value across training, inference, and cloud GPU rental.

H200 vs H100 (2026): Specs, Real Performance, Price per Hour, and Which to Rent
NVIDIA H200 vs H100 in 2026: official specs, why 141GB matters for 70B inference, real hourly rental prices from Flatkey Compute, RunPod, and Lambda, Blackwell alternatives, and a workload-by-workload pick.
OpenAI API Cost in 2026: Pricing Table and Calculator
A current OpenAI API cost guide with GPT-6 pricing tables, a copyable calculator, worked examples, hidden fees, and optimization checks.
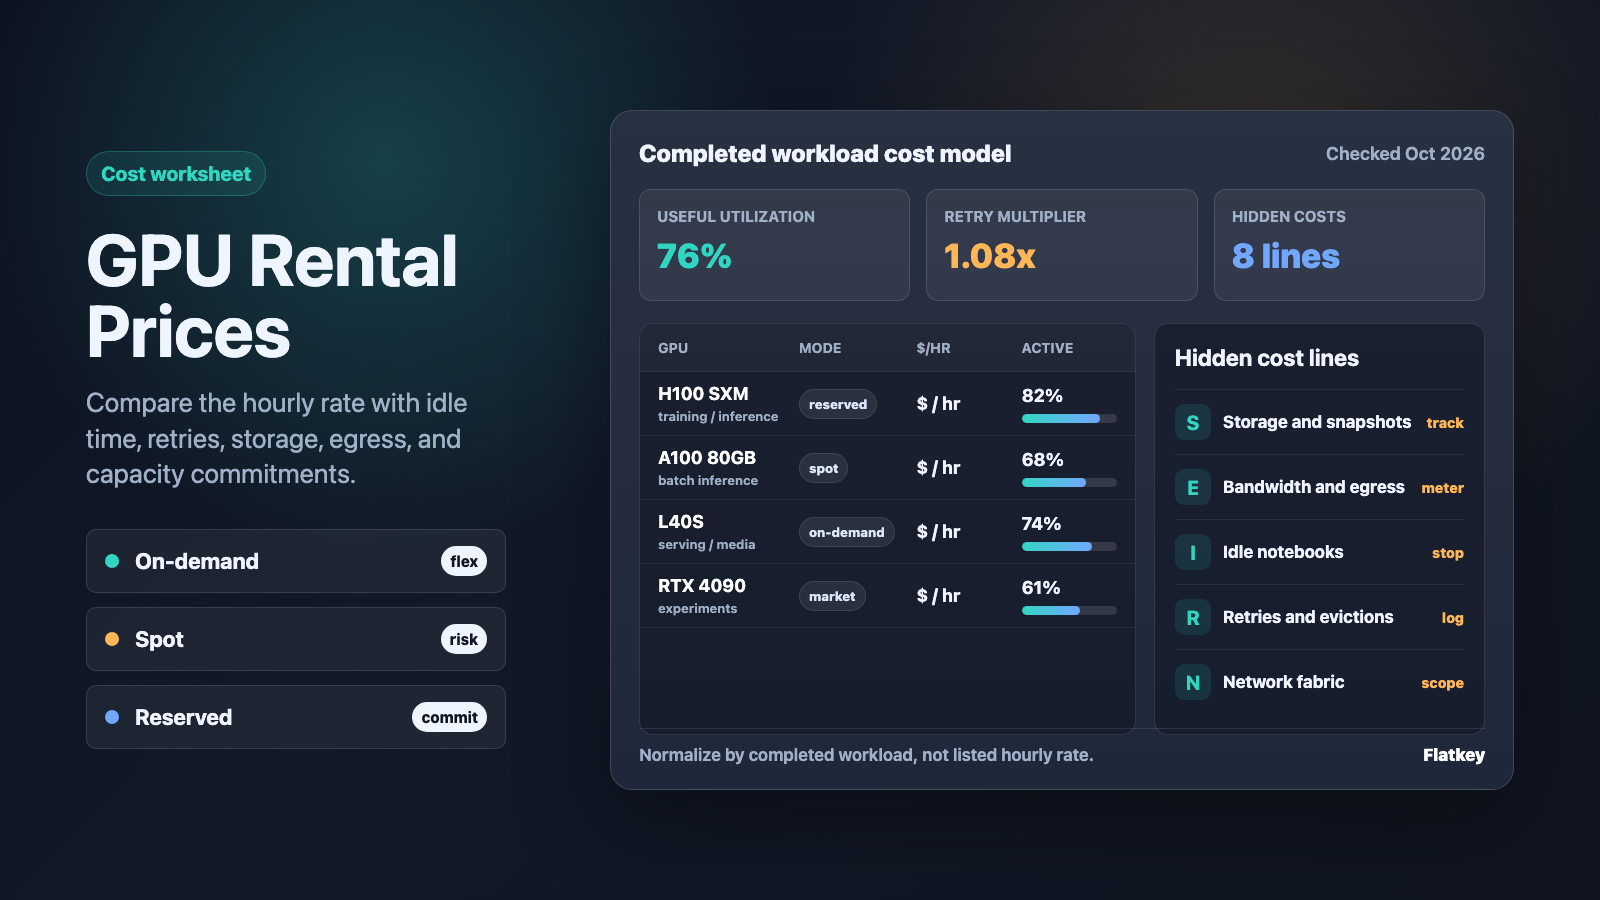
GPU Rental Prices Explained: On-Demand, Spot, Reserved, and Hidden Costs
A practical guide to comparing GPU rental prices by completed workload cost, not only hourly rates, with source checks for on-demand, spot, reserved, marketplace, and hidden-cost models.
Free LLM API (2026): 10 Options Compared by Real Limits, Models, and Catches
Ten free LLM API options checked against official docs in October 2026: what is free, the exact limits, the hidden catches, and code to fall back between them.

Cheapest LLM APIs (2026): AI Model Pricing Comparison
Compare low-cost LLM APIs by current token prices and learn how to choose the cheapest model for your real workload, not just the lowest list rate.
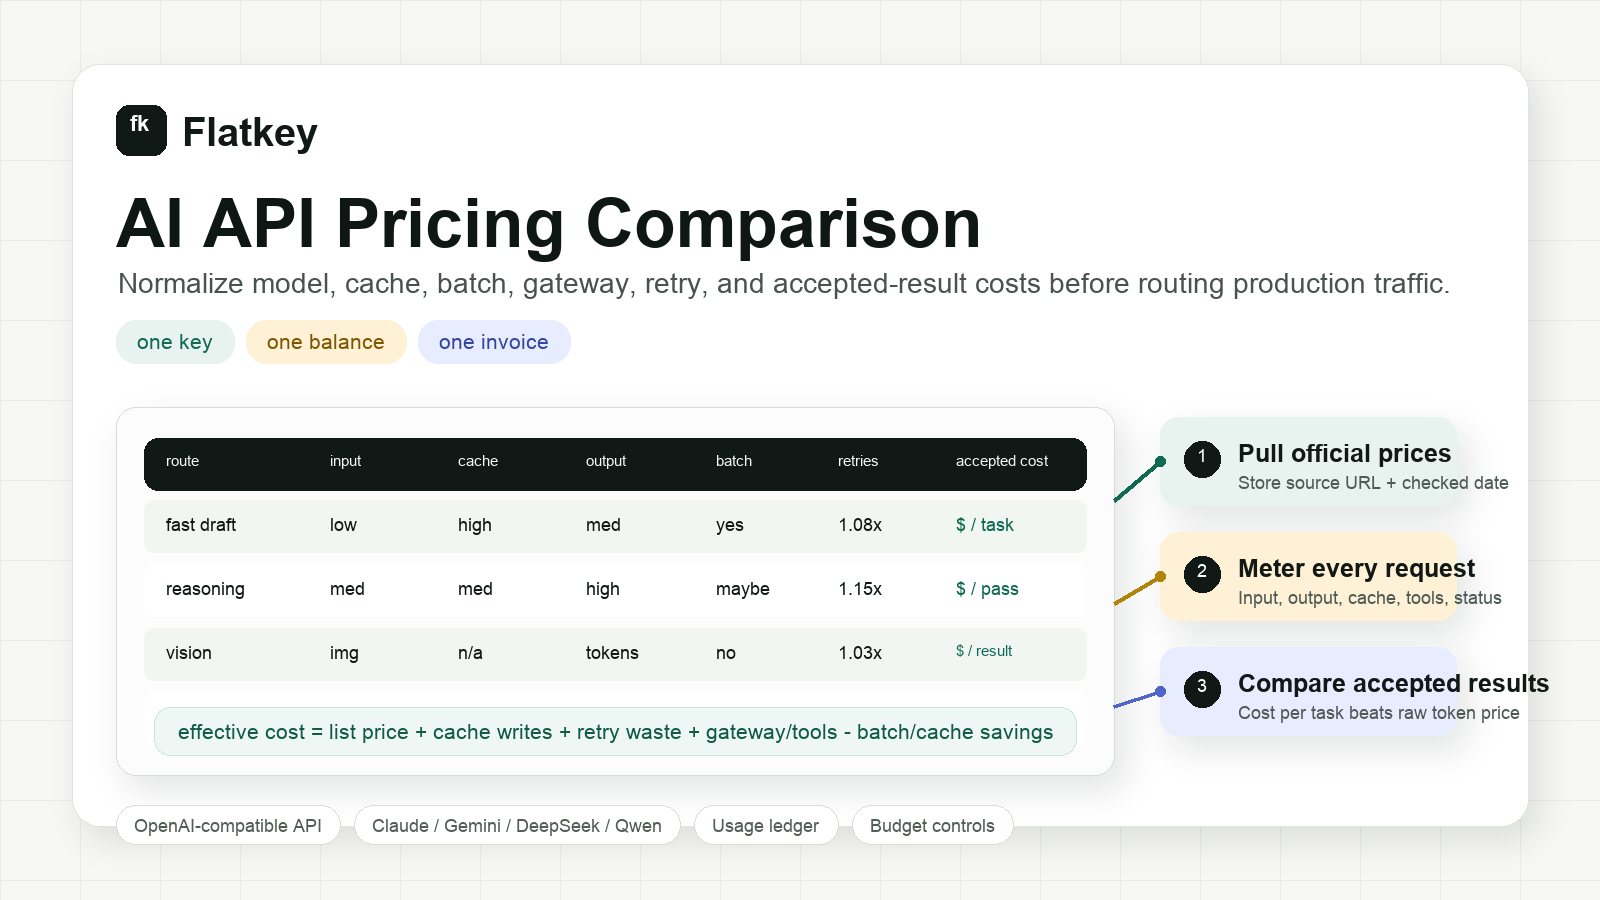
AI API Pricing Comparison: Model, Cache, Batch, and Gateway Costs
A practical AI API pricing comparison framework for developers, product teams, and procurement teams comparing model, cache, batch, gateway, retry, and accepted-result costs.
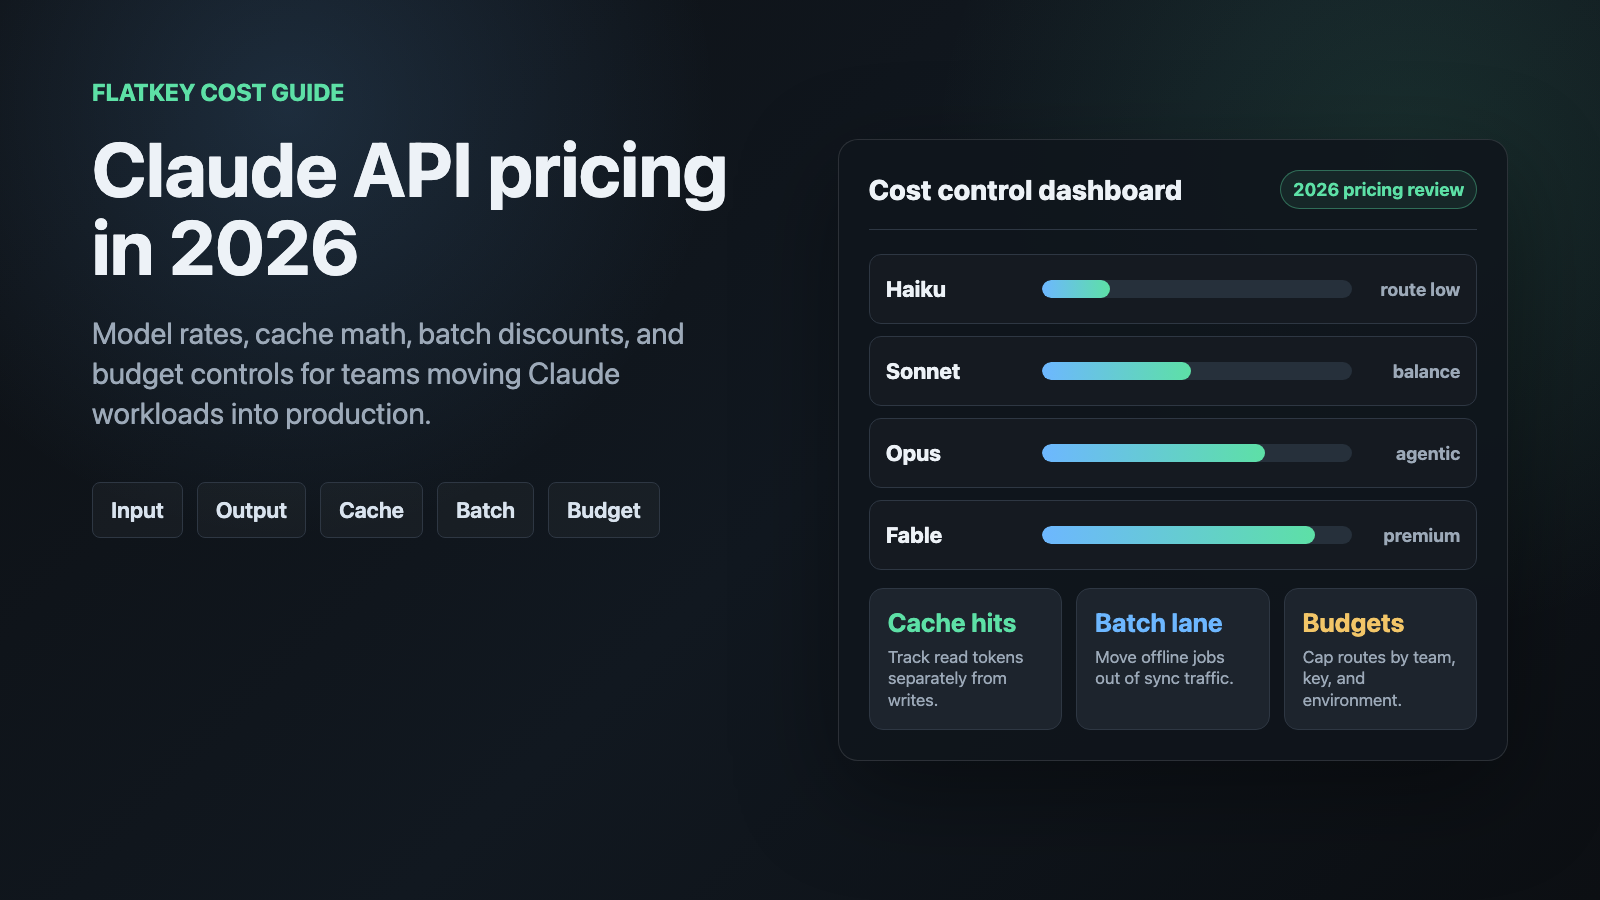
Which Claude Model Is Best for Coding? Opus 5.5 vs Sonnet 5.5 vs Haiku 5.5 vs Fable 5.1 (2026)
Which Claude model should you use for coding in 2026? A task-by-task guide to Opus 5.5, Sonnet 5.5, Haiku 5.5 and Fable 5.1, with official pricing, session cost math, Claude Code aliases and runnable API examples.
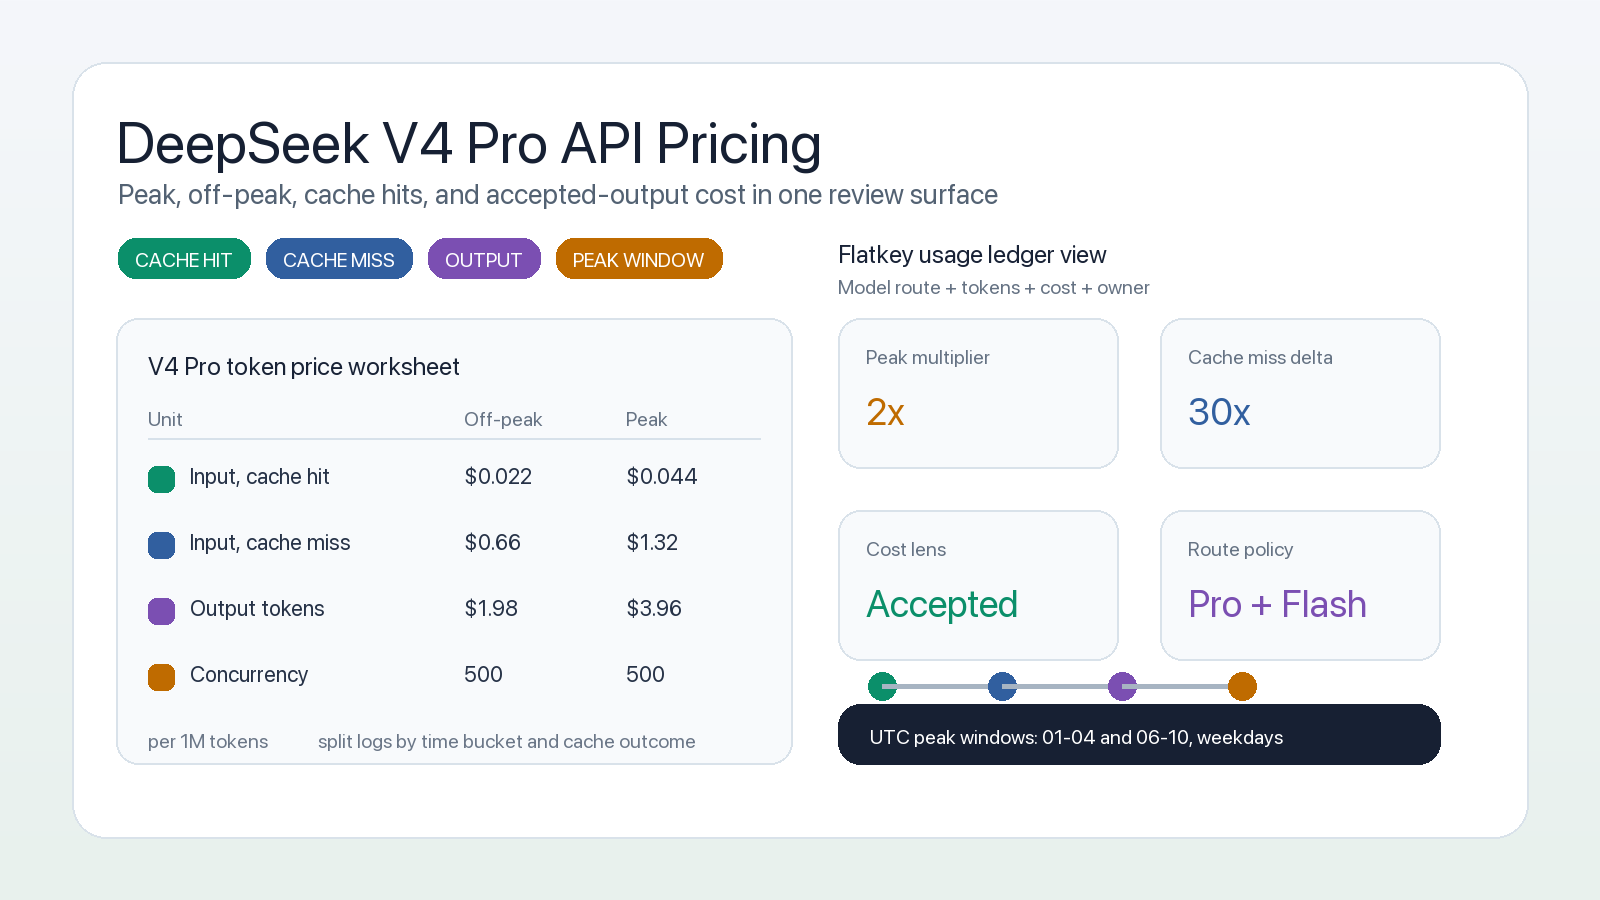
DeepSeek V4 Pro API Pricing: Peak, Off-Peak, and Cache Costs
Current DeepSeek V4 Pro API pricing with peak/off-peak rates, cache-hit math, and a cost-control worksheet for developers and procurement teams.
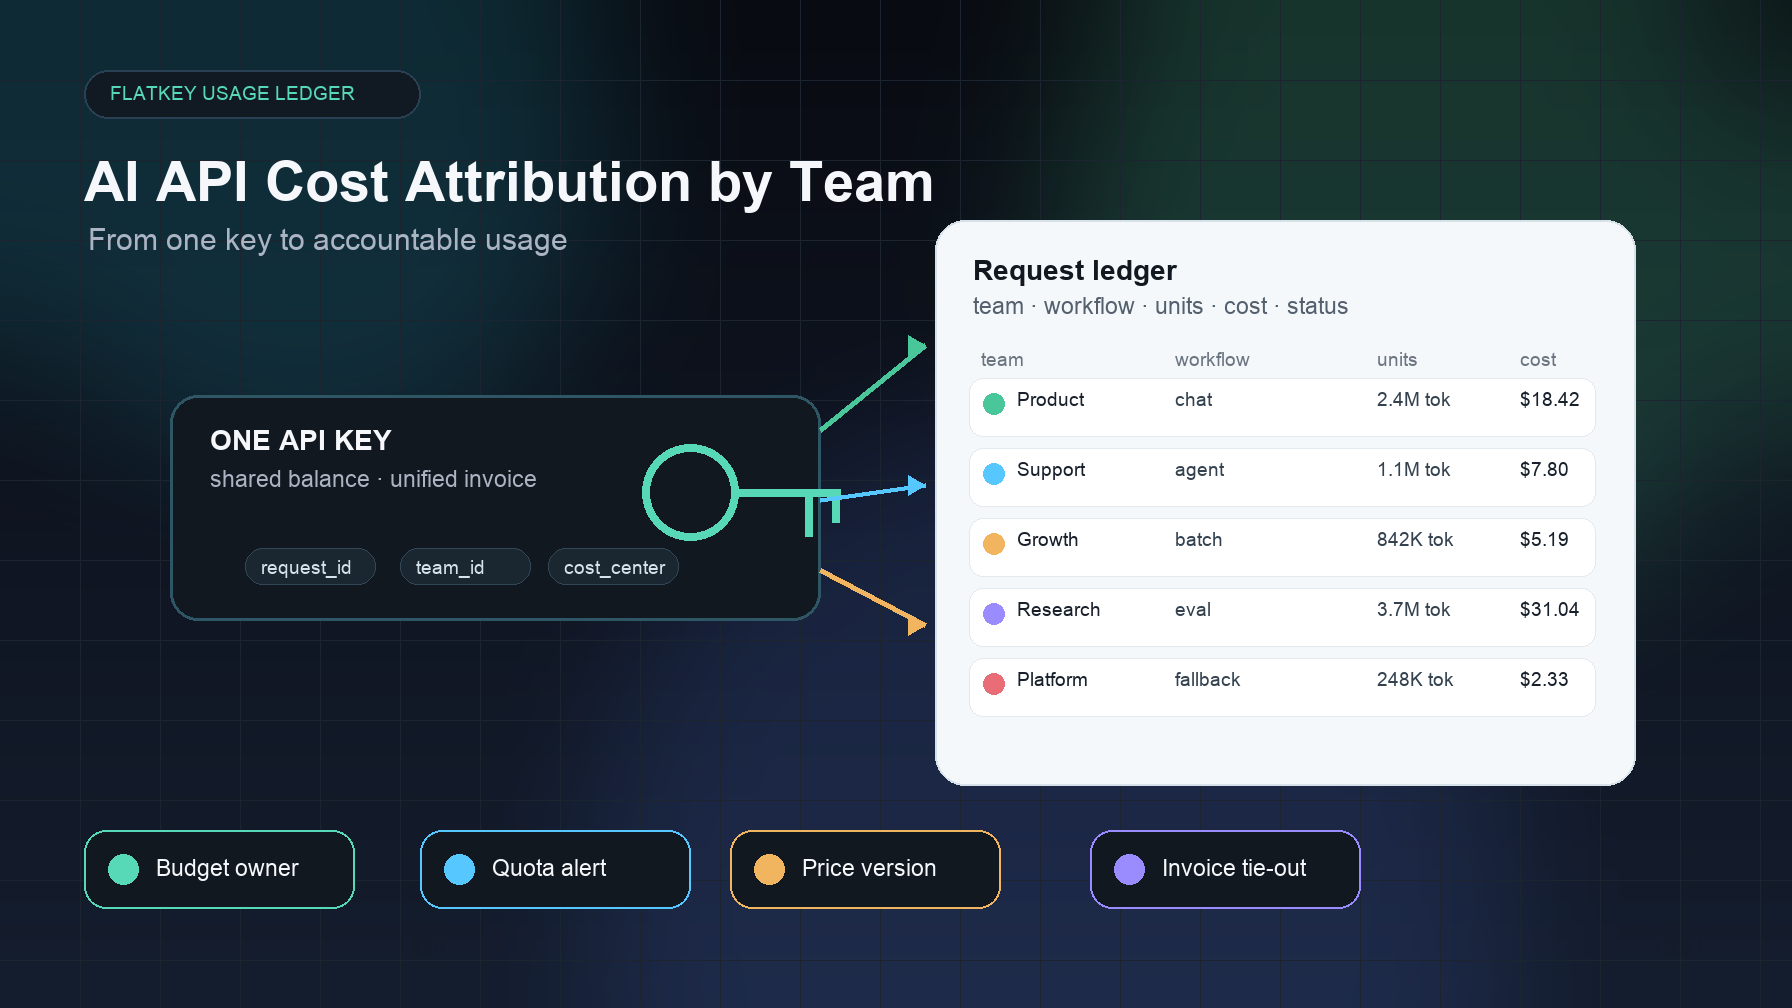
AI API Cost Attribution by Team: From One Key to Accountable Usage
Build AI API cost attribution by team with request tags, sub-key boundaries, usage ledgers, quotas, and monthly finance review.
Build faster with one AI gateway.
Use flatkey.ai to manage models, keys, billing, and observability from one API platform.
Get started