
Cost, Billing, and Ops
Latest articles in Cost, Billing, and Ops.
AI API Pricing Comparison (October 2026): OpenAI vs Claude vs Gemini vs Qwen vs DeepSeek vs Kimi
One dated table of official AI API prices for OpenAI, Claude, Gemini, Qwen, DeepSeek and Kimi in October 2026, plus discounts, promo end dates, worked monthly budgets, and a cost calculator.
SGLang Prefill Decode Disaggregation: Architecture and Deployment Guide
Deploy SGLang prefill decode disaggregation with separate GPU pools, KV-cache transfer, validation metrics, topology choices, and rollout checks.
KV Cache Offload and Tiering for Long-Context LLM Serving
KV cache offload and tiering guide for long-context LLM serving with vLLM and TensorRT-LLM.

Self-Hosted LLM Cost per Million Tokens: A Reproducible GPU Cost Model
A reproducible model for calculating self-hosted LLM serving cost from fully loaded GPU capacity, accepted throughput, utilization, and quality.
Build a Kubernetes GPU Cluster for AI Training and Inference
A practical Kubernetes GPU cluster guide for AI training and inference, covering GPU node pools, device plugins, GPU Operator, queueing, storage, observability, security, cost controls, and provider due diligence.
ComfyUI on a Cloud GPU: Setup, Storage, and Cost Guide
A practical guide to deploying ComfyUI on a cloud GPU with persistent storage, private access, workload-based GPU selection, and cost controls.

vLLM Expert Parallel Deployment for DeepSeek and Other MoE Models
Deploy vLLM expert parallel for DeepSeek and other MoE models with the right flags, topology, backend checks, and rollout tests.
Ollama Cloud GPU: Run a Secure Remote API Server
A secure Docker and HTTPS-proxy workflow for running Ollama on a cloud GPU and serving a remote /api or OpenAI-compatible /v1 endpoint.
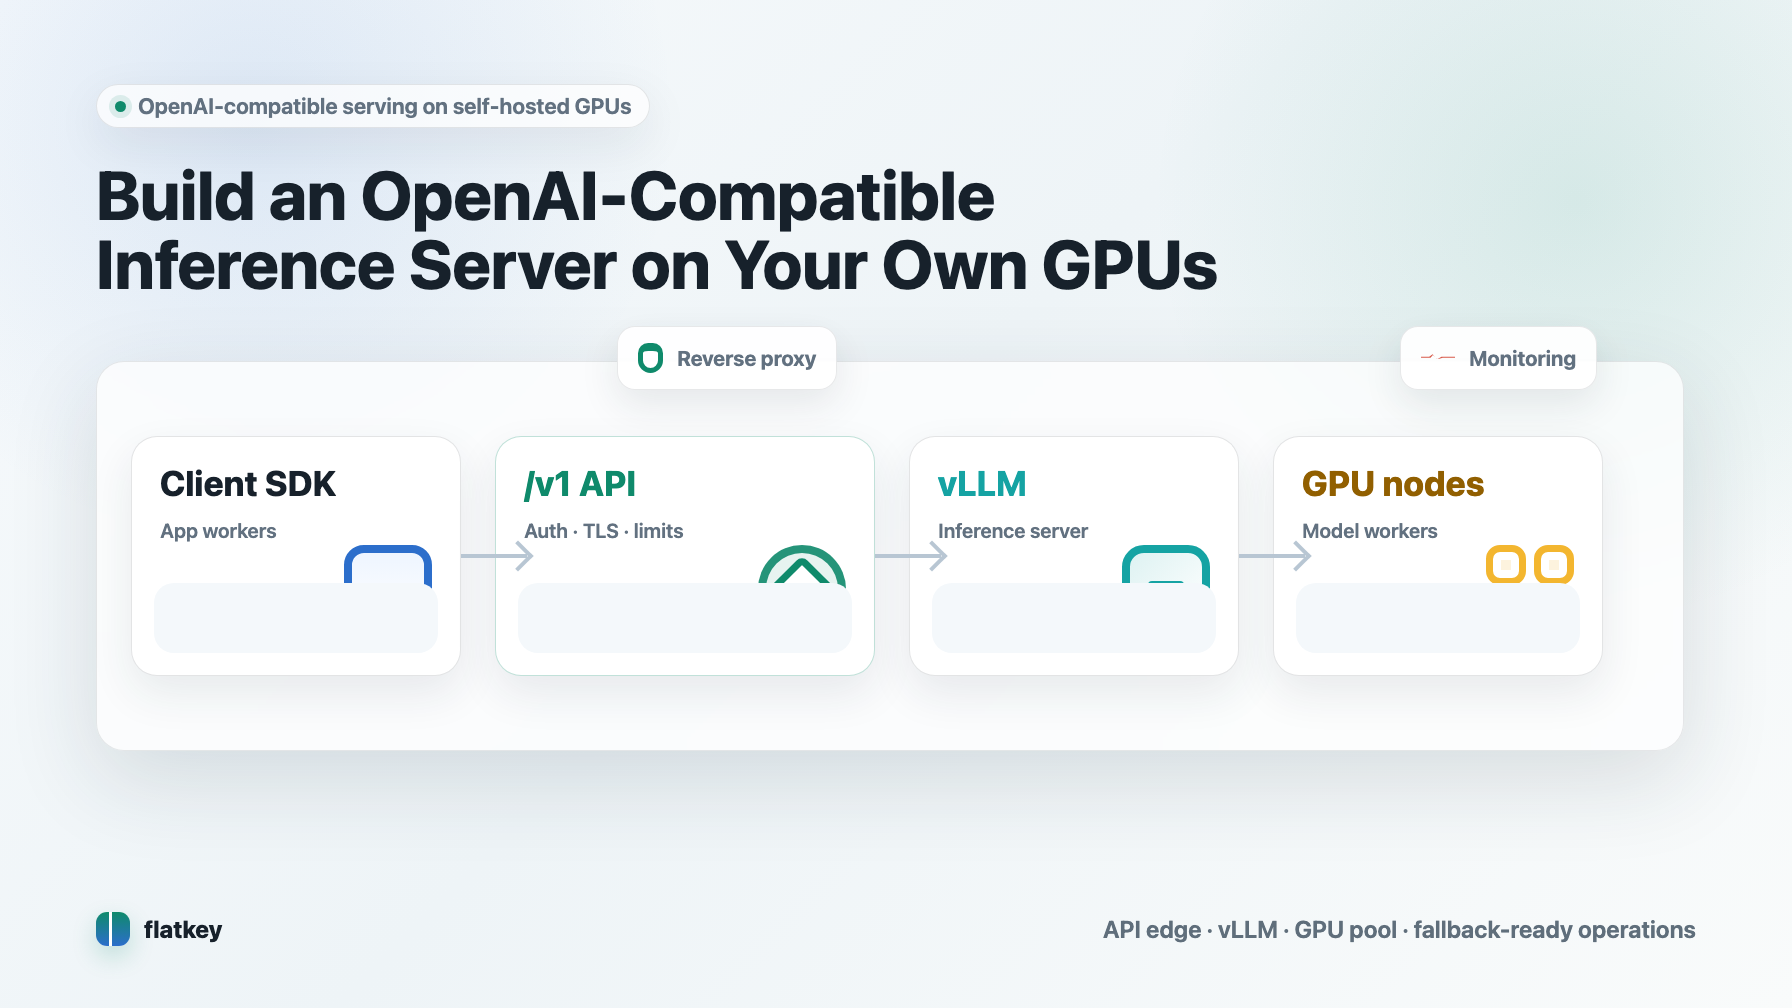
Self-Hosted LLM Guide (2026): When It Pays Off, What Hardware You Need, and How to Serve It
A self-hosted LLM runs open-weight models on GPUs you control. Learn when it beats per-token API pricing (with October 2026 GPU rates), how to size GPU memory, which serving tool to pick, and how to deploy an OpenAI-compatible vLLM server with a fallback.
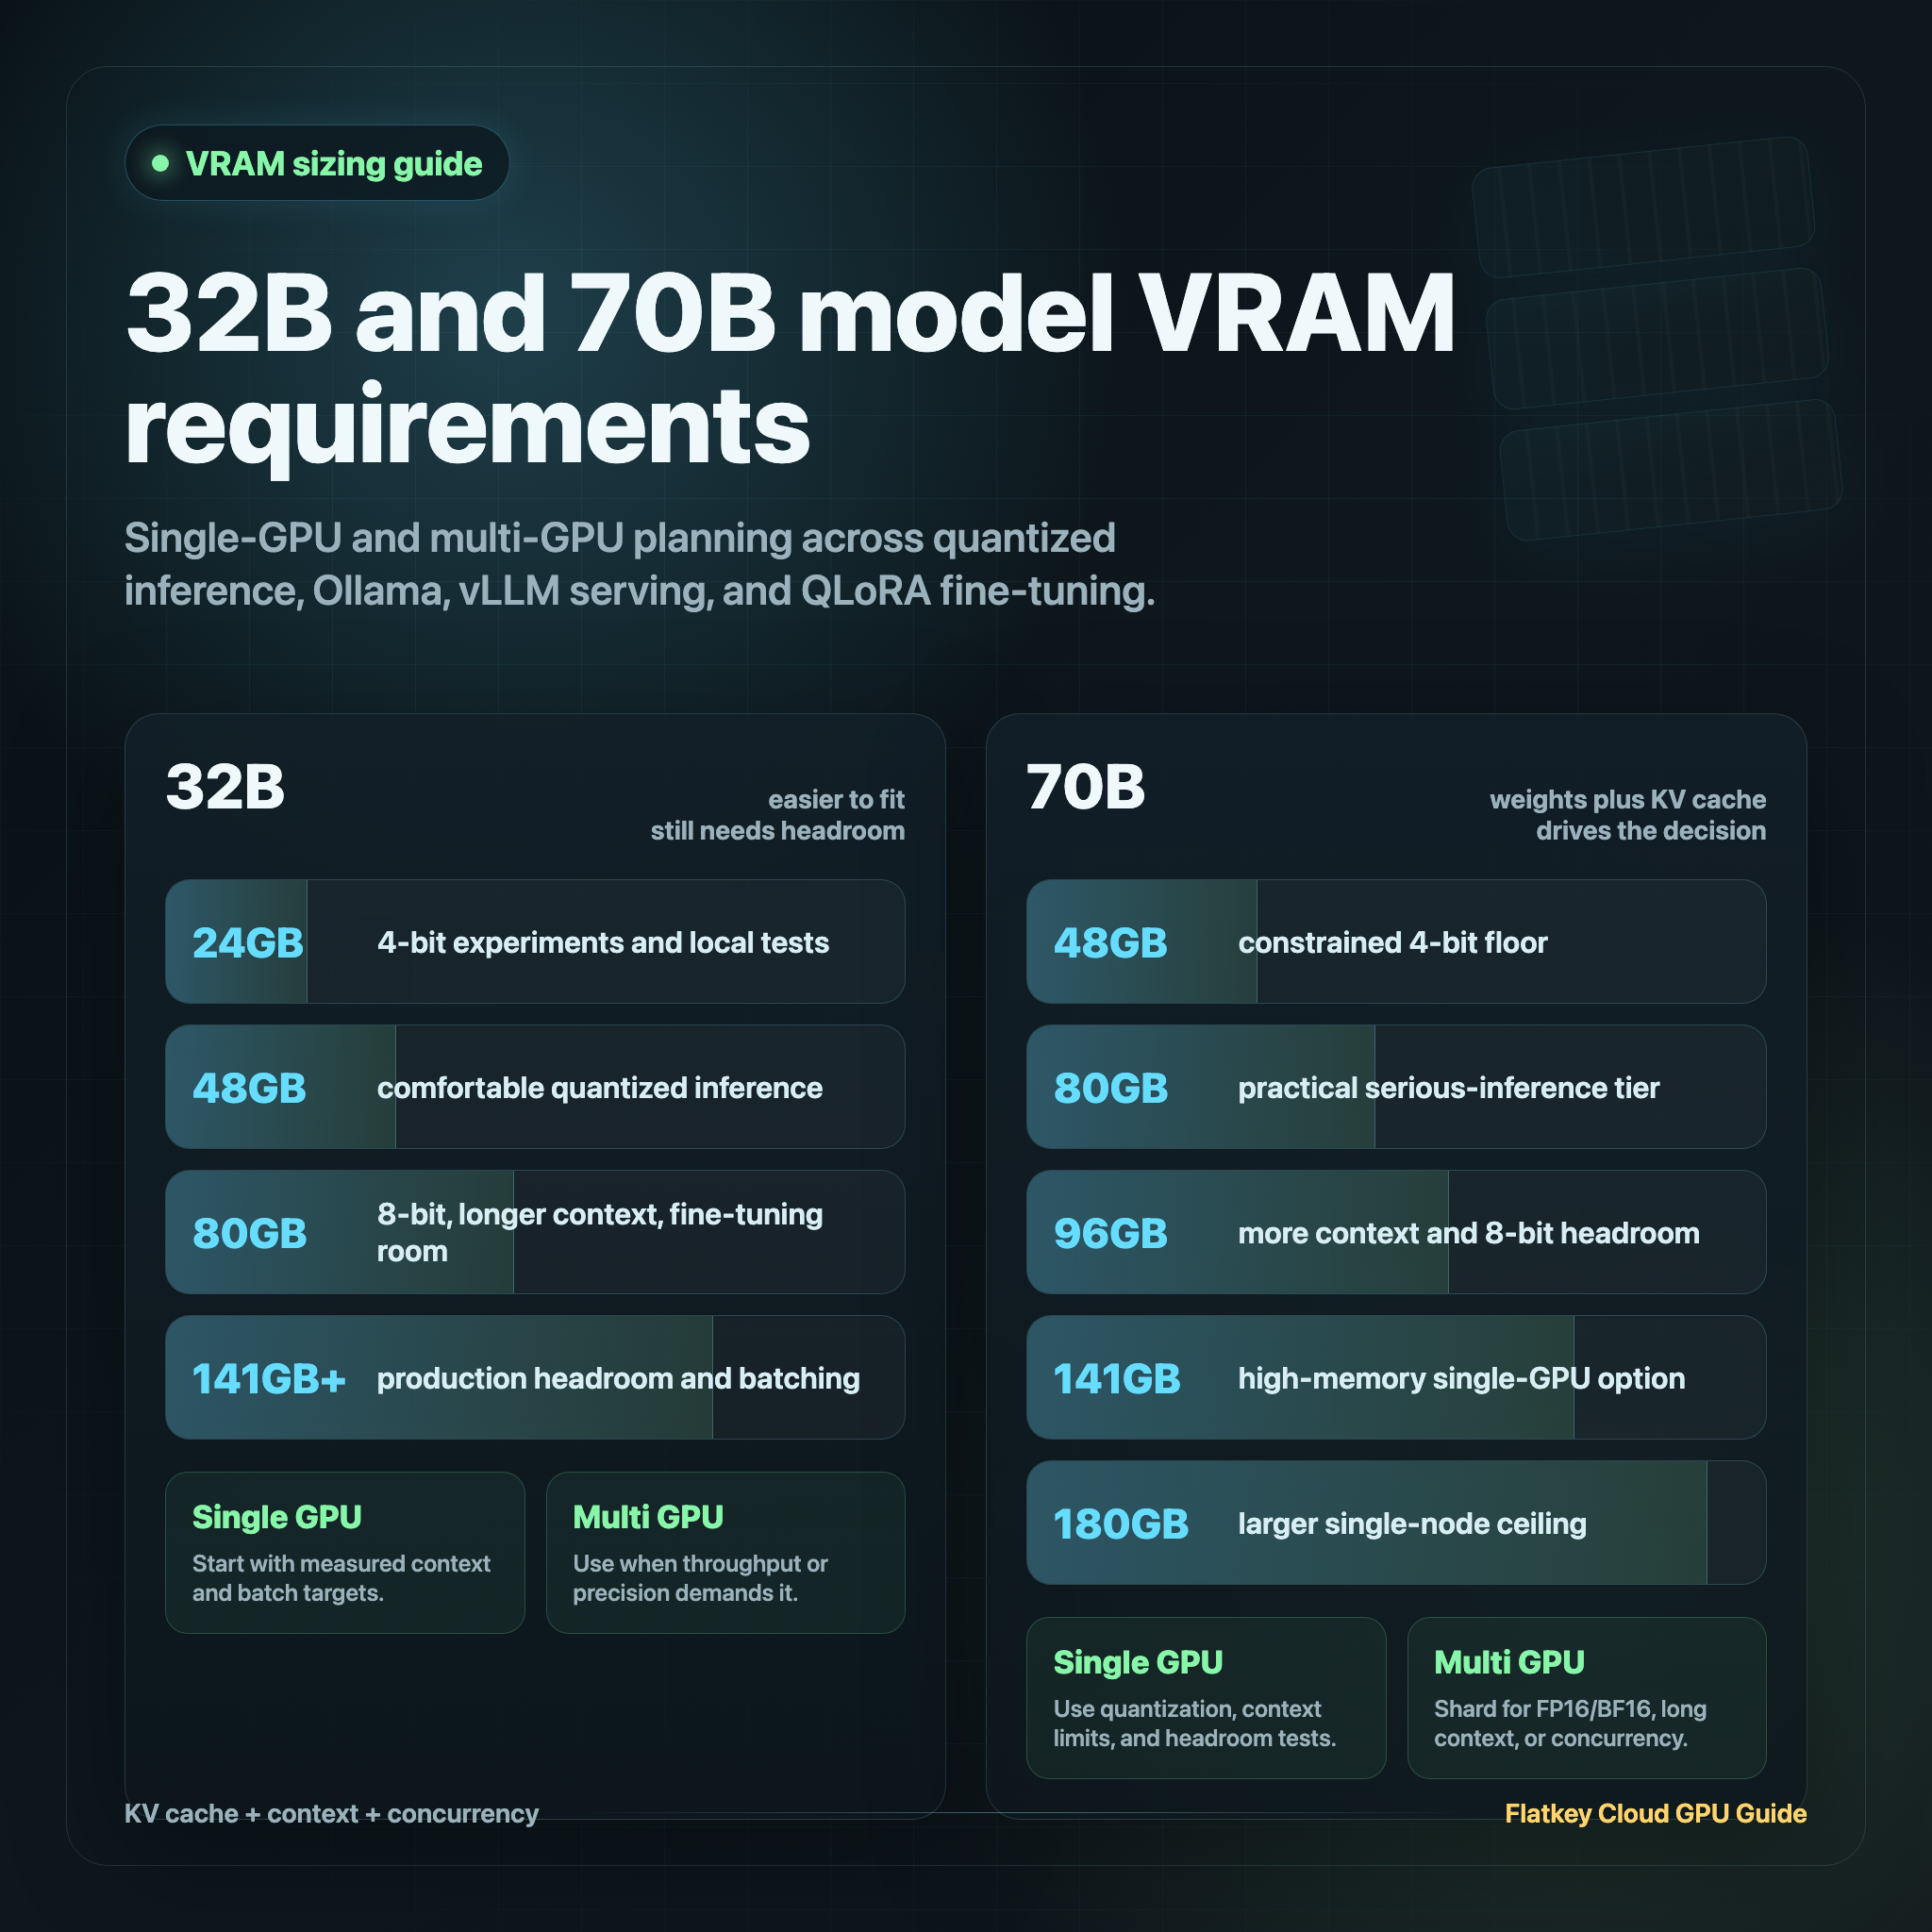
32B and 70B Model VRAM Guide: Single-GPU and Multi-GPU Options
Learn practical 32B and 70B model VRAM requirements for 4-bit, 8-bit, FP16/BF16 inference, Ollama, QLoRA fine-tuning, and multi-GPU options.
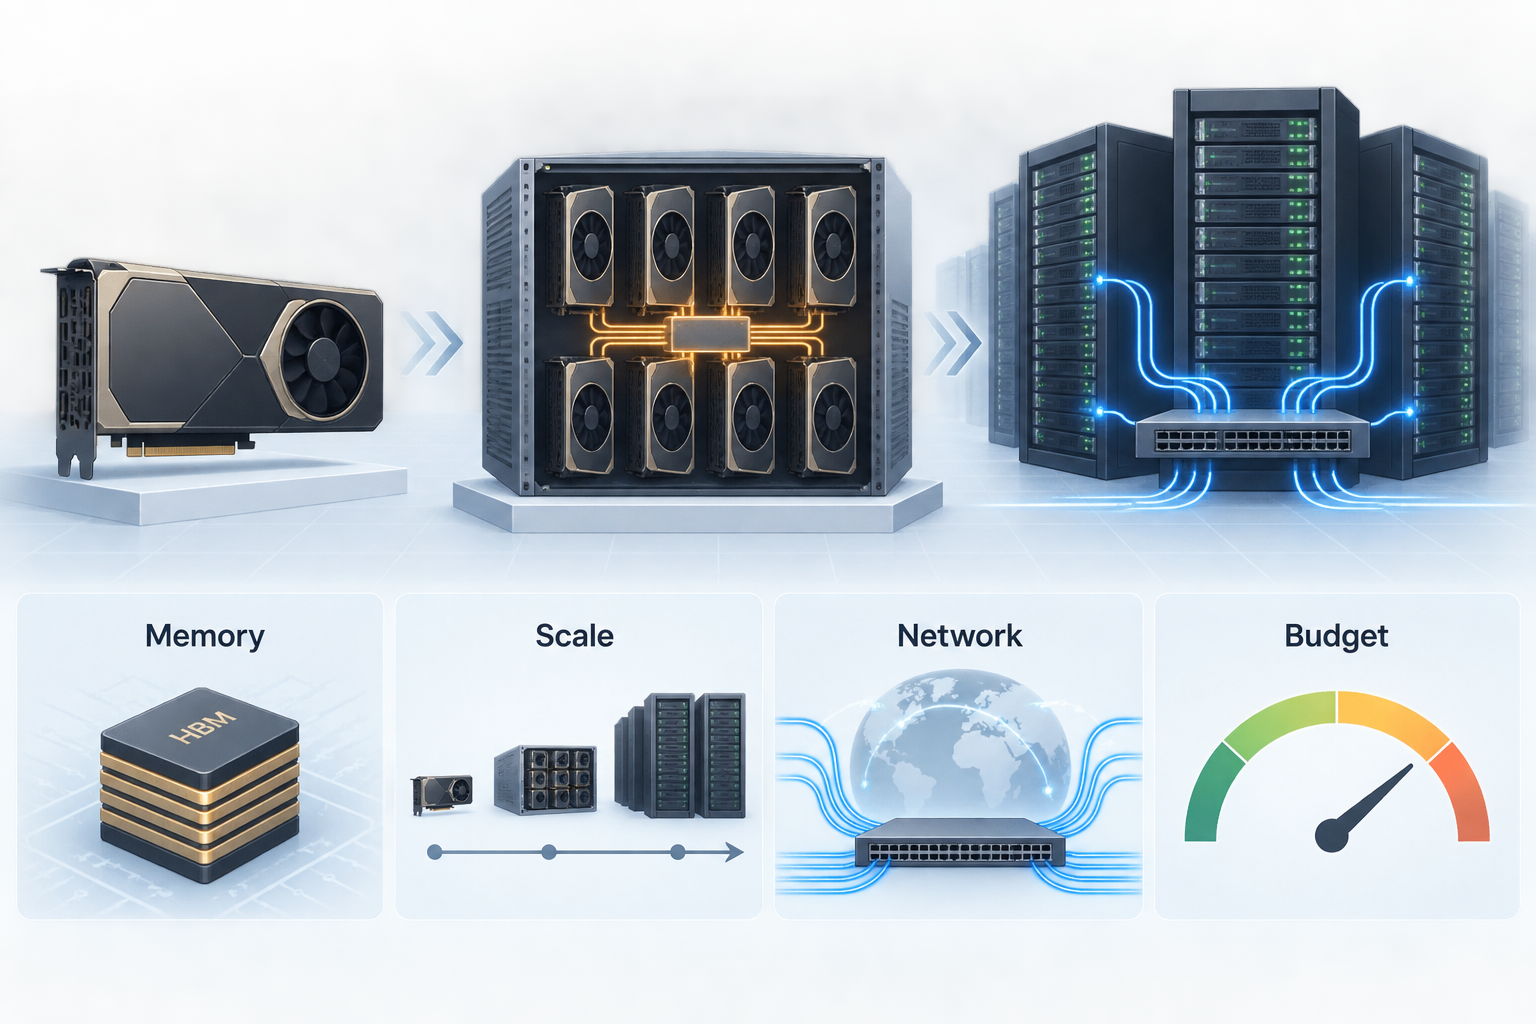
Best GPU for LLM Training: Scale, Memory, Networking, and Budget
A practical 2026 guide to choosing the best GPU for LLM training by scale, memory, networking, provider fit, and cost per finished checkpoint.
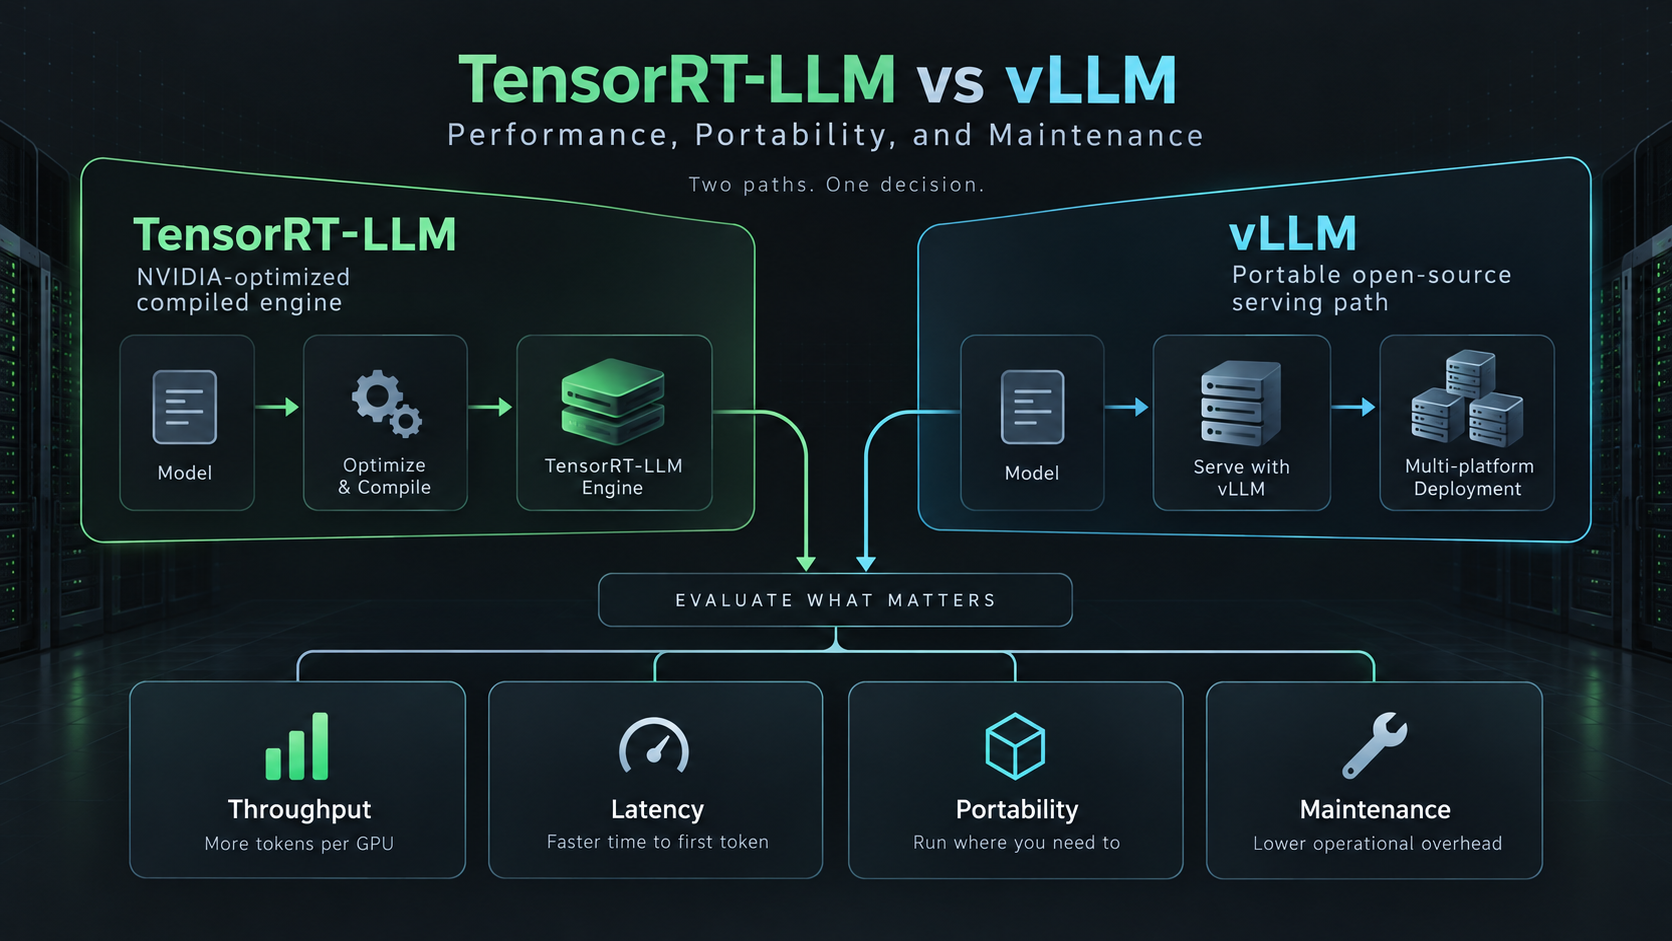
TensorRT-LLM vs vLLM: Performance, Portability, and Maintenance
A practical TensorRT-LLM vs vLLM comparison for AI infrastructure teams choosing an LLM serving engine across performance, portability, maintenance, and benchmark design.
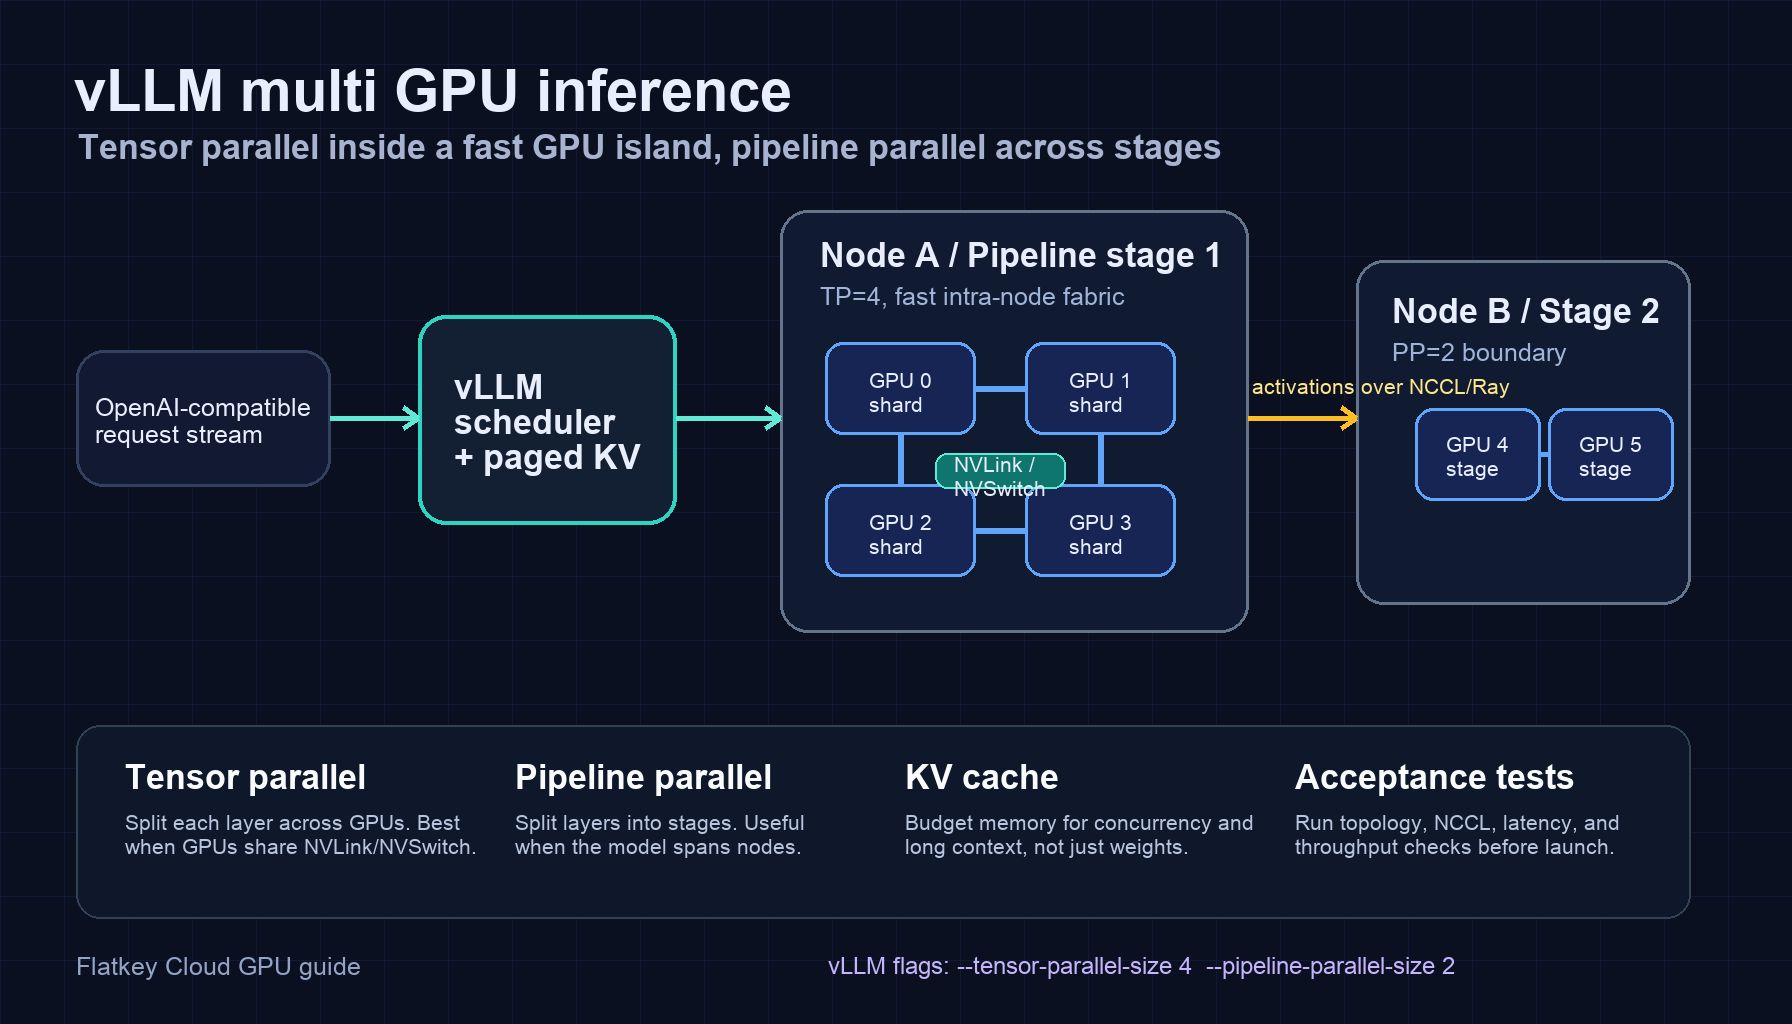
vLLM Multi-GPU Inference: Tensor and Pipeline Parallel Setup
Set up vLLM multi GPU inference with tensor parallelism, pipeline parallelism, Ray, topology checks, examples, and production tests.
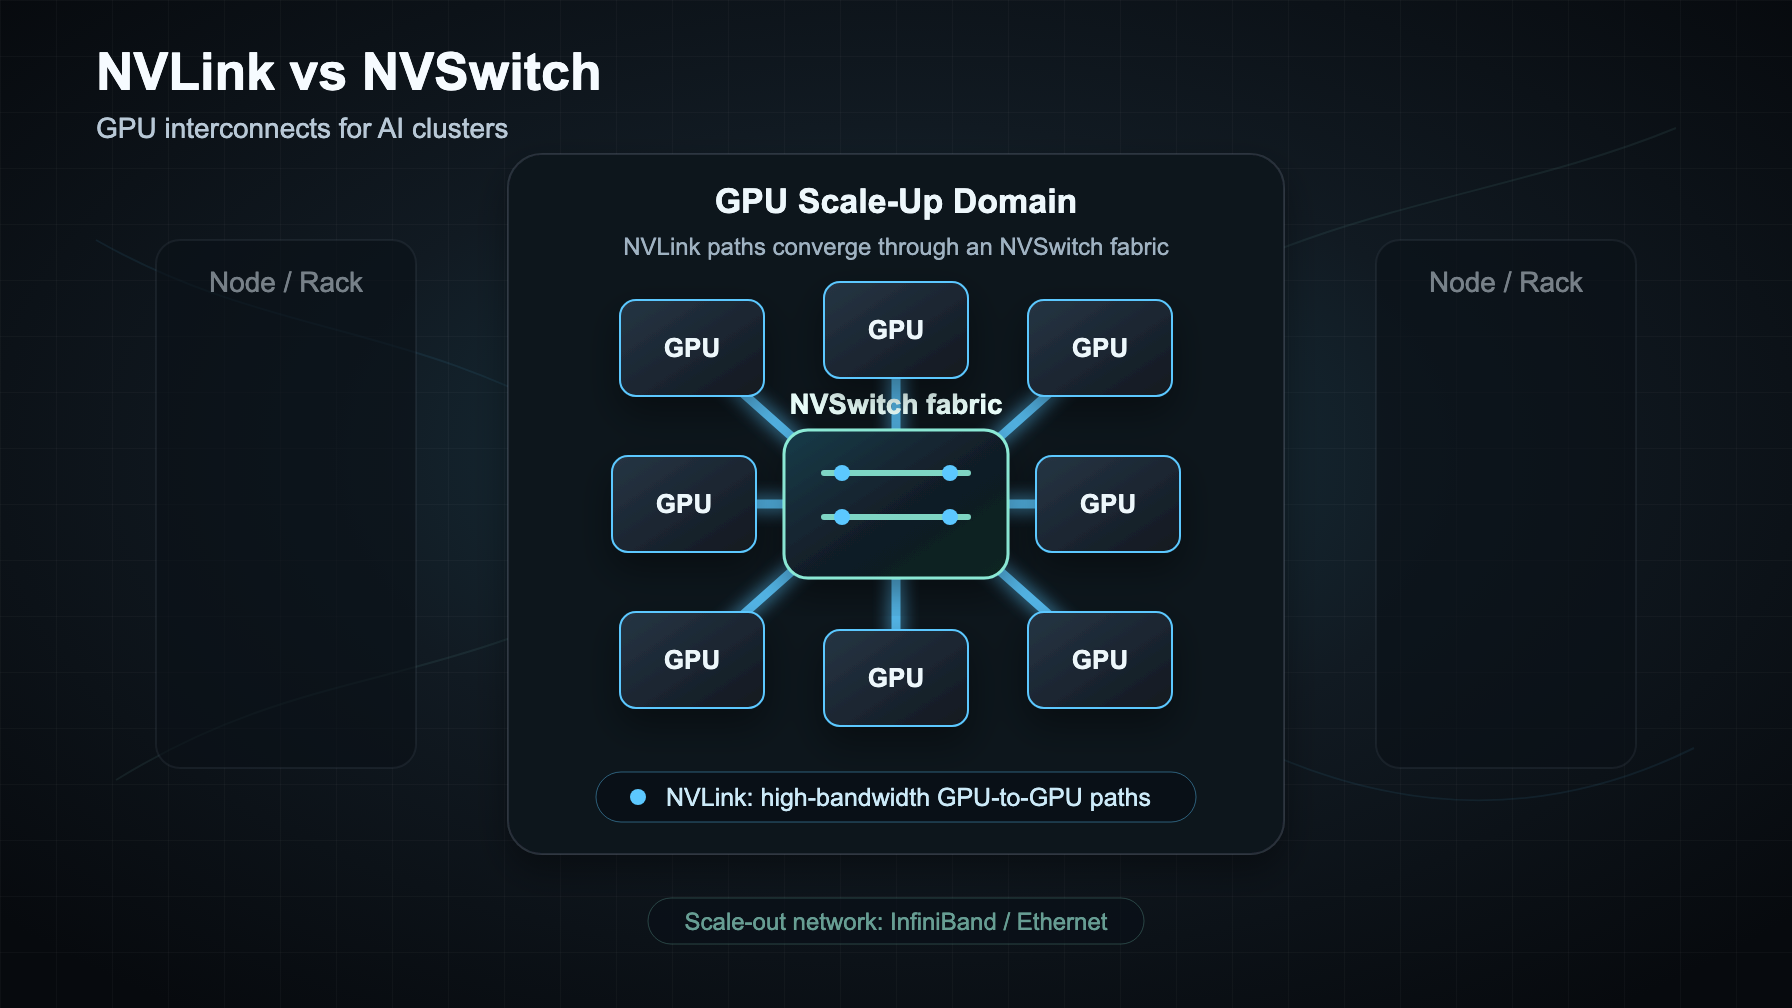
NVLink vs NVSwitch: GPU Interconnects Explained for AI Clusters
NVLink is the GPU-to-GPU link, NVSwitch is the fabric, and InfiniBand or Ethernet is the scale-out network. Here is how to choose for AI clusters.
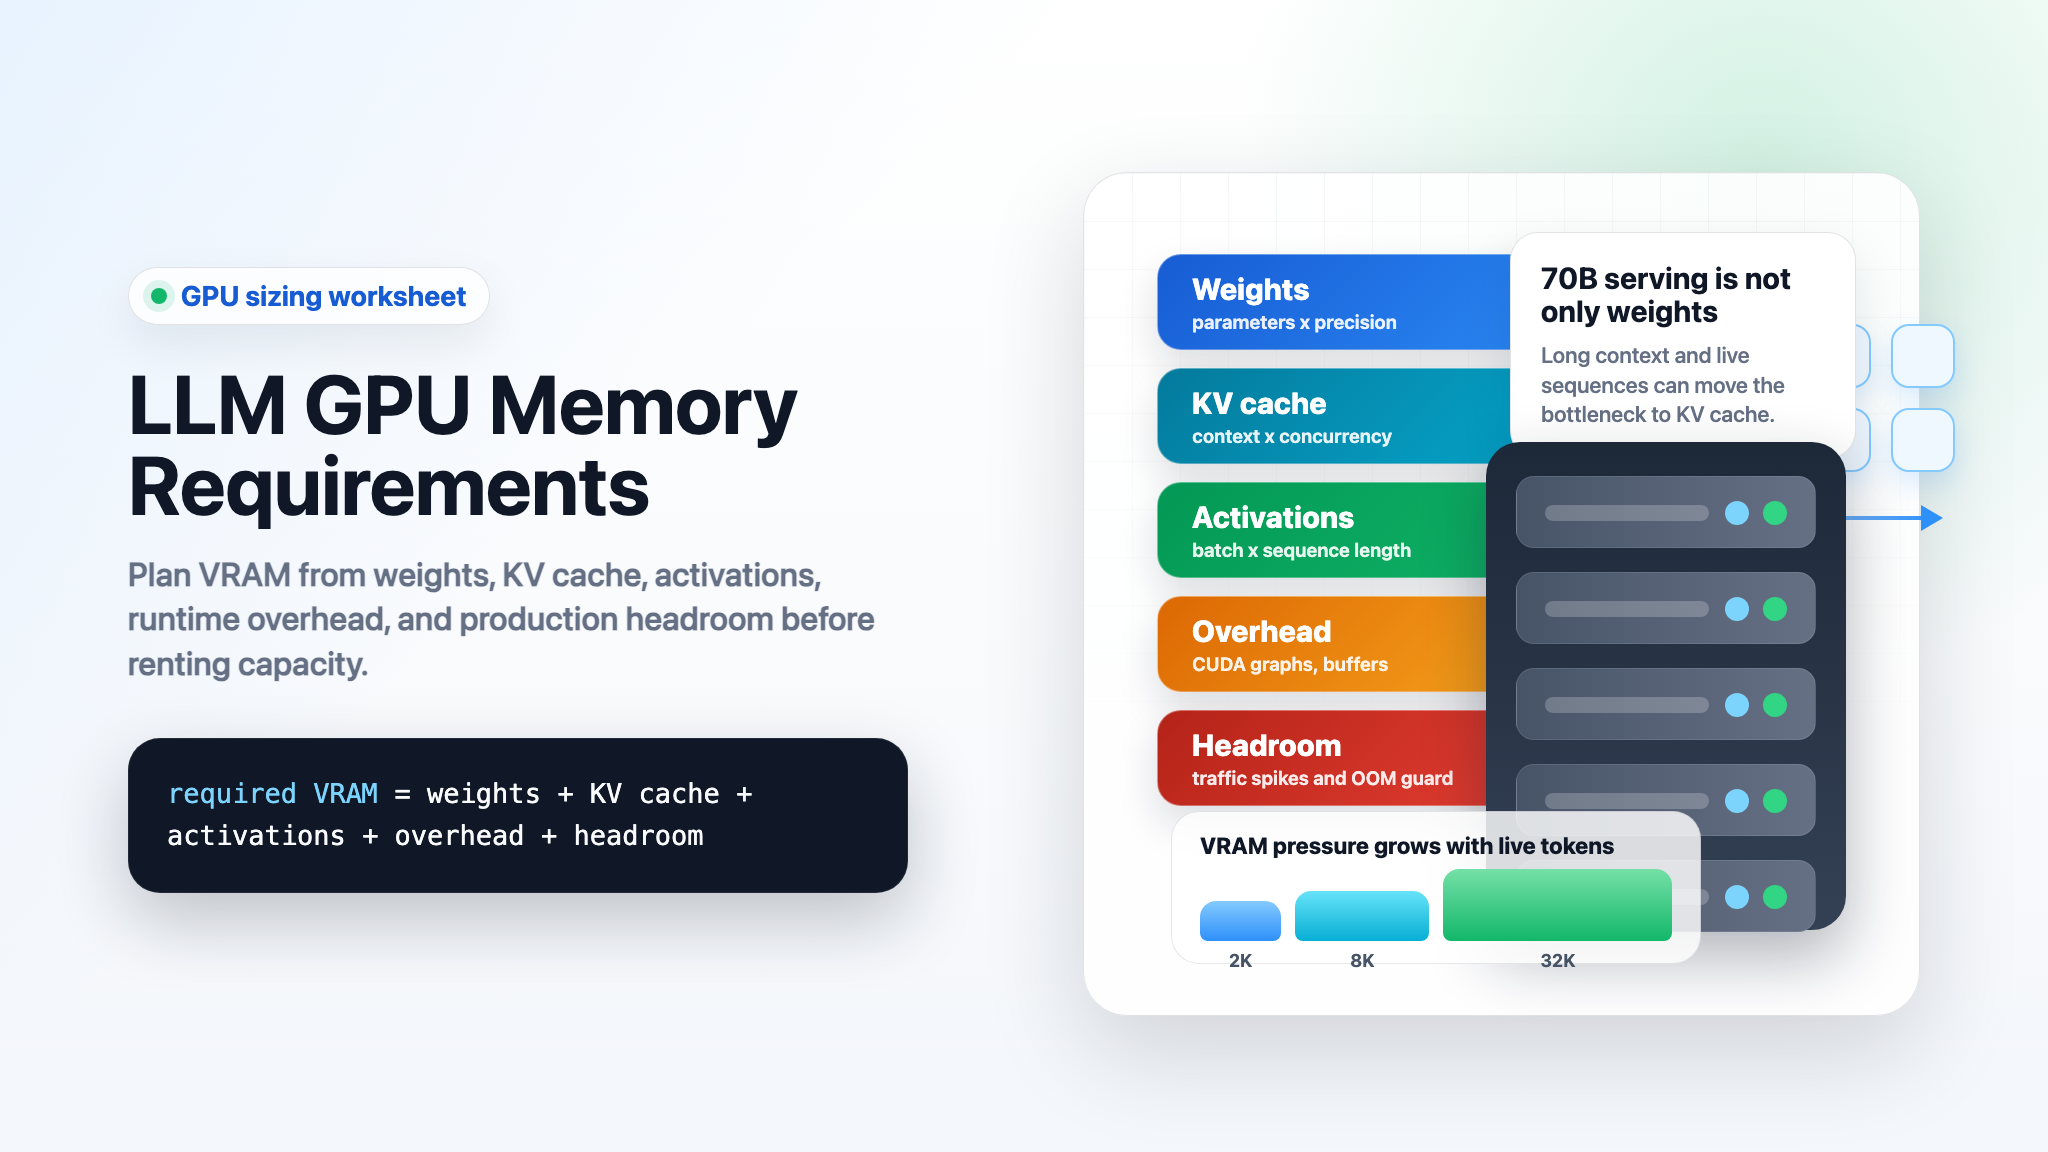
LLM GPU Memory Requirements: Weights, KV Cache, Activations, and Overhead
A practical worksheet for estimating LLM GPU memory requirements across weights, KV cache, activations, serving overhead, vLLM 70B planning, fine-tuning, and training.
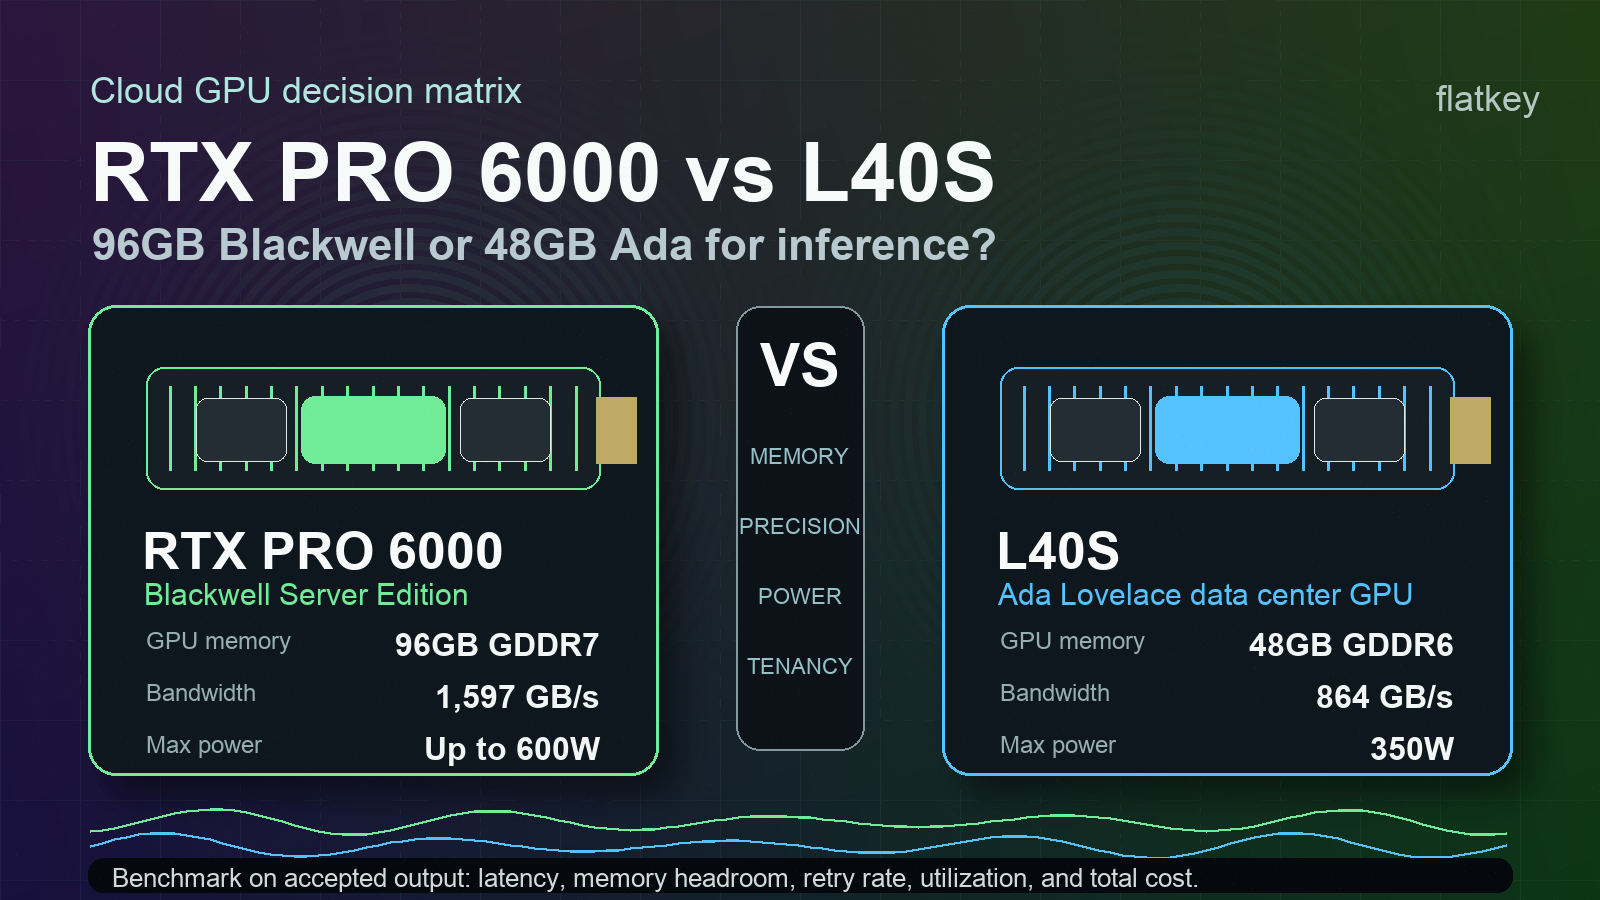
RTX PRO 6000 vs L40S: 96GB Blackwell or Ada Inference GPU?
Compare NVIDIA L40S vs RTX PRO 6000 Blackwell Server Edition for LLM inference, multimodal workloads, memory fit, power, and accepted-output cost.
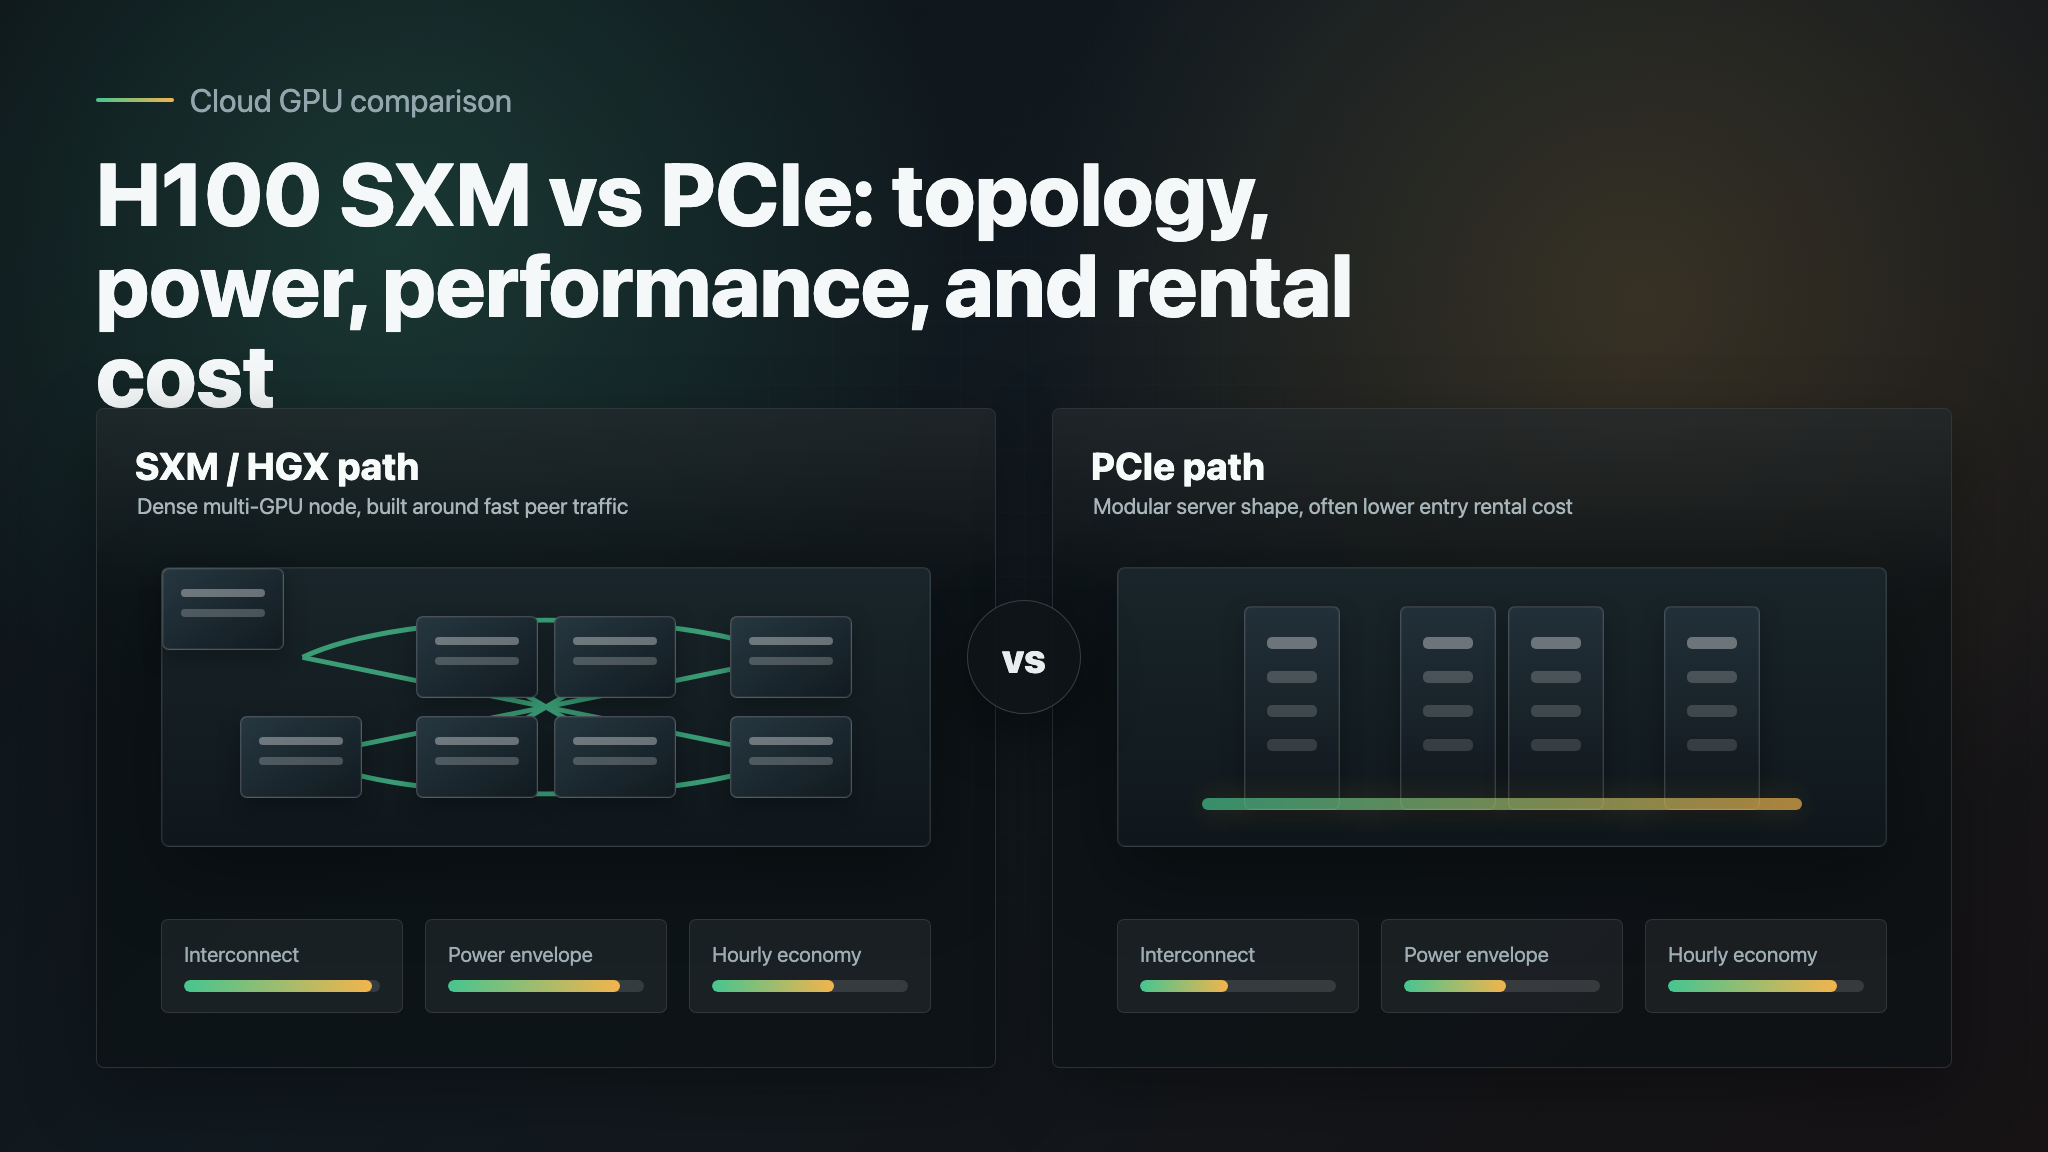
H100 SXM vs PCIe: NVLink, Power, Performance, and Rental Cost
Compare H100 PCIe vs SXM for NVLink, power consumption, workload performance, and rental cost before renting cloud GPUs.
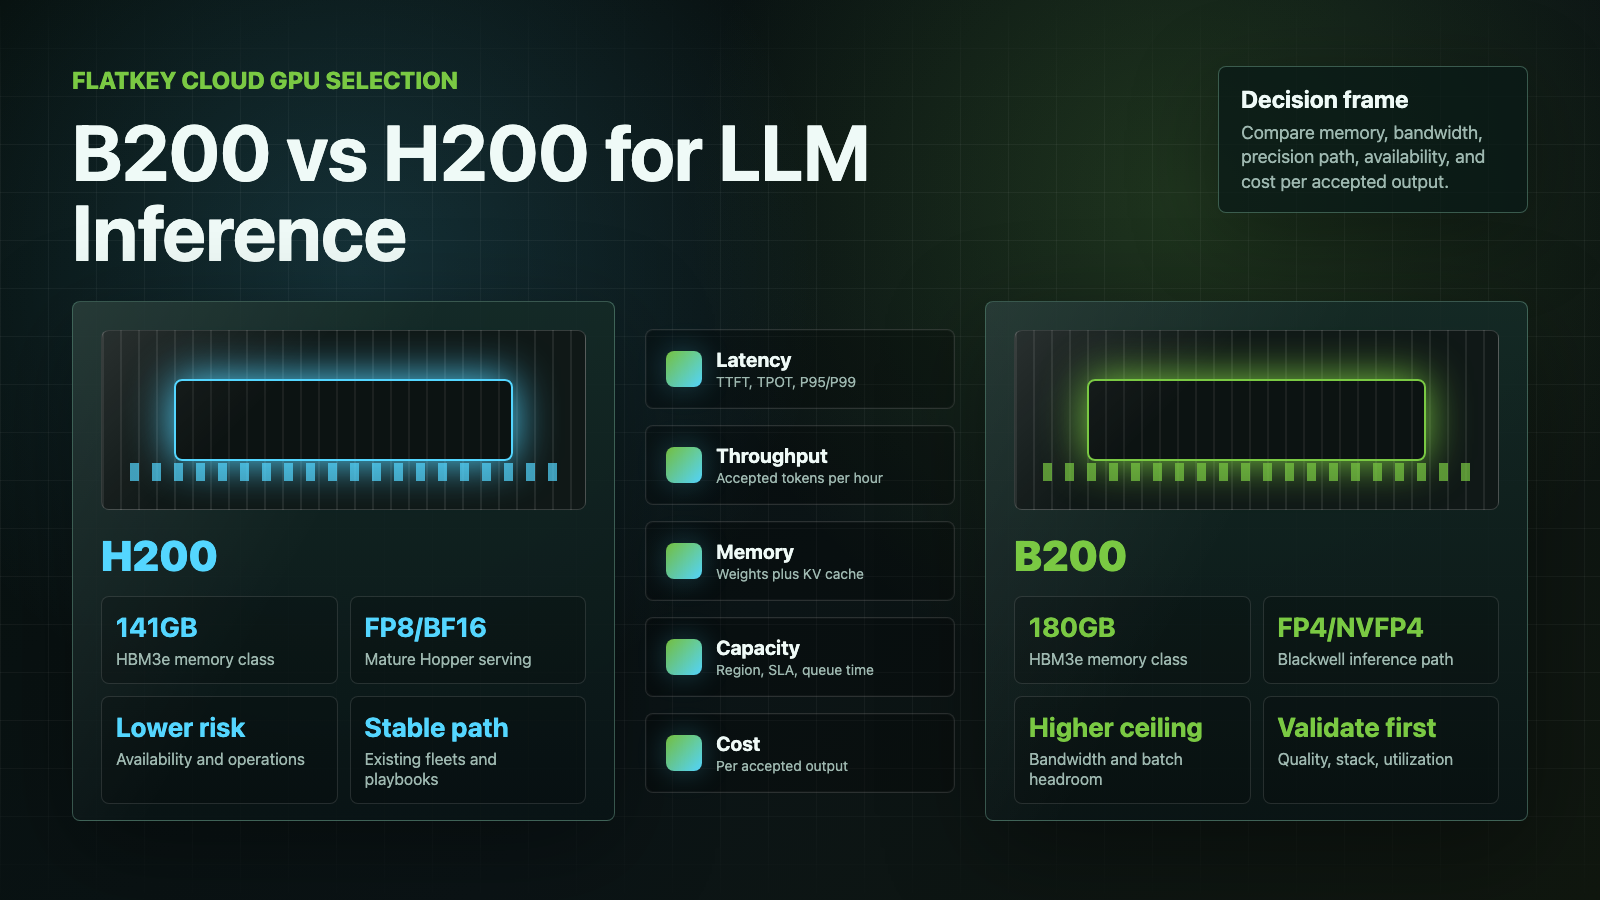
NVIDIA B200 vs H200: Which GPU Is Better for LLM Inference?
Compare NVIDIA B200 vs H200 for LLM inference by memory, bandwidth, precision support, DGX systems, cloud GPU availability, and cost per accepted output.
Build faster with one AI gateway.
Use flatkey.ai to manage models, keys, billing, and observability from one API platform.
Get started