
Reliability and Routing
Latest articles in Reliability and Routing.
Claude API Access Outside One-Region Setups: A Compliance-First Guide
A compliance-first guide to Claude API access across regions, covering direct Anthropic, Bedrock, Vertex AI, gateways, testing, observability, and approved failover.
Seedance 2.0 API Guide: Access, Pricing, and Routing (2026)
A practical Seedance 2.0 API guide to access, pricing, asynchronous jobs, capability checks, and fallback routing for production video products.
Seedance API production checklist for text-to-video teams
A practical production checklist for operating Seedance text-to-video jobs with durable queues, normalized states, safe retries, storage, and cost controls.
Gemini API for AI Agents: Production Integration Checklist
A production checklist for Gemini-powered agents covering stable endpoints, controlled model switching, tool safety, retries, fallback routing, and cost visibility.
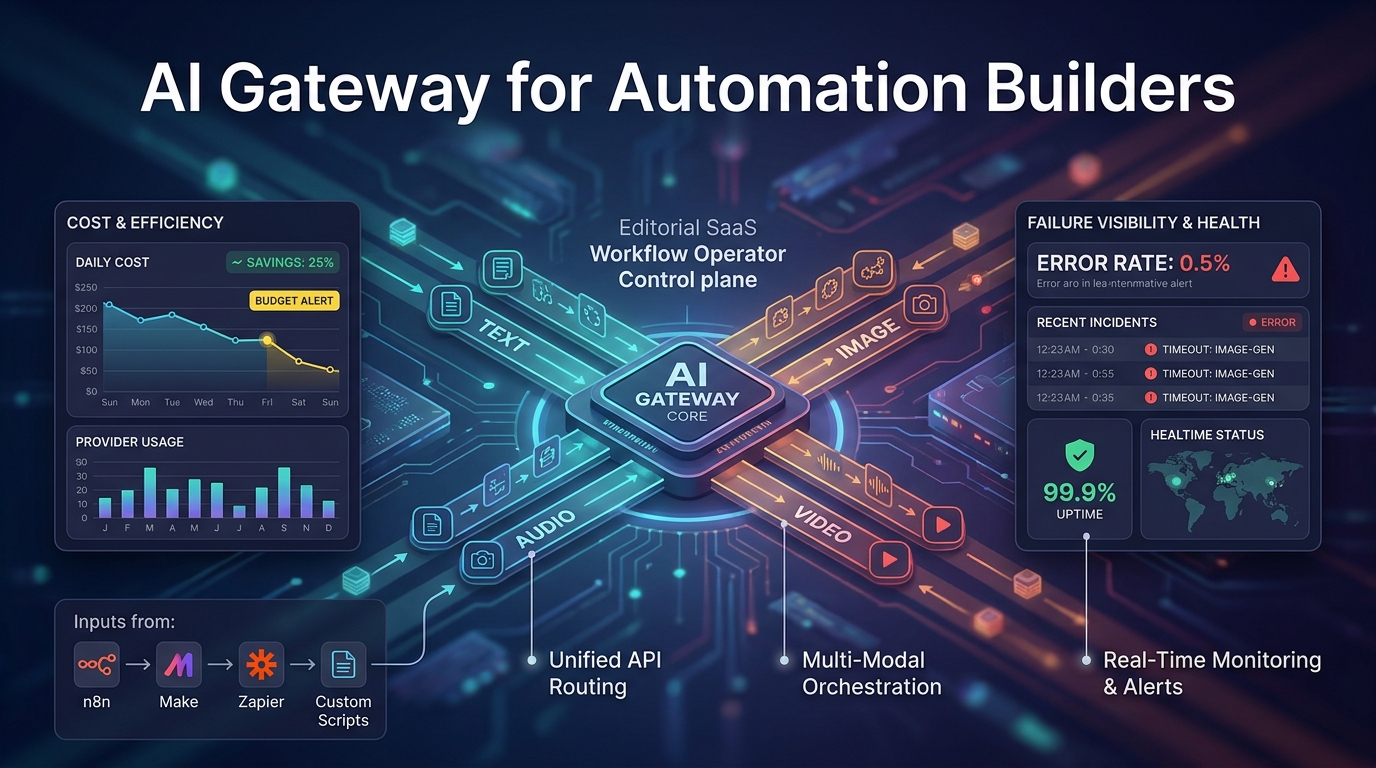
AI Gateway for Automation Builders: Fallback Routing, Cost Visibility, and One Base URL
Why automation builders need one AI gateway for stable base URLs, safer fallback routing, and easier cost review across high-volume workflows.

Multi-Upstream Account Pooling: Reliability Checks Before Sharing Model Traffic
A production checklist for safe multi-upstream account pooling across AI model accounts, with health checks, quotas, billing evidence, and fail-closed routing rules.

Model Fallback Quality Testing: When Cheaper or Faster Models Are Not Equivalent
A practical model fallback quality testing plan for proving cheaper or faster backup models preserve quality, cost, tools, policy, and observability before production routing.

LLM Router: How Model Routing Works, Strategies, and Safe Canary Rollouts (2026)
How LLM routers choose a model per request, the five routing strategies with runnable code, the best open-source and hosted routers, and a canary rollout runbook.

AI API Queueing Strategy: Protect User-Facing Workflows During Provider Outages
A production reliability playbook for protecting user-facing AI workflows with queue lanes, backpressure, fallback contracts, dead-letter rules, and route evidence.

LLM Gateway Error Taxonomy: Separate Auth, Quota, Provider, and Safety Failures
A production reliability playbook for classifying LLM gateway failures into auth, quota, provider, request, safety, and cancellation paths before retry or fallback.

API Rate Limit Exceeded: What It Means and How to Fix It (2026)
What "API rate limit exceeded" means, how major APIs enforce limits in 2026, and step-by-step fixes: Retry-After, exponential backoff code in Python and Node, rate limiters, caching, queues, and higher tiers.

AI API Timeout Strategy: Connect, Read, Stream, and Queue Budgets
Set production AI API timeout budgets for connect, read, stream, queue, retry, fallback, and observability before incidents become expensive.
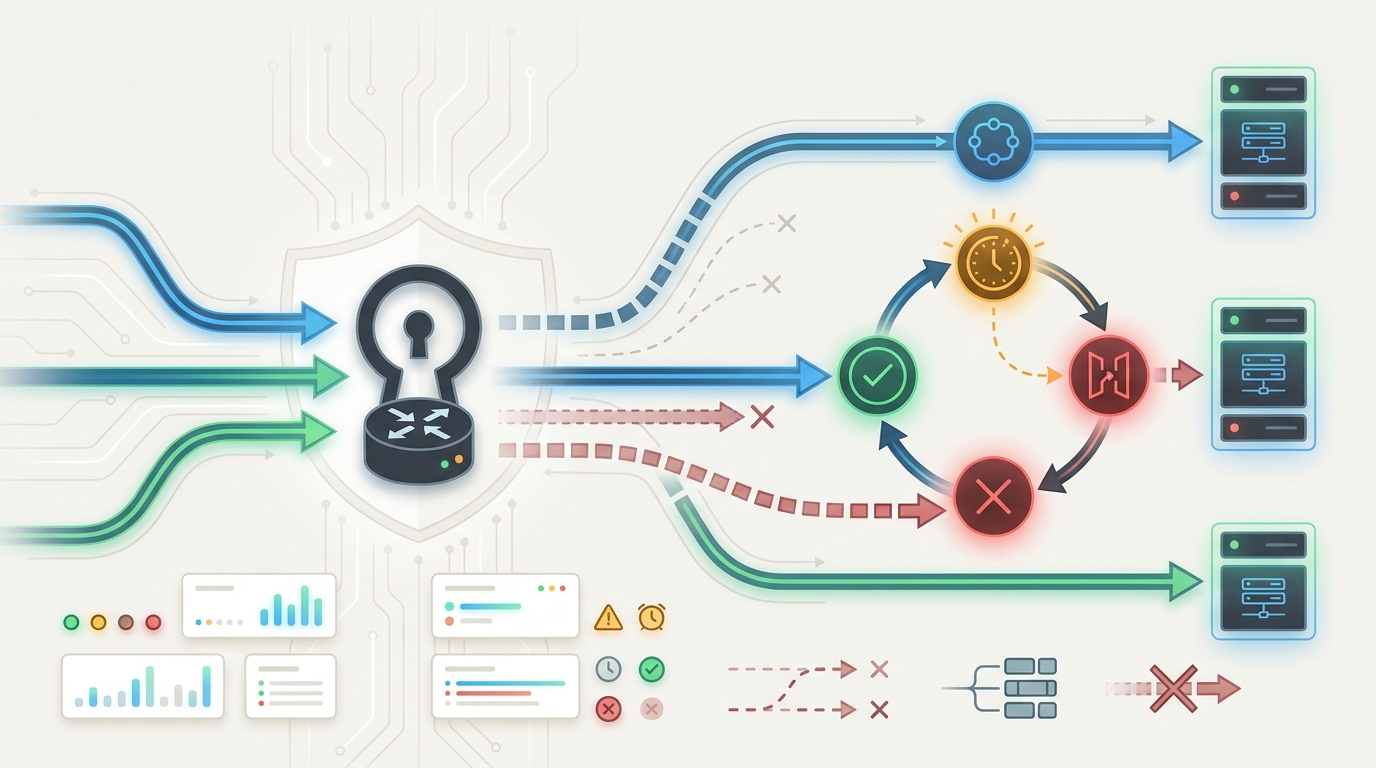
Circuit Breakers for LLM API Gateways: Protect Apps From Provider Failure Loops
Use an LLM API gateway circuit breaker to stop provider failure loops, classify errors, protect retries, and route to fallback, queue, or fail closed.
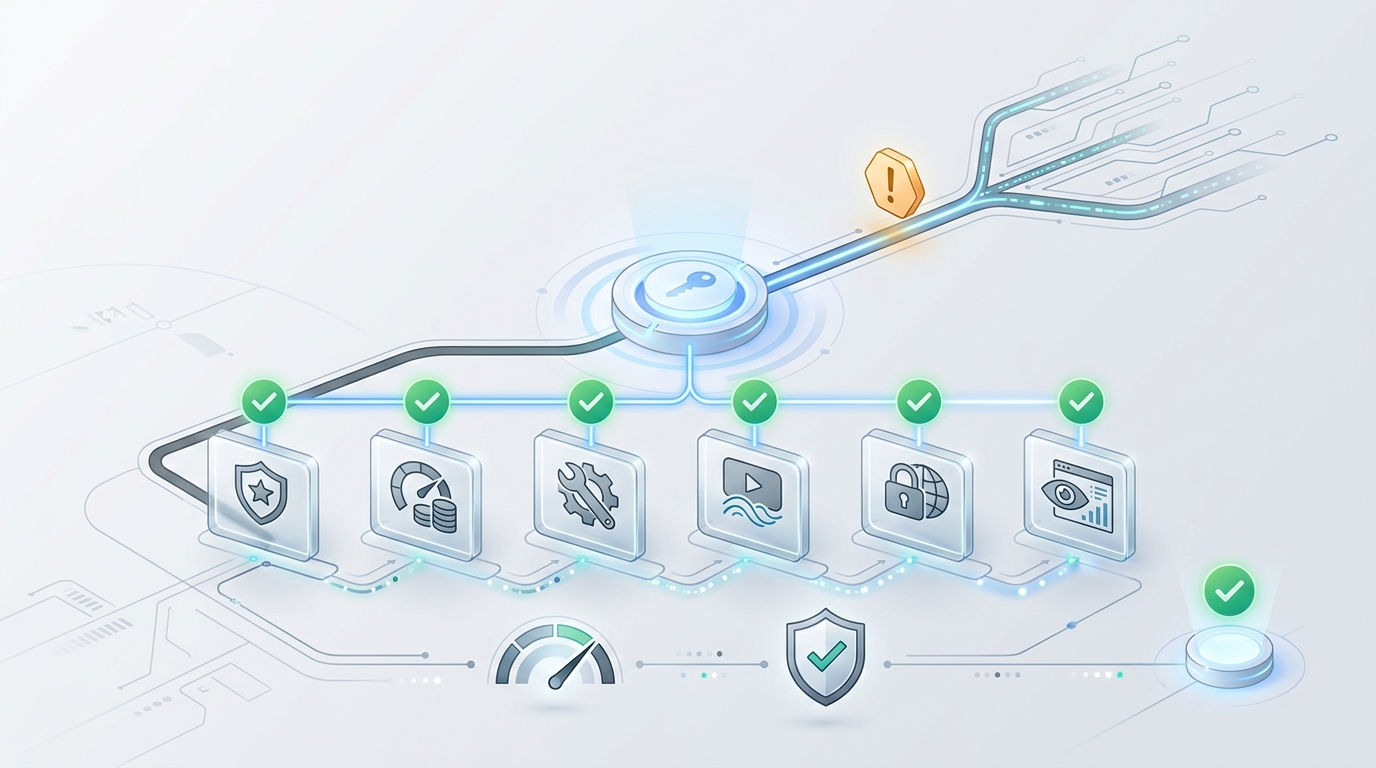
Model Fallback Checklist: Quality, Cost, Tools, and Compliance Boundaries
Use this model fallback checklist to evaluate quality, cost, tools, streaming, compliance, logs, and rollback before automatic AI gateway fallback.
Streaming AI API Reliability: SSE, Timeouts, and Router-Level Failure Modes
Use streaming AI API reliability tests to catch SSE stalls, proxy timeouts, partial outputs, retry risks, and router failover gaps before production.
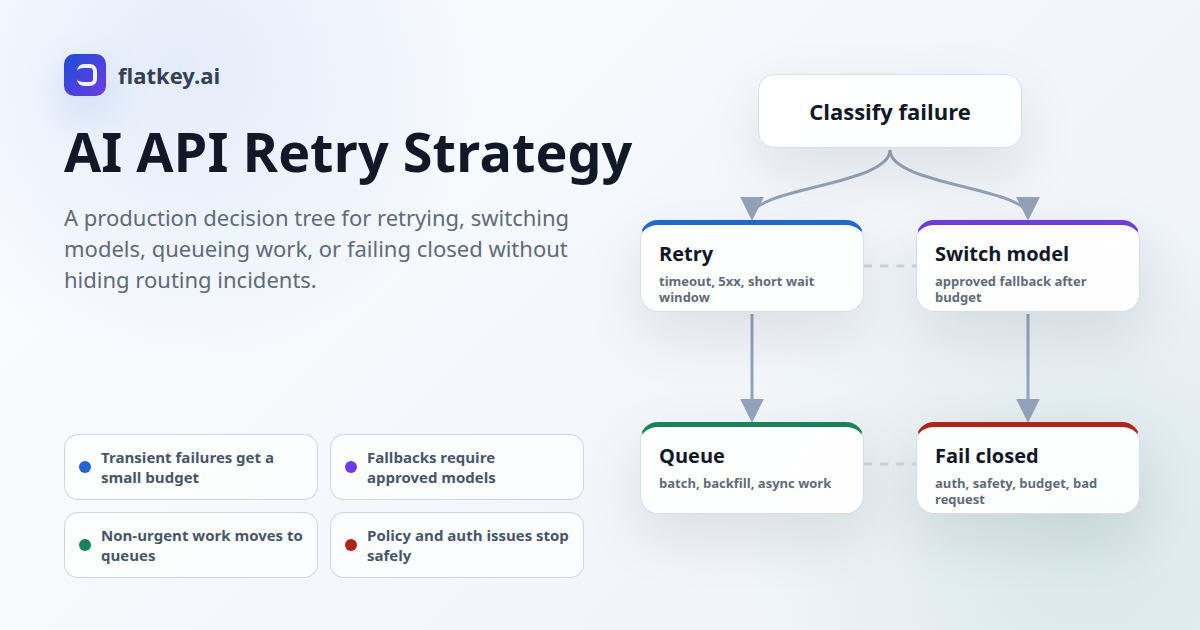
AI API Retry Strategy: When to Retry, Switch Models, Queue, or Fail Closed
Use an AI API retry strategy to decide when to retry, switch models, queue work, or fail closed without hiding quota, auth, or routing incidents.
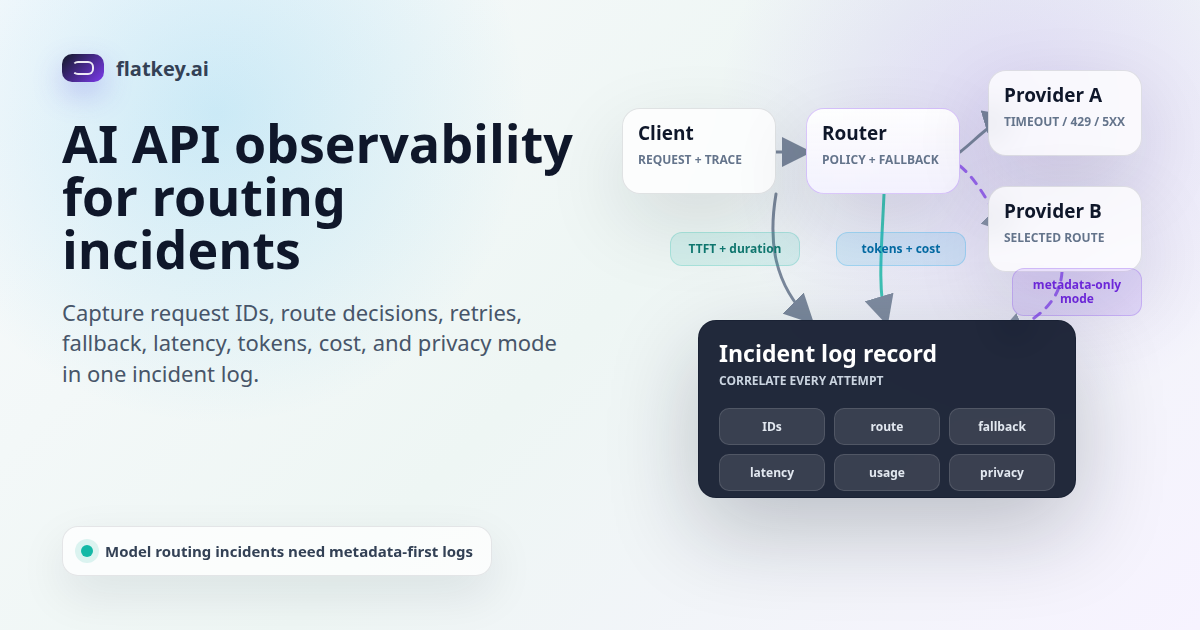
AI Observability Platforms: What They Do and How to Choose (2026)
AI observability platforms record prompts, tokens, cost, agent steps, and quality scores. Compare Langfuse, LangSmith, Arize, Datadog, Helicone, Braintrust, and Logfire on features and October 2026 pricing, with OpenTelemetry code.
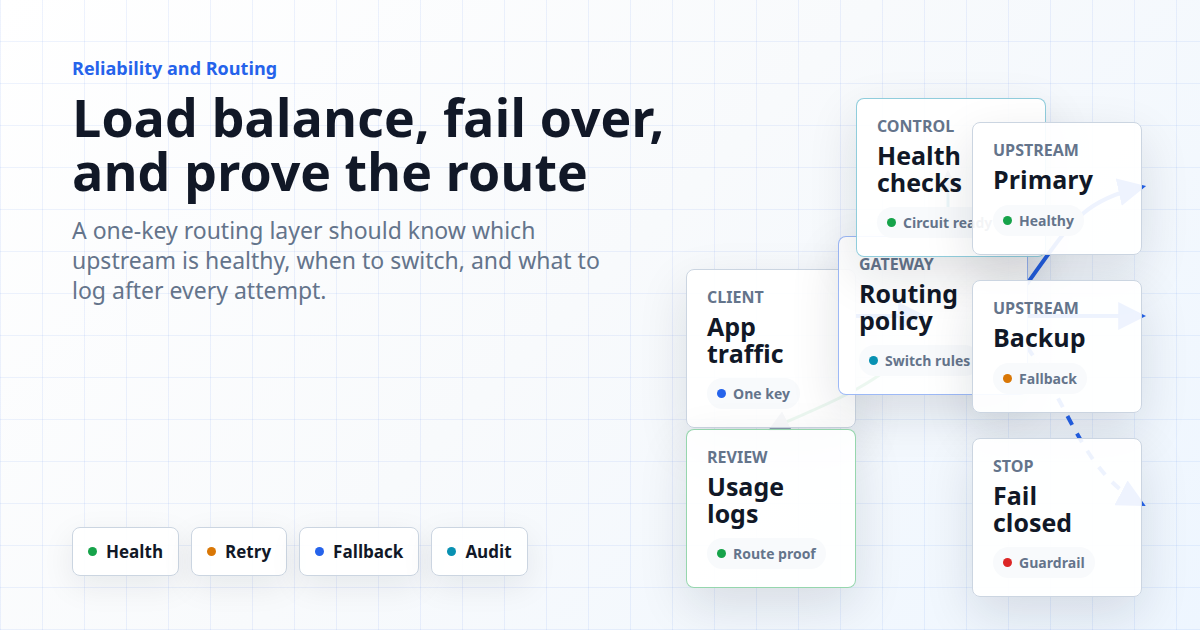
AI API Load Balancing and Failover Behind One Key
Plan AI API load balancing and failover with routing rules, health checks, retry paths, usage logs, quotas, rollback tests, and one-key gateways.
Build faster with one AI gateway.
Use flatkey.ai to manage models, keys, billing, and observability from one API platform.
Get started