
flatkey.ai Blog
Insights, product notes, and implementation guides for teams building on AI APIs.
AI Gateway Architecture
Latest articles in AI Gateway Architecture.
Read moreBase URL and SDK Migration
Latest articles in Base URL and SDK Migration.
Read moreCost, Billing, and Ops
Latest articles in Cost, Billing, and Ops.
Read moreEnterprise Controls and Trust
Latest articles in Enterprise Controls and Trust.
Read moreGateway Comparisons
Latest articles in Gateway Comparisons.
Read moreModel and Modality Playbooks
Latest articles in Model and Modality Playbooks.
Read moreReliability and Routing
Latest articles in Reliability and Routing.
Read moreTool Integrations
Latest articles in Tool Integrations.
Read more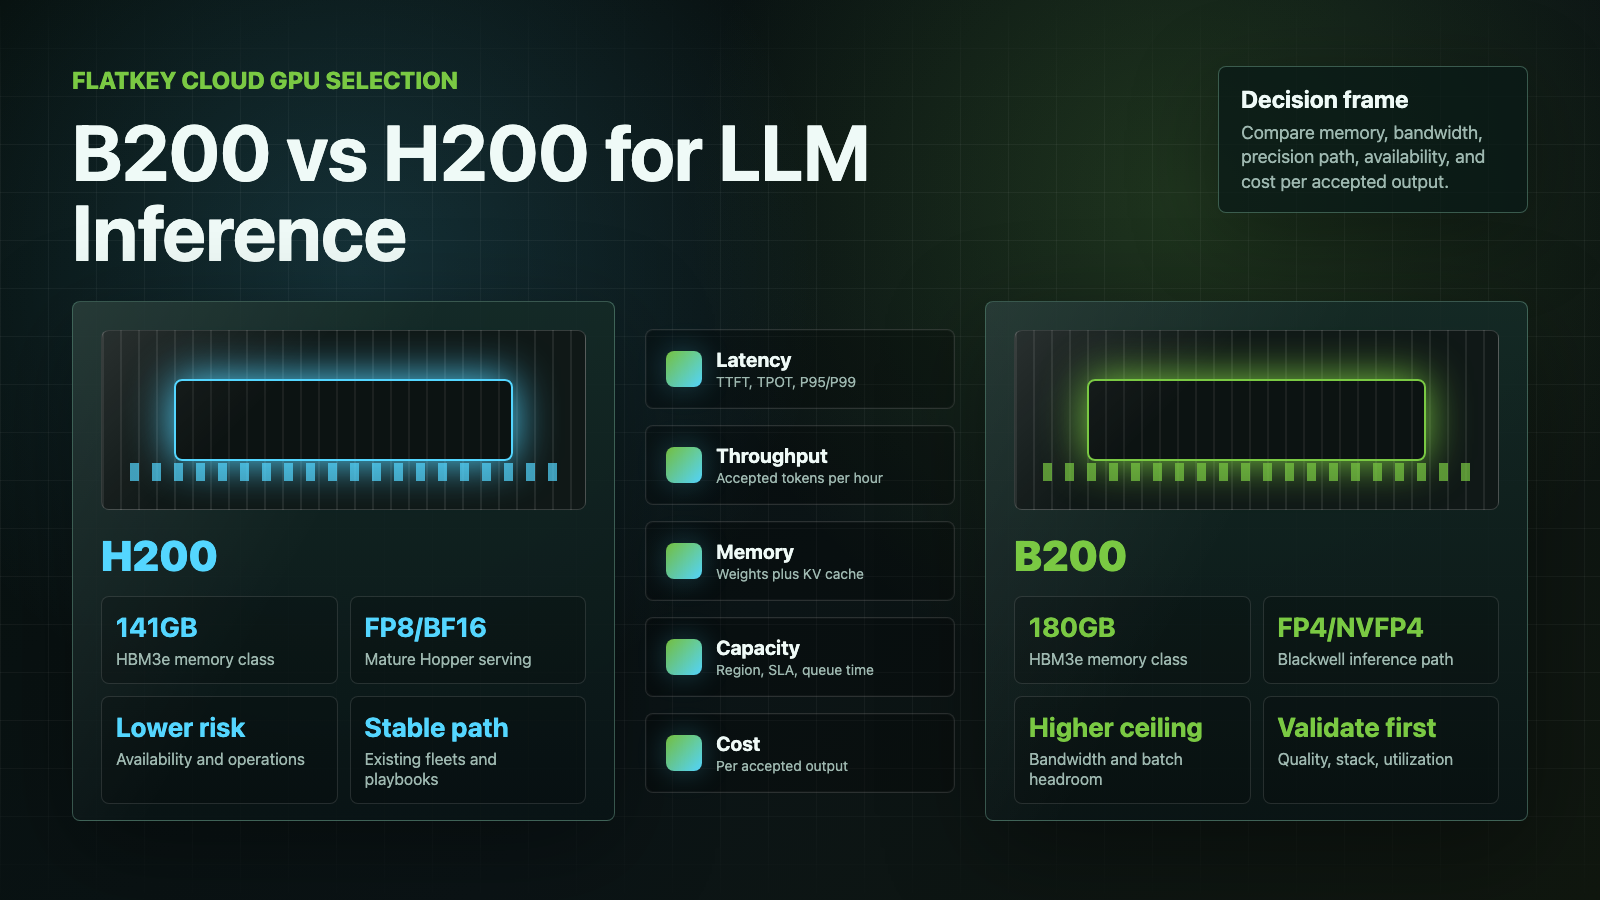
NVIDIA B200 vs H200: Which GPU Is Better for LLM Inference?
Compare NVIDIA B200 vs H200 for LLM inference by memory, bandwidth, precision support, DGX systems, cloud GPU availability, and cost per accepted output.
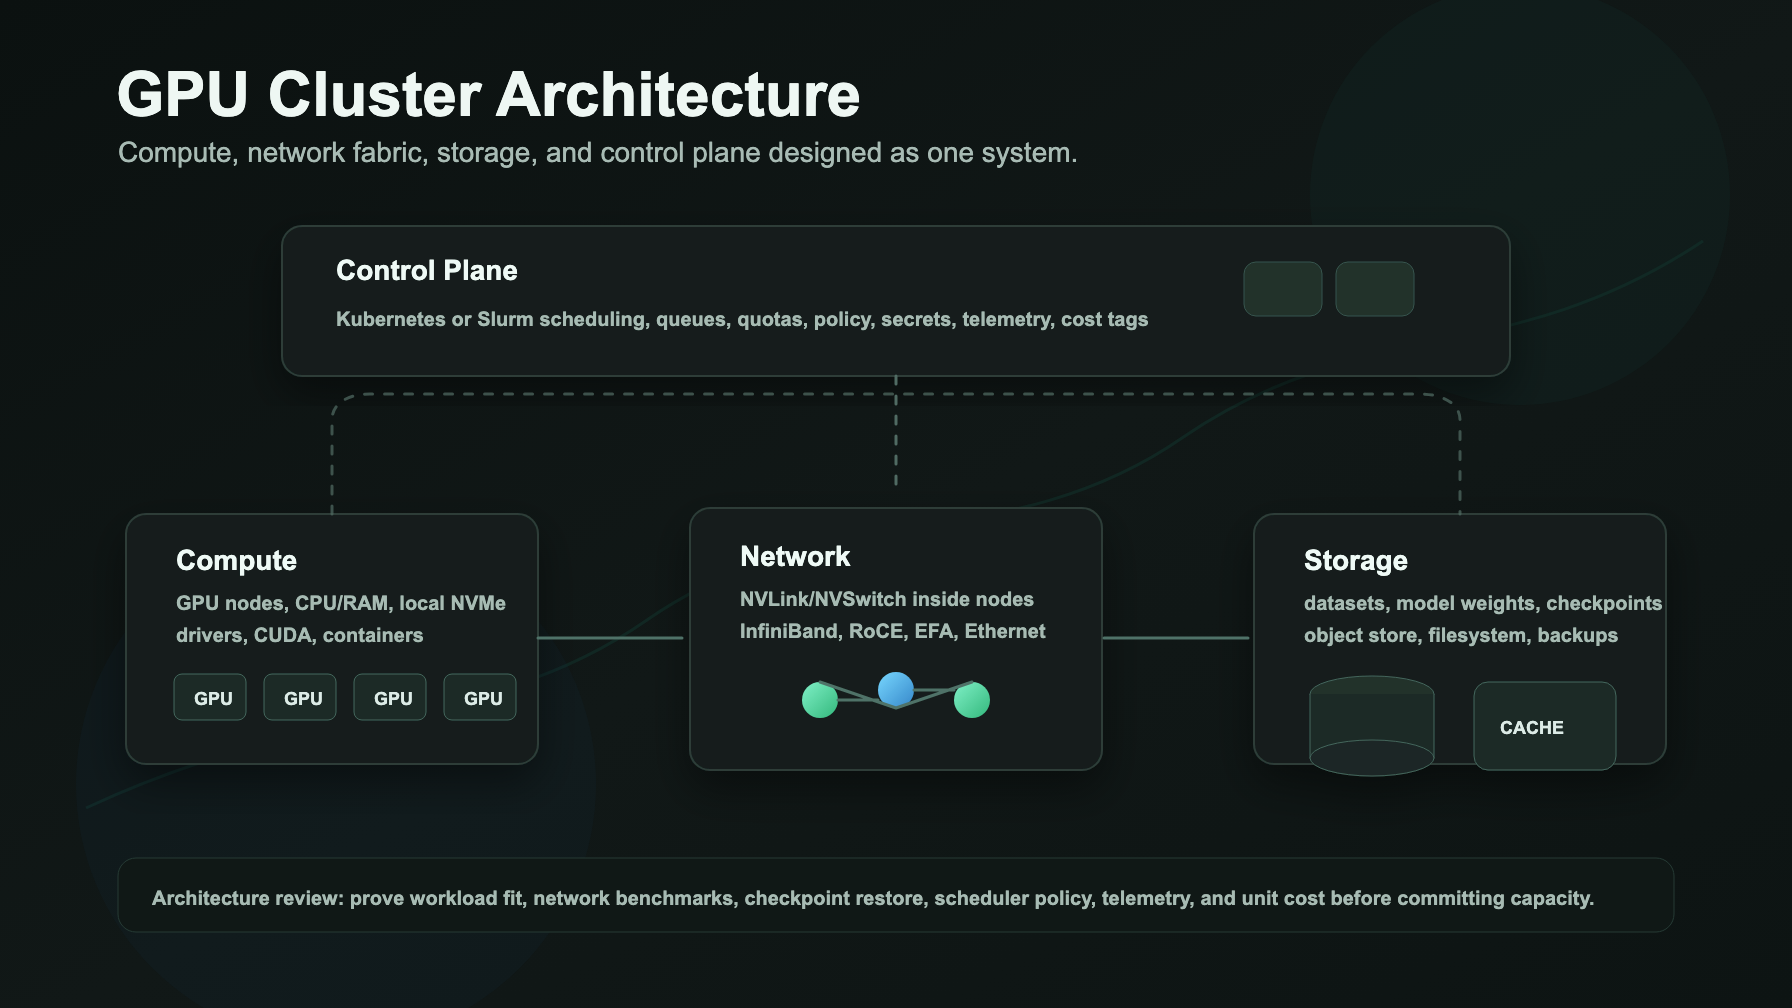
GPU Cluster Architecture: Compute, Network, Storage, and Control Plane
A practical GPU cluster architecture guide for compute nodes, network fabric, storage, Kubernetes or Slurm control plane, observability, and acceptance tests.
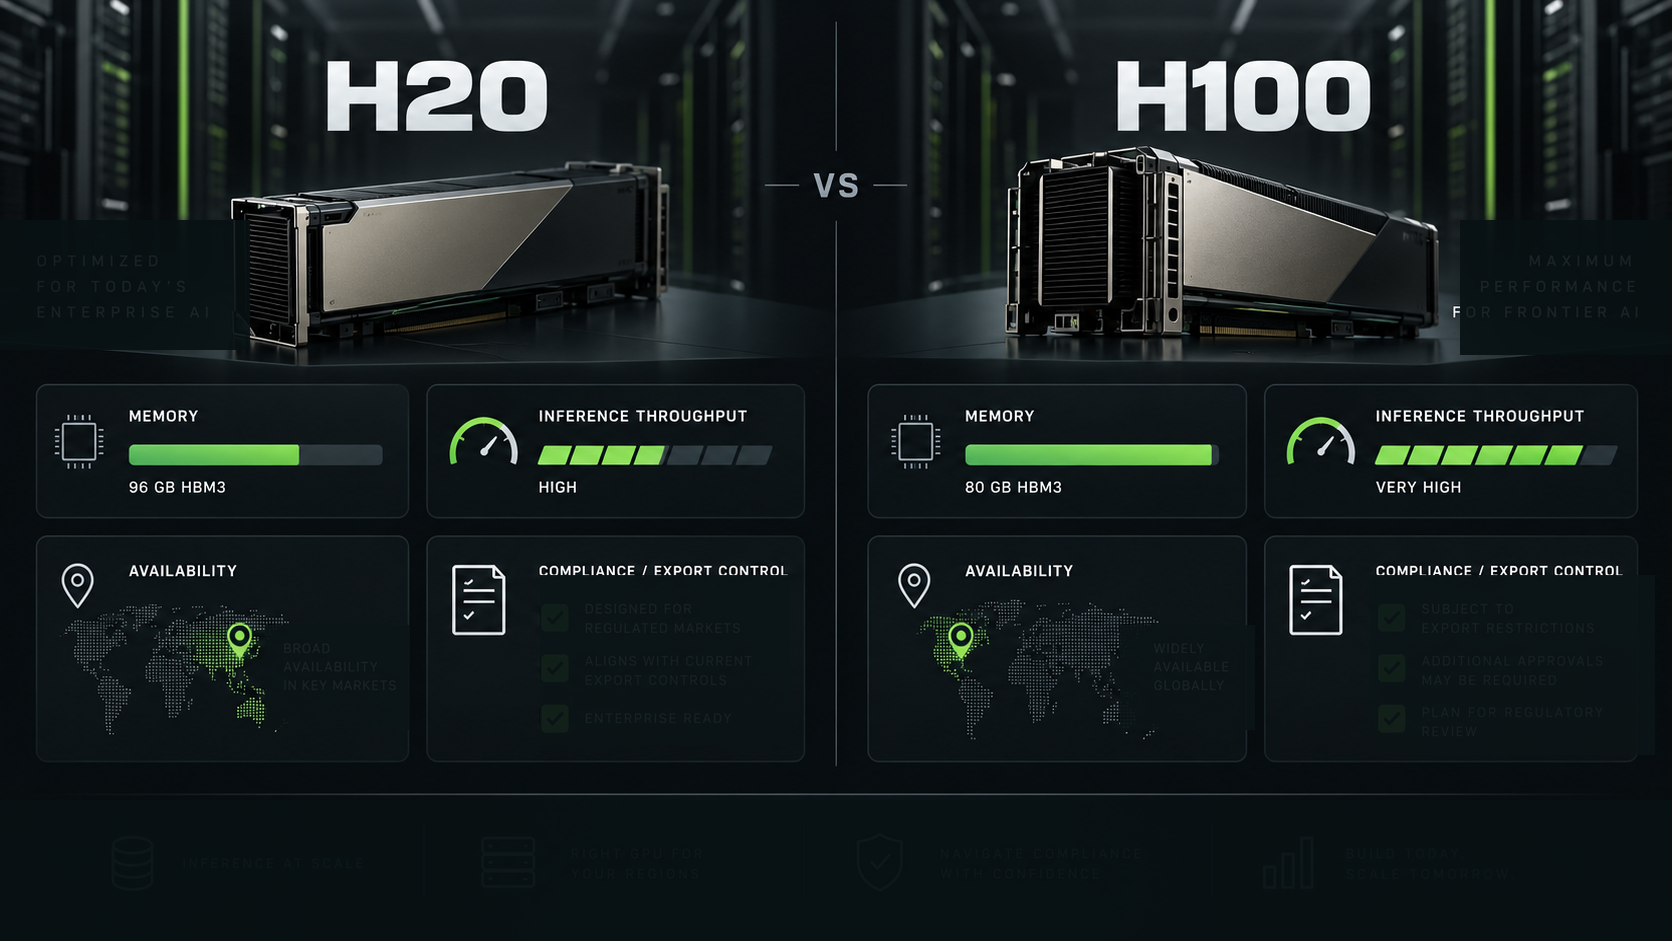
NVIDIA H20 vs H100: Inference, Memory, Availability, and Compliance
A practical H20 vs H100 comparison for enterprise AI teams, covering inference, memory, availability, export-control risk, and when H200 or model APIs are better baselines.
Best Cloud GPU Rental Platforms 2026: Price, Capacity, Network, and Support
A practical 2026 shortlist of GPU cloud platforms for AI teams, comparing price posture, capacity, network, support, and when a model API is the better baseline.
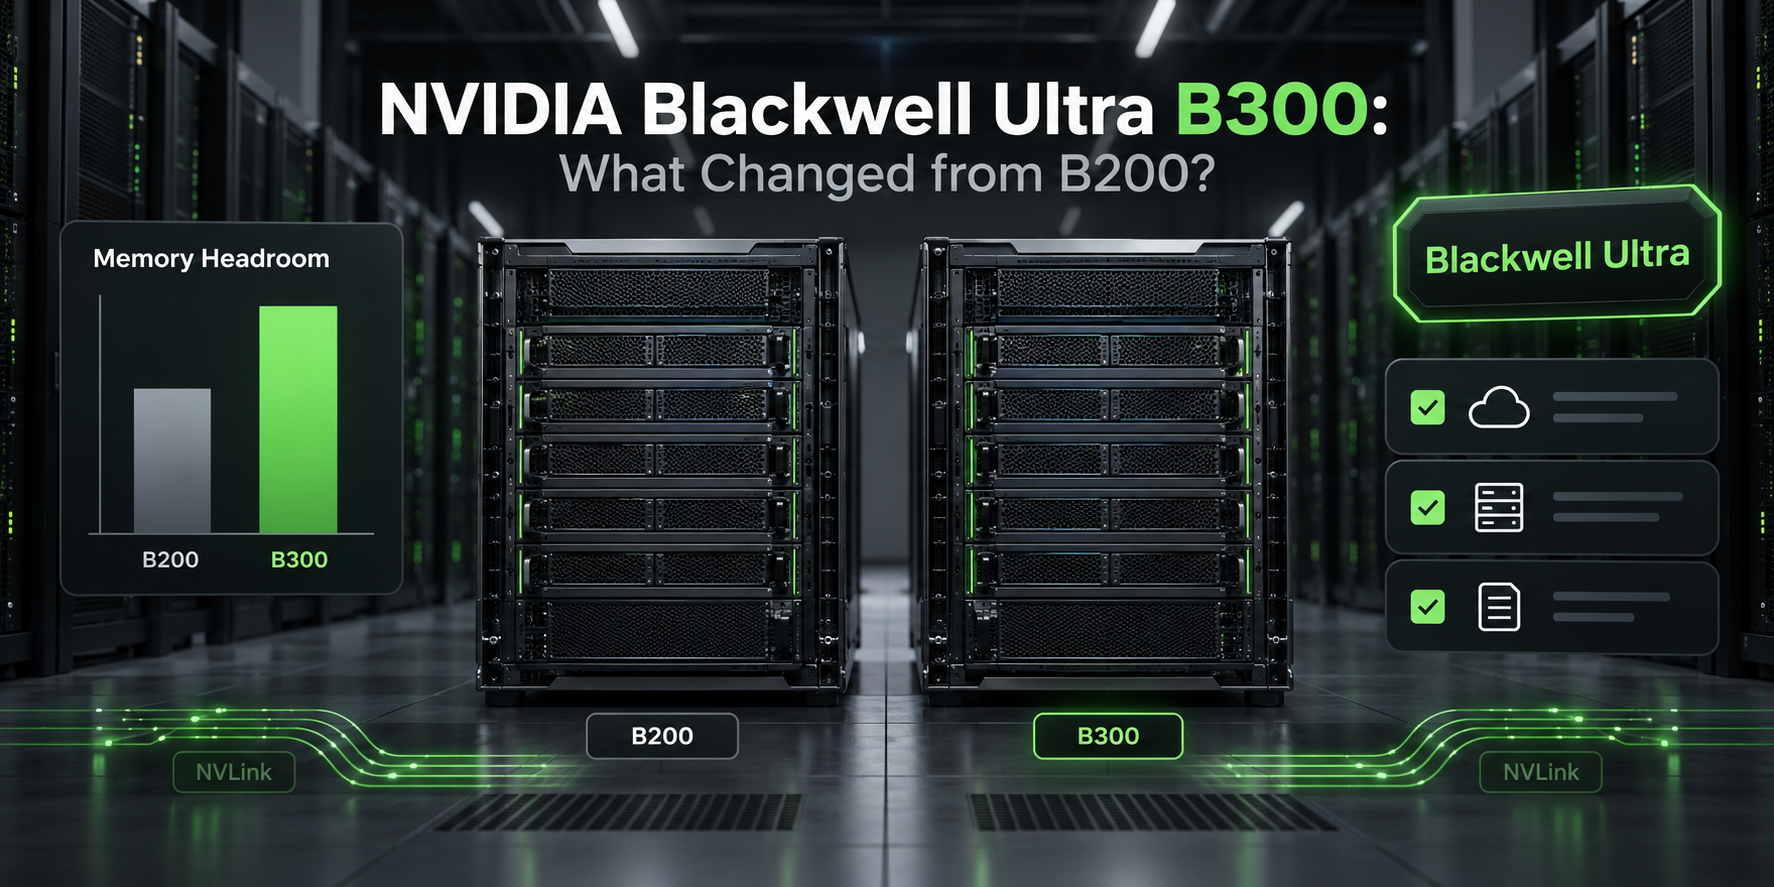
NVIDIA Blackwell Ultra B300: What Changed from B200?
A practical NVIDIA B300 Blackwell Ultra tracker for AI infrastructure teams comparing B300 specs, release status, price caveats, and workload fit against B200.
AMD MI455X and Helios: Architecture, Memory, and Availability Tracker
A buyer-focused tracker for AMD MI455X and Helios covering architecture, HBM4 memory, bandwidth, availability, vLLM readiness, provider questions, and model/API fallback strategy.
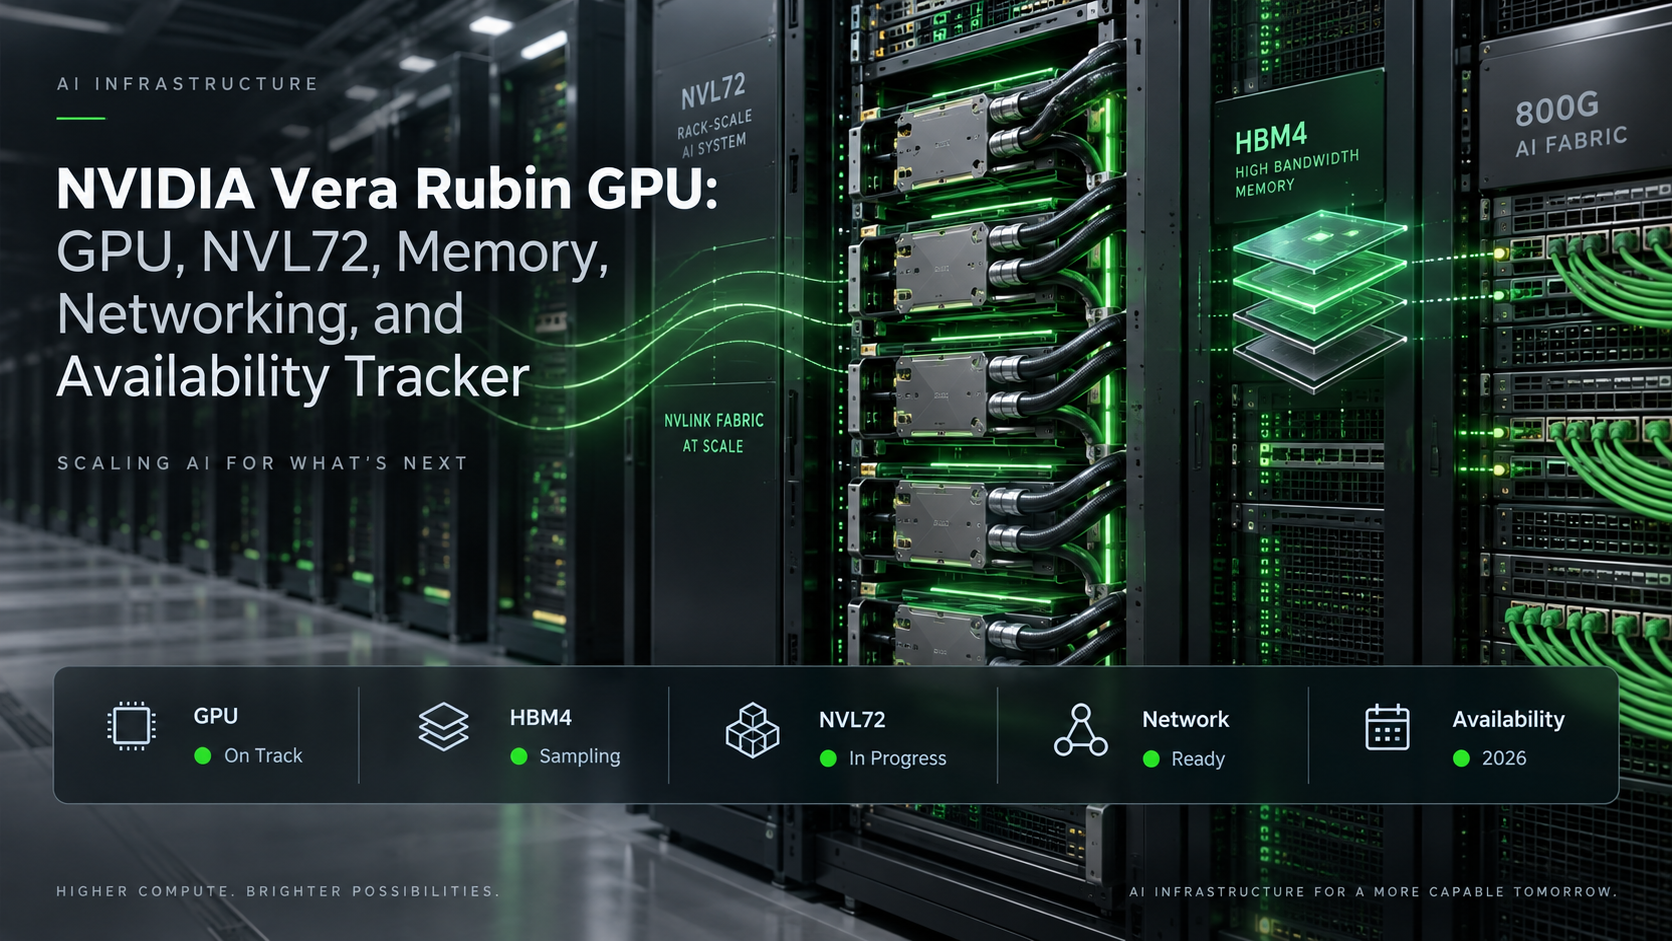
NVIDIA Vera Rubin GPU: GPU, NVL72, Memory, Networking, and Availability Tracker
A current tracker for NVIDIA Vera Rubin GPU specs, DGX Vera Rubin NVL72, HBM4 memory, networking, and availability milestones for cloud GPU buyers.
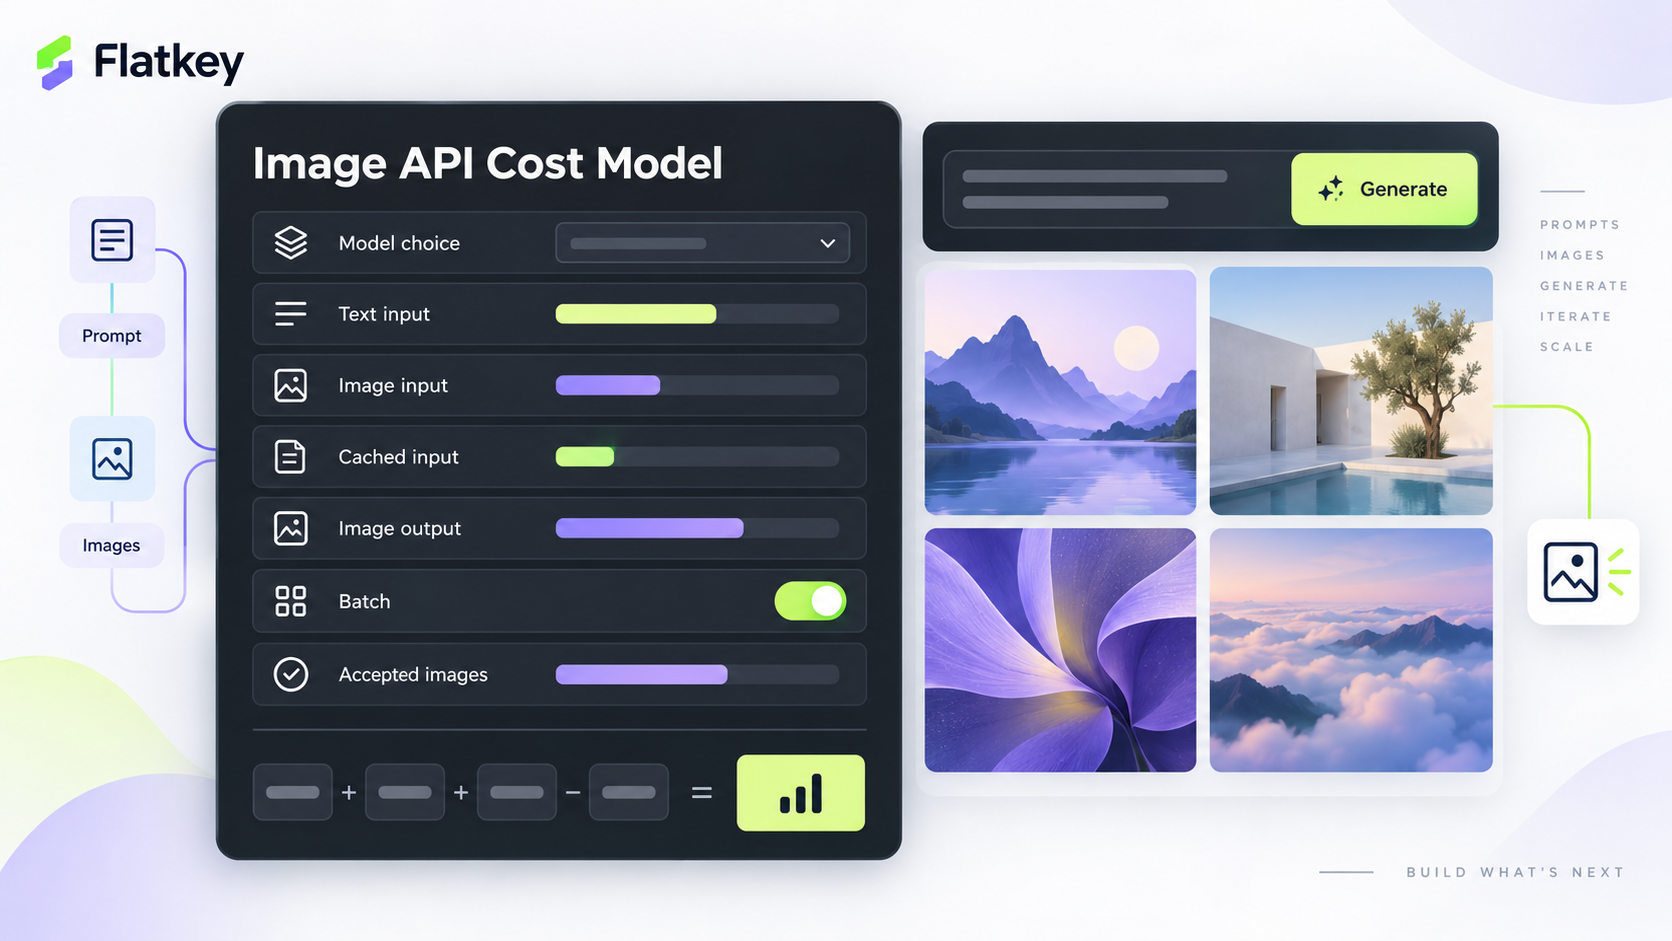
OpenAI Image API Pricing: GPT Image 2.5 Rates, Cost Formula, and Budget Controls
Learn how OpenAI image API pricing works for GPT Image 2.5, including token rates, cached input rules, partial images, Batch, and cost per accepted image.
GB200 vs B200: Grace Blackwell Superchip or x86 HGX?
Compare GB200 vs B200 for AI infrastructure procurement: Grace Blackwell rack-scale NVL72 systems, B200 HGX/x86 nodes, benchmarks, and TCO checks.
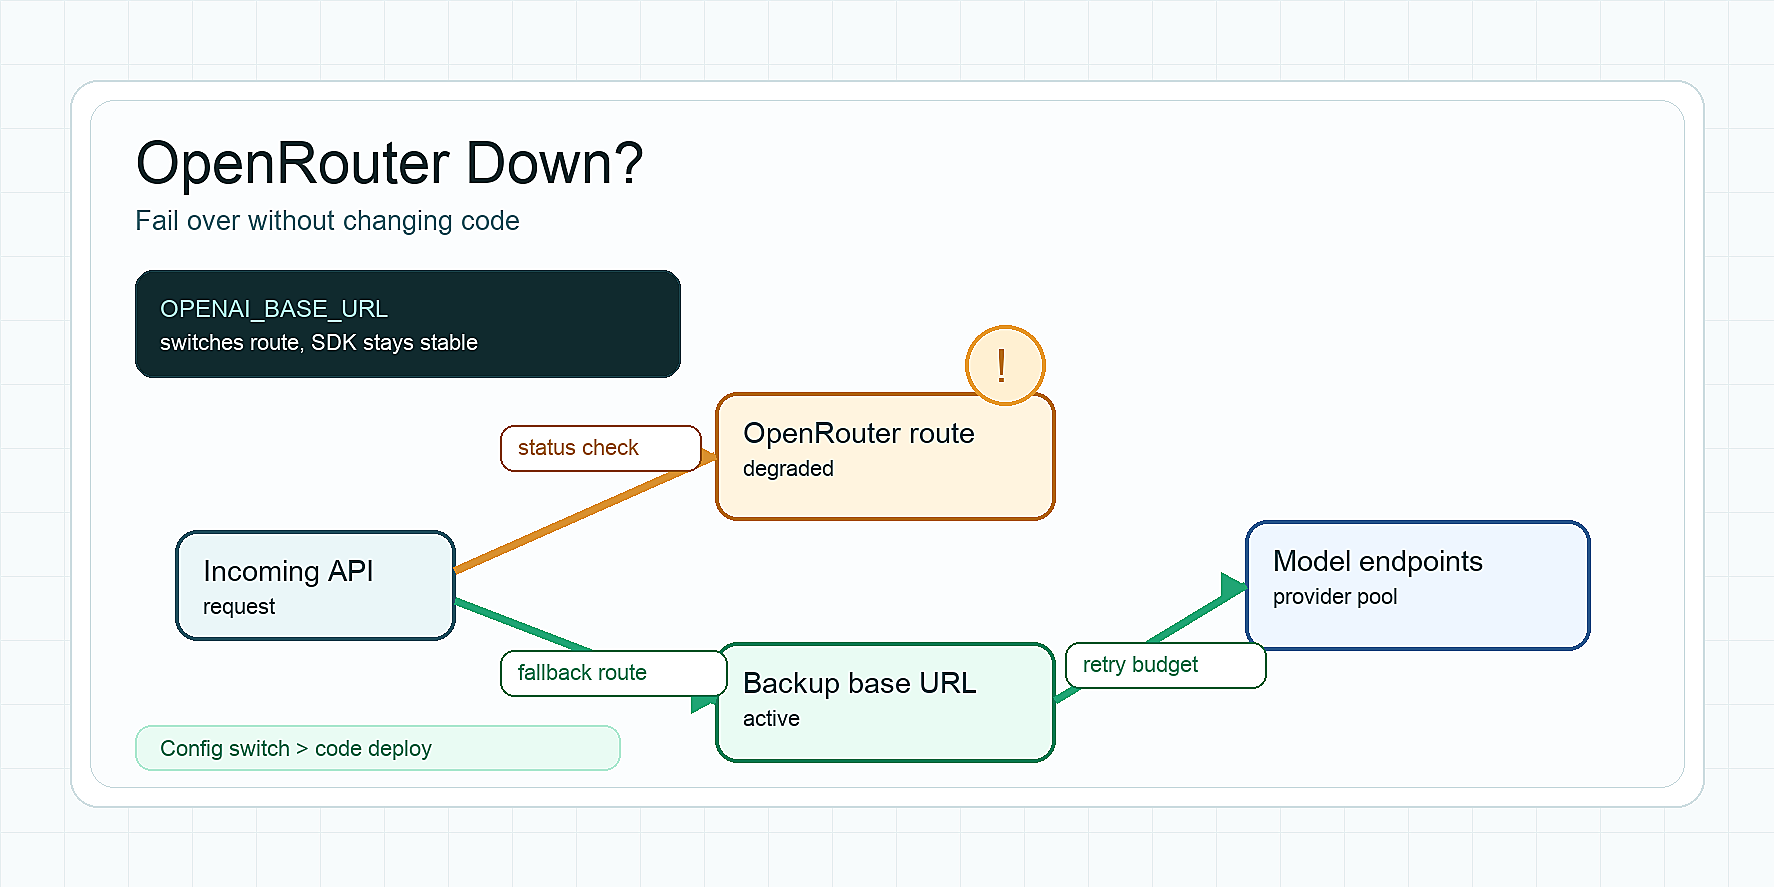
OpenRouter Down? How to Fail Over Without Changing Code
Check whether OpenRouter is down, separate provider errors from platform incidents, and fail over with base_url, retries, provider fallback, and model fallback.
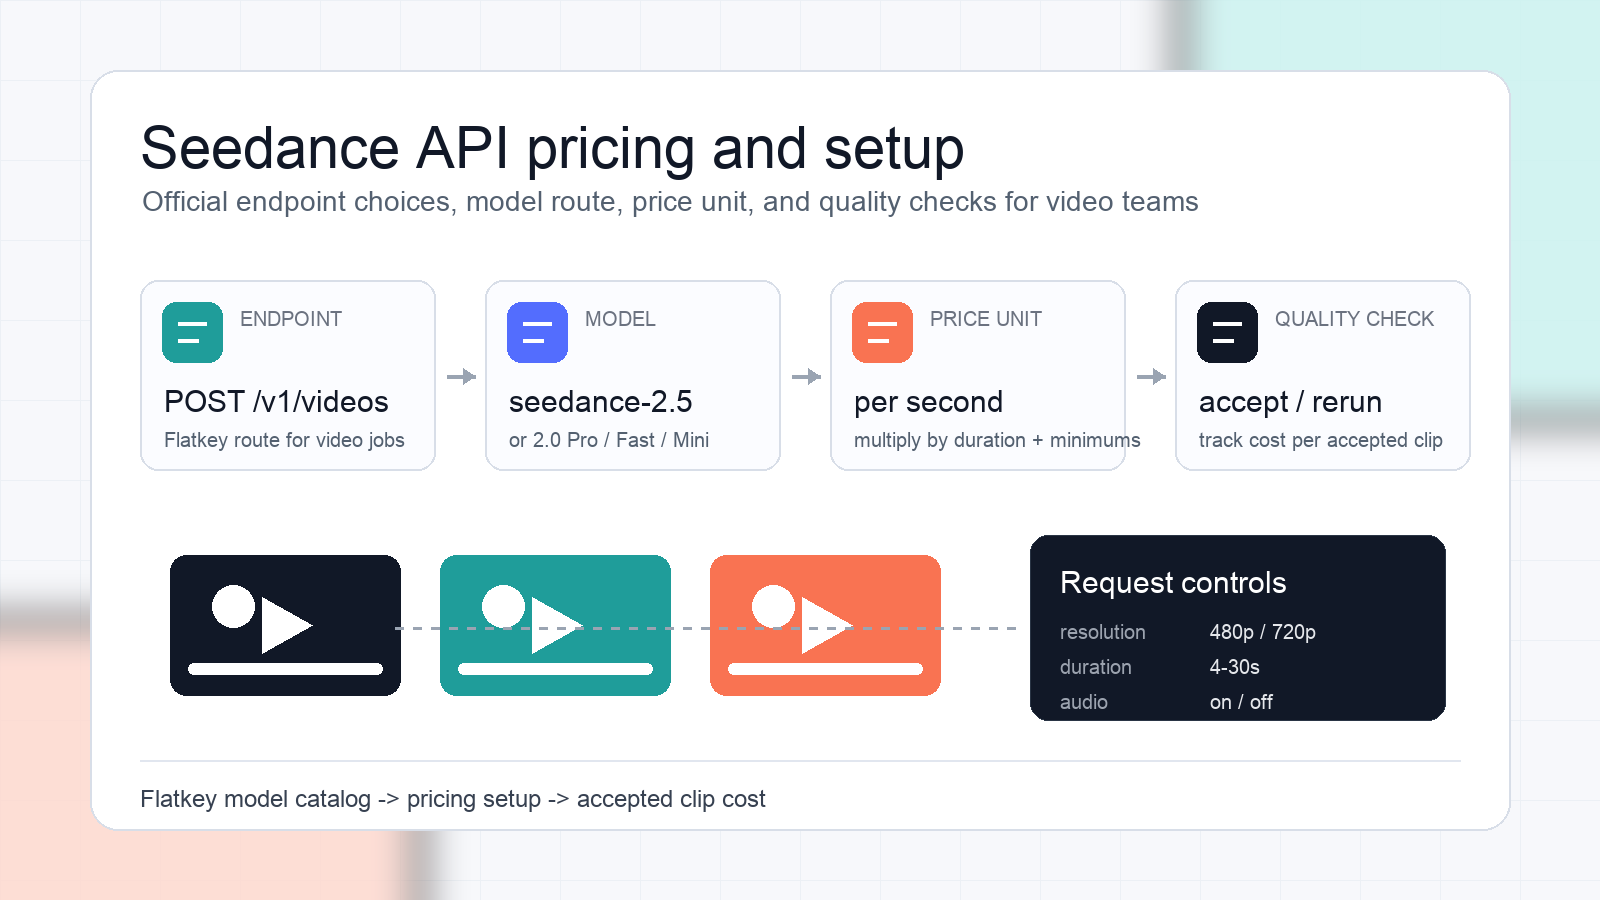
Seedance API: Pricing, Quality, and Setup for Official Endpoints
Compare official Seedance API endpoint options, Flatkey per-second pricing, setup steps, and quality checks for video generation teams.
What Is an AI Factory? GPU Clusters, Data, Models, and Operations
Learn what an AI factory is, how GPU clusters, data pipelines, models, inference, governance, and operations work together, and when model APIs can replace direct GPU ownership.
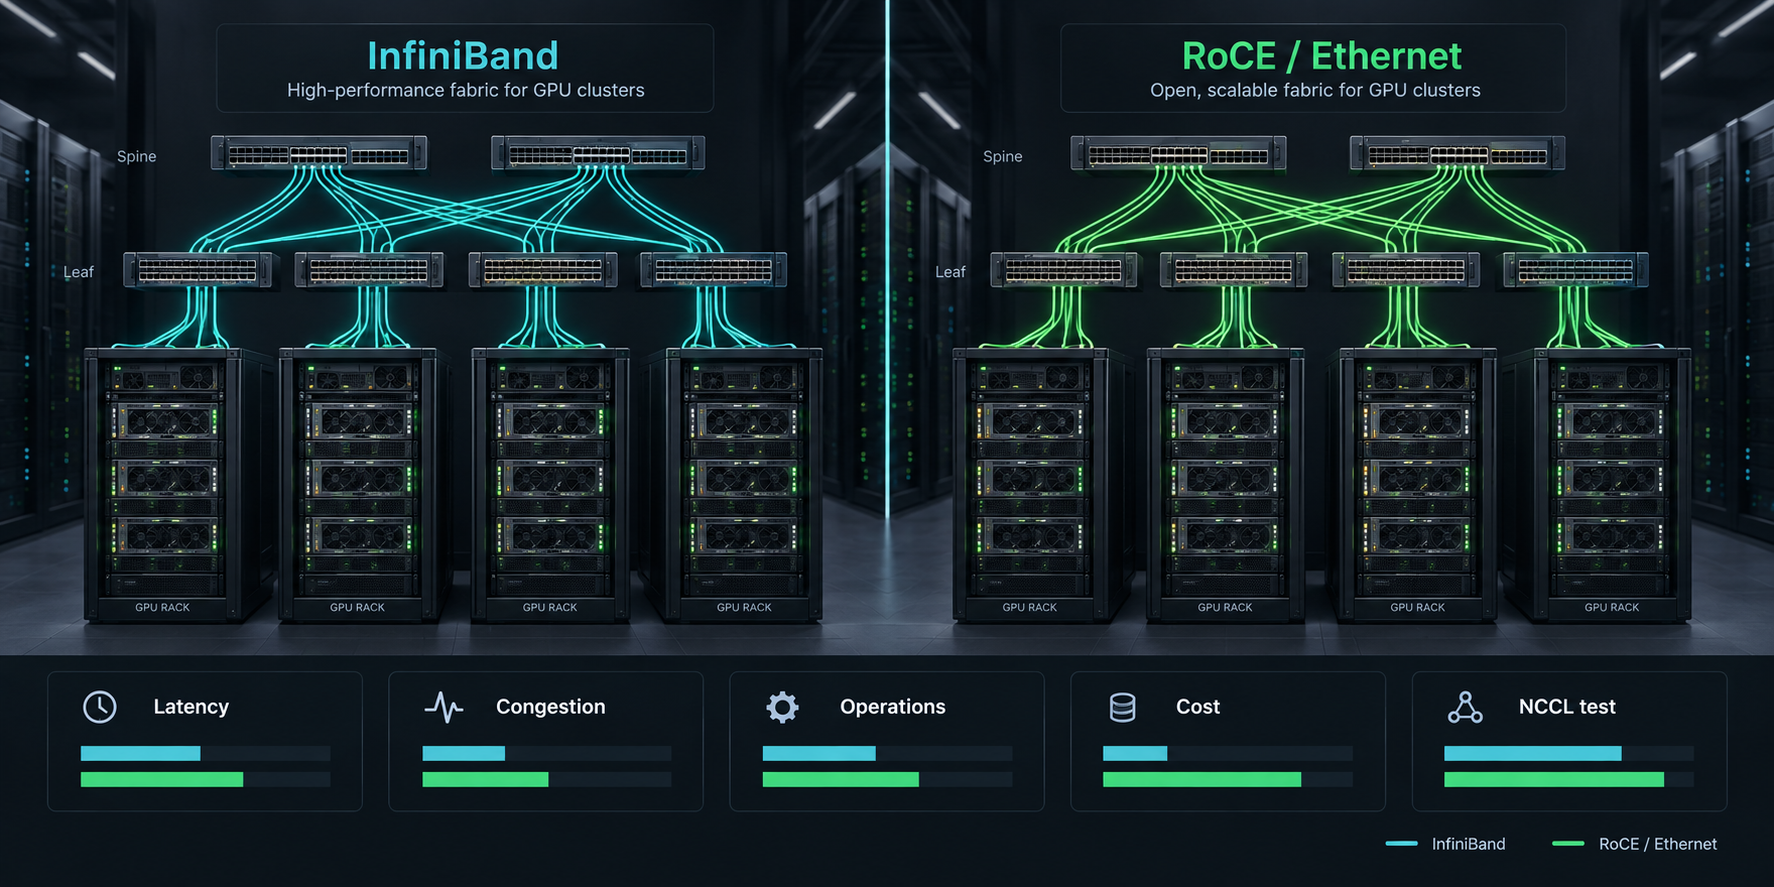
RoCE vs InfiniBand for GPU Clusters: Latency, Operations, and Cost
Compare RoCE and InfiniBand for multi-node GPU clusters with a practical decision matrix, NCCL acceptance test, cost model, and procurement checklist.
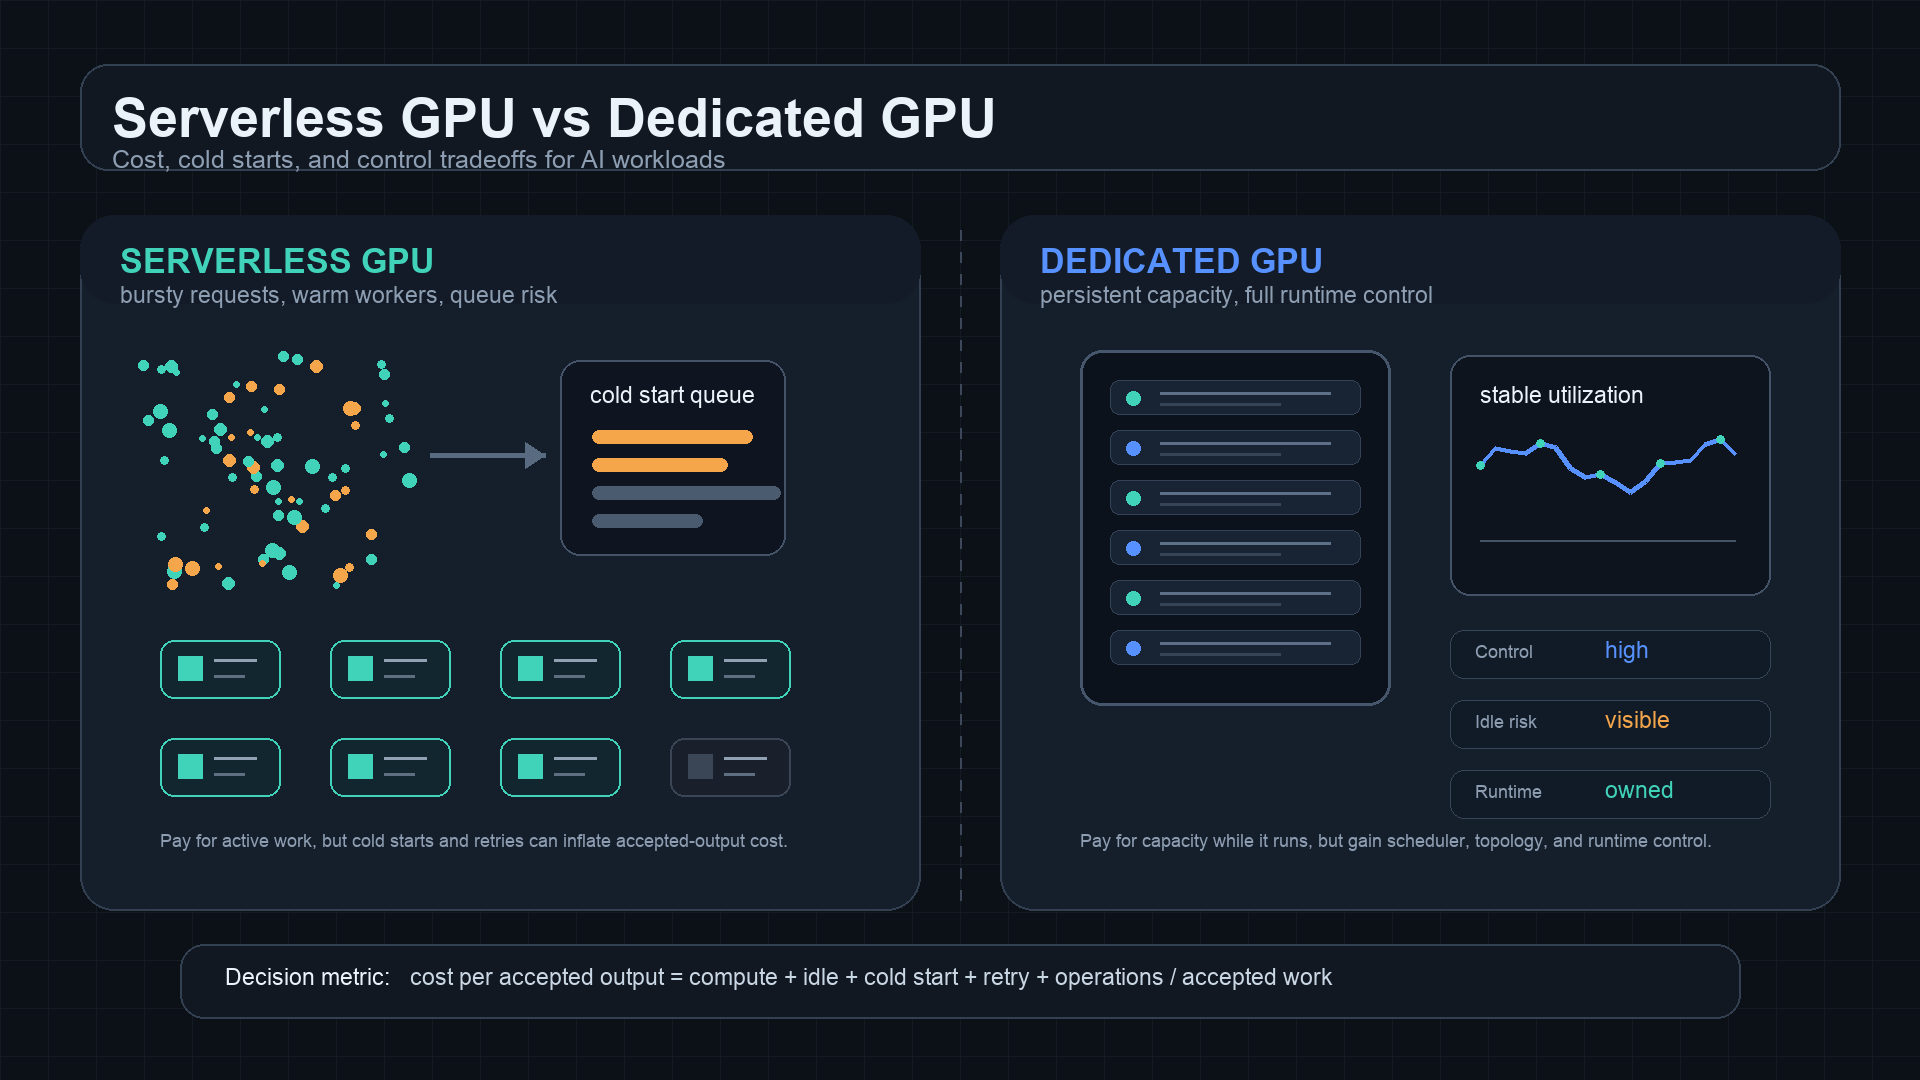
Serverless GPU vs Dedicated GPU: Cost, Cold Starts, and Control
Compare serverless GPU vs dedicated GPU by cost per accepted output, cold starts, idle capacity, autoscaling, and operational control.

AI Image Generation API Pricing Comparison: GPT Image, Gemini, Imagen, and fal
Compare image generation API pricing across GPT Image, Gemini Image, Imagen, and fal routes by normalizing billing units into cost per accepted image.
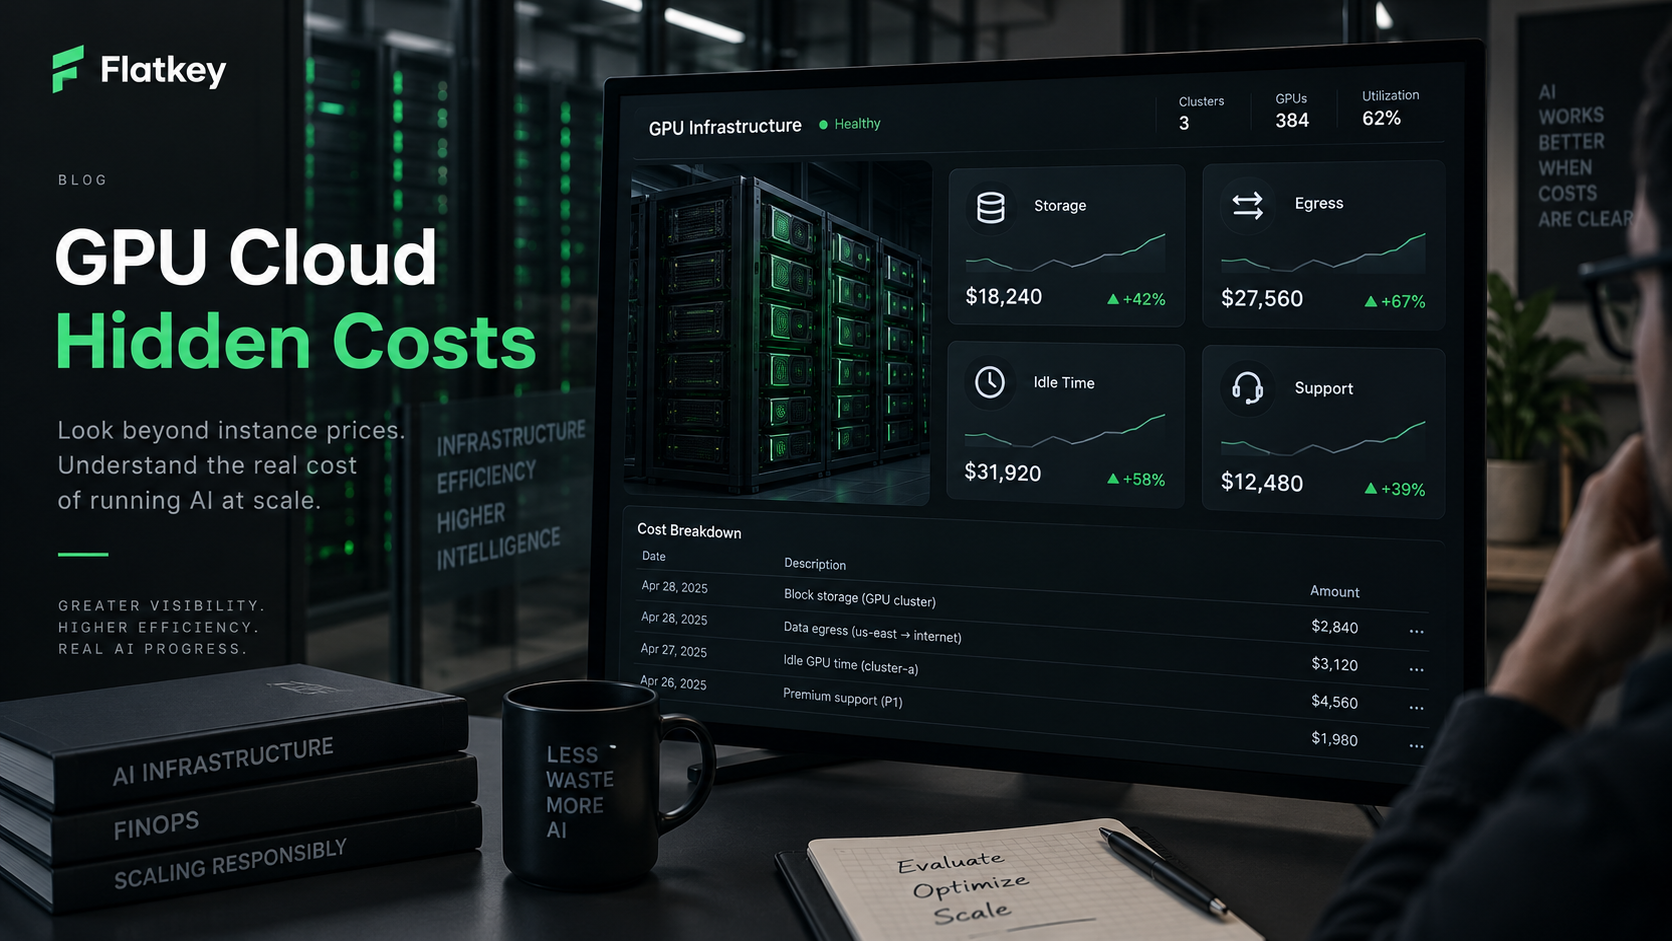
What Are the Hidden Costs of Cloud GPU Services? Storage, Egress, Idle Time, and Support
A practical cloud GPU TCO guide for finding storage, egress, idle time, failed-job, support, networking, and operations costs before the invoice arrives.
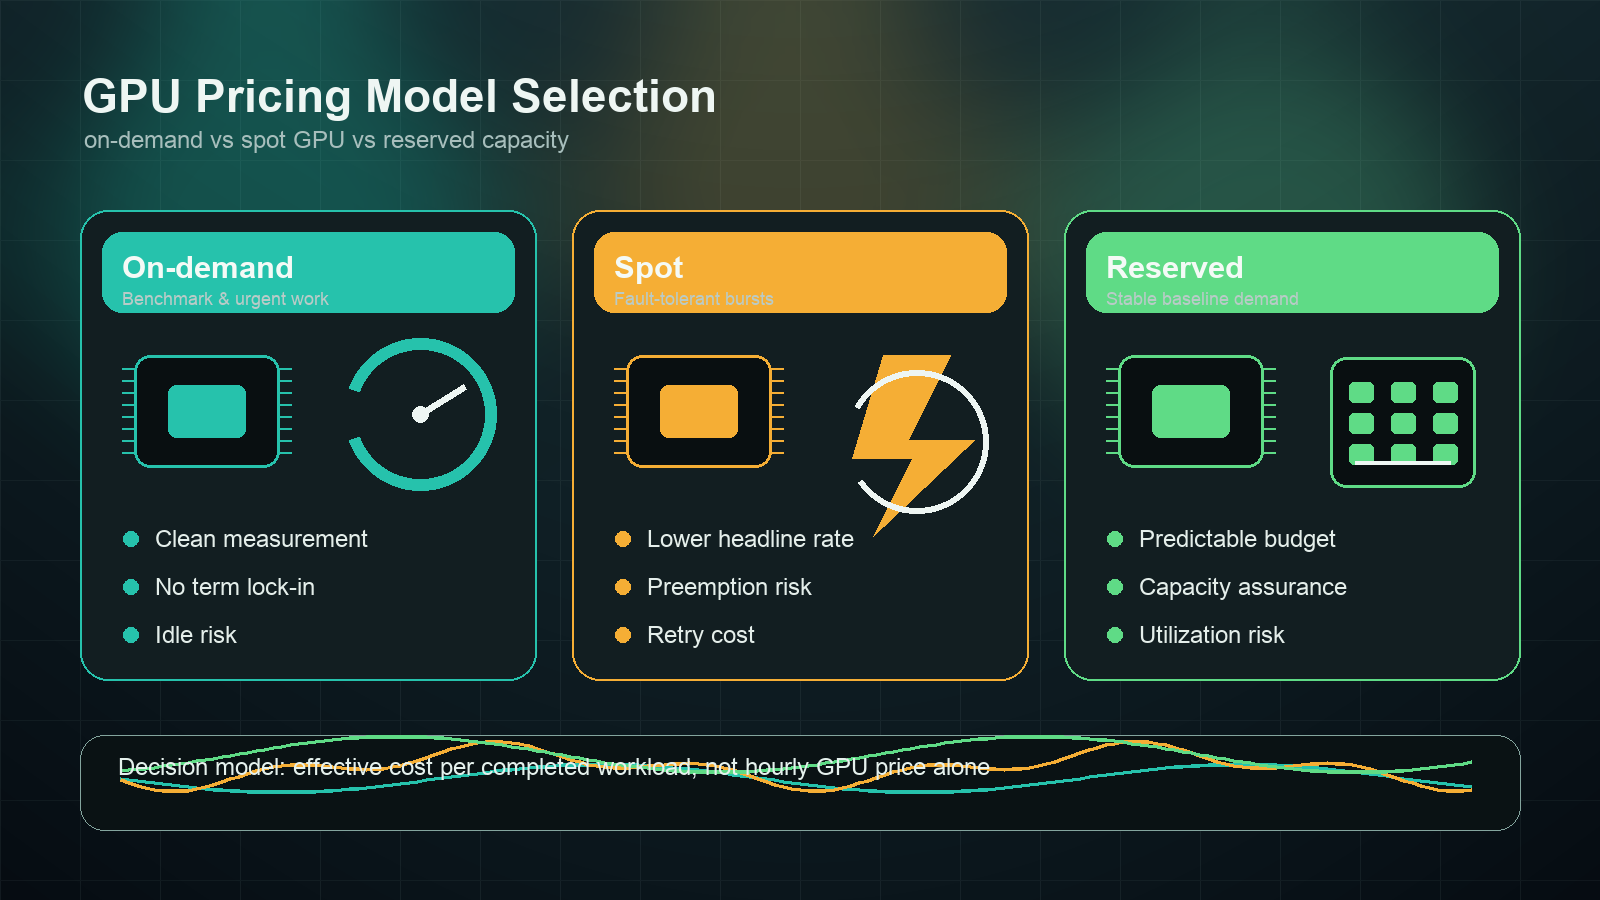
On-Demand vs Spot vs Reserved GPU Pricing: Which Model Fits Your Workload?
A workload-driven framework for choosing on-demand, spot, or reserved GPU capacity without confusing the listed hourly rate with completed workload cost.
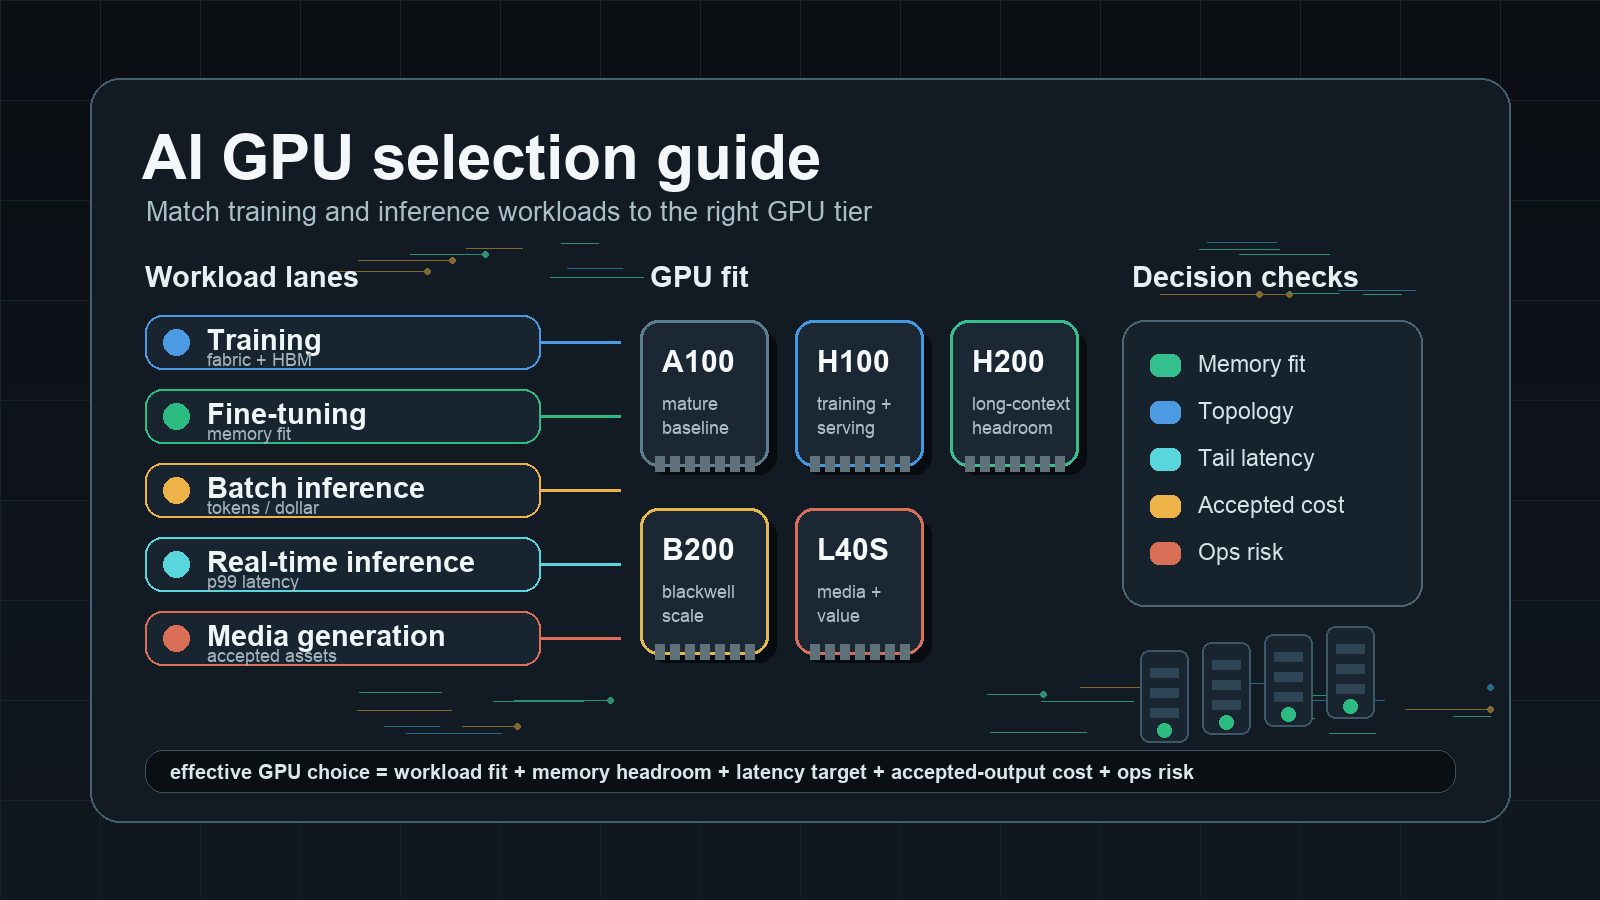
AI GPU Selection Guide: Match Training and Inference Workloads to the Right GPU
A practical AI GPU selection guide for teams matching training, fine-tuning, LLM inference, media generation, and evaluation workloads to the right GPU and capacity model.
Build faster with one AI gateway.
Use flatkey.ai to manage models, keys, billing, and observability from one API platform.
Get started